


Four Outcomes That Get an LLM Gateway Funded
Build the internal business case for an LLM gateway on four quantifiable outcomes: total spend reduction, cost per call, tail latency, and developer speed.

Direct answer: Build the internal business case for an LLM gateway on four quantifiable outcomes: total spend reduction, cost per call, tail latency, and developer speed.
The position
An LLM gateway is not bought on capabilities; it is funded on four outcomes — total spend, cost per request, performance under load, and time to ship the next AI feature. Write the case in that language, with a number on each line, or it stalls at the first finance review.
Most gateway pages sell mechanisms. The person who signs the purchase order is not buying a mechanism. They are buying a change to a line on a spreadsheet and a change to how fast the team ships, and they will approve neither unless you have written both down in their units.
This post is the internal case, in the order a VP of Engineering, CTO, or Head of Platform actually has to pitch it. Every claim below is either arithmetic you can redo or a link to a page you can check. If you are still establishing what the category even is, start with what an LLM gateway is or the managed LLM gateway itself, and come back.
What we were asked for instead
The request we keep getting — and keep declining — is the feature matrix. Send us the capability grid, twenty rows deep, with checkmarks across four vendors. Procurement wants it, and it is a reasonable thing to want.
Stated at its strongest, the case for the matrix is solid:
| Their argument | Why it holds up |
|---|---|
| It is comparable | Every vendor answers the same twenty questions in the same order |
| It is auditable | A checkmark is a claim someone can be held to later |
| It is delegable | An engineer who has never used the product can fill it in |
| It de-risks the pick | A missing capability found in month six is a migration; found in the grid, it is a filter |
All true. We fill these grids in when asked, and we do not lie in them. But a completed matrix answers the question "what does it do?" and the budget owner asked "what changes for the business?" Those are different questions, and the second one is the one that releases money.
What that would cost you
Here is the concrete failure mode, and it is not hypothetical. A matrix-led case reaches finance and gets one of two responses: "we already have observability" or "come back with a number." Both are correct responses to a document that lists capabilities and forecasts nothing.
The cost of that is measured in quarters, not dollars. Meanwhile:
- The spend keeps growing unattributed. Every month without a gateway is a month whose provider invoice cannot be split by feature, team, or customer. That history is not reconstructible later — you can start attributing tomorrow, but you cannot attribute last quarter.
- The next incident has no containment. Without per-key ceilings, a retry loop shipped on a Friday is a budget event, not a log line. Four ceilings every request passes is the shape of what you are missing.
- Each new model is a project. Teams without a single seam integrate providers one at a time, which means the cheapest qualifying model for a workload stays unadopted because adopting it costs two sprints.
- The matrix ages badly. Capability grids are true on the day they are filled in. Prices and model families move faster than procurement cycles — every hyperscaler publishes its rates on a page it revises without notice, Azure OpenAI Service and Google Vertex AI among them — so the grid is stale before the contract is signed.
A capability list has no unit. An outcome does. Rewrite the case as four outcomes and the same facts start moving.
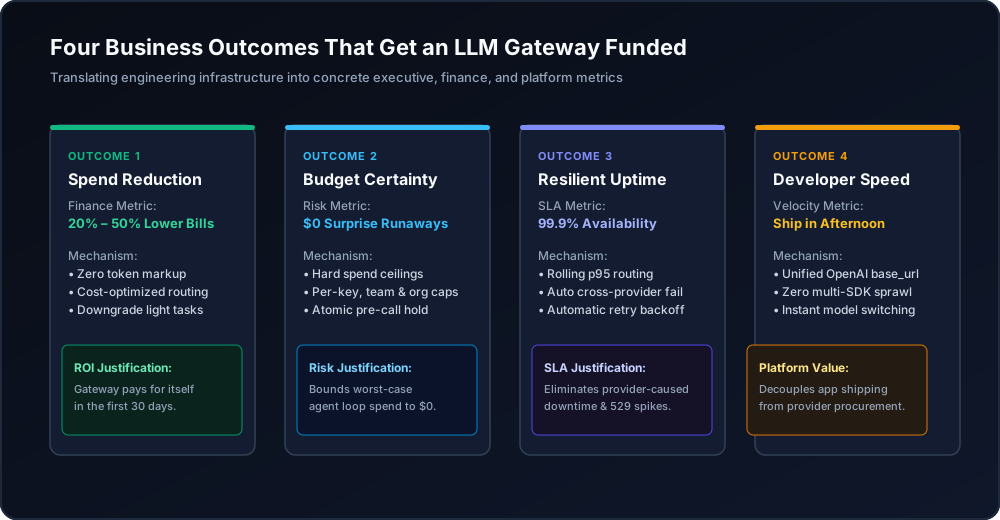
Figure 1: The four core business outcomes: spend reduction, budget certainty, resilient uptime, and developer speed.
The four outcomes, mapped
Each row starts in the language of the person who signs. Finance reads the middle column. Engineering validates the right one. Nobody has to translate "OpenAI-compatible endpoint" into "we will ship faster" — the translation is already done.
| Outcome | What it means to the business | The mechanism behind it |
|---|---|---|
| Lower total spend | Less money leaves the company for AI, platform overhead included — not just a cheaper token price | Pay as you go at a 0% platform fee, with credit purchases charging exactly the credits bought ($5 costs $5.00, $100 costs $100.00); usage settles at provider list price with 0% markup; every governance feature on every account, never gated |
| Lower cost per request | The same quality of answer for fewer cents, measured not estimated | Route each request to the cheapest qualifying model; exact per-call cost on the x-nr-request-cost response header |
| Performance under load | Fewer outages, and a bad provider hour that does not become a bad product hour | Automatic provider fallback, plus per-key, per-team and per-organisation ceilings that contain blast radius |
| Faster shipping | New models and new AI features land in days, not sprints | One OpenAI-compatible key in front of every model in your live catalog — a new model is a string, not an integration |
Capabilities described here are nRouter's, verified 2026-08-23. SOC 2 Type II is in progress, not certified — see the trust page. "Type II" here means an attestation over a period against the AICPA's trust services criteria, which is worth knowing before a procurement call treats the phrase as a checkbox.
The memo that gets funded is one page and follows this order:
- The number today. Last month's provider invoice, total, and the fraction you cannot attribute to a team.
- The four outcomes, each with the target you will hit and the date you will measure it.
- The blast-radius incident you are preventing, named, with its plausible cost.
- The migration cost, honestly: a base URL, a key, and a rollout window.
- The exit, honestly: what it takes to leave, and how long.
Line 5 is the one people skip and the one that wins the room. A buyer who has been told the exit cost believes the other four lines.
Outcome 1 — total spend: zero platform fee and zero token markup
Token prices are set by the provider, on the provider's own page — OpenAI's is the reference most teams price against. Your vendor choice does not move them. What a vendor choice does move is the overhead layered on top — and that overhead is where gateway pricing quietly differs.
Work the arithmetic for a team spending $20,000/month with providers. nRouter sells one plan, pay as you go, at a 0% platform fee: purchasing $20,000 of credits charges exactly $20,000.00, nRouter absorbs the card-processing cost, and usage settles at the served model's exact list price with 0% markup. Every dollar of credits buys a dollar of model inference. Current numbers sit on the pricing page.
The number is public and does not need a sales call: with a 0% platform fee and 0% token markup, overhead is $0. No subscription plan is sold (existing subscribers keep theirs), so there are no subscription tiers to evaluate.
The second half of "total spend" is what you are not charged extra for. Guardrails, A/B tests, prompt management, evals and per-team budgets are on every account. That is a deliberate commercial position, argued in Every Feature on Every Plan: No Fee, No Gate. For a finance reviewer, it removes the line item that usually appears in month four labelled "enterprise upgrade to enable the thing we already assumed we had."
One honest note for the memo: paid evaluation usage starts with a card and a real $5 minimum charge (charging exactly $5.00 for $5.00 of credits). Put that line in the memo rather than discovering it in the procurement call.
Outcome 2 — cost per request: you cannot cut what you cannot attribute
"Reduce AI costs" is a different claim from "spend less money," and conflating them is why so many cases fall apart under questioning. Total spend can fall because usage fell. Unit cost falling means you got the same work done for less, and proving that requires per-request cost attached to the request.
Every response carries the exact cost of that call on x-nr-request-cost, paired with x-nr-cost-status. When the cost is not knowable, the header is absent and the status reads unpriced — never a fabricated $0, for the reasons in cost honesty.
from openai import OpenAI
import os

client = OpenAI(
    base_url="https://api.nrouter.ai/v1",
    api_key=os.environ["NROUTER_API_KEY"],
)

resp = client.chat.completions.with_raw_response.create(
    model="claude-sonnet-5-5",
    messages=[{"role": "user", "content": prompt}],
)

cost = resp.headers.get("x-nr-request-cost")          # absent when unpriced
status = resp.headers.get("x-nr-cost-status")         # "exact" | "unpriced"
With that number on the request you can do the thing the finance case actually needs: tag spend by team, customer and feature (attribution tags), then find the model that is quietly expensive rather than the one that is obviously popular (cost vs usage). Routing cheap traffic to a cheaper qualifying model is the lever everyone reaches for first; attribution is what tells you which traffic is cheap. Do them in that order.
Forecasting before you have data is guesswork, so use the cost calculator for the memo's first draft and replace its numbers with measured ones within a month.
Outcomes 3 and 4 — performance and shipping speed come from the same seam
These read as two outcomes and are one mechanism. Because every request passes through one place, you can change what happens to it without changing application code — and that single property produces both the reliability story and the velocity story.
Performance under load. A provider degrading is not an outage if the next call goes elsewhere. Fallback chains handle the failover, and the subtlety worth putting in the memo is that a retry is a second call and therefore a second bill — a naive failover double-charges for one user-visible request. Meanwhile ceilings keep one misbehaving job from consuming the quota of everything else: budgets and rate limits are different controls for different failure shapes, and knowing which to reach for is most of the operational skill. When the ceiling does bite, your application sees a 429 or a 402, and handling 429 and 402 is the client-side half. Report the result in percentiles, not averages — p50, p95, p99 is what an SLO is written in.
Shipping speed. Adopting a different model is a string change, and adopting nRouter itself is a base URL and a key:
- client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])
+ client = OpenAI(
+     base_url="https://api.nrouter.ai/v1",
+     api_key=os.environ["NROUTER_API_KEY"],
+ )
That diff is the whole "faster deployment" claim, and it is the one a skeptical engineer can verify in ten minutes with the quick start. Which models the key reaches is a live question rather than a fixed list — the models page is the current answer, and Anthropic, OpenAI and AWS Bedrock are all live today.
The trade we are making
A gateway is a hop, and we are not going to pretend otherwise.
Our availability becomes part of yours. A direct SDK call has one dependency; through us it has two. That is why the status page is public and why fallback behaviour is documented rather than implied.
You do not bring your own provider keys. nRouter holds the provider relationship. If you have negotiated committed-spend pricing directly with a provider, you cannot carry that rate through us, and our gateway settles at provider list price rather than your custom discounted rate. For some teams that single fact decides the evaluation, and it should.
Outcome-led cases are harder to write than feature grids. The matrix can be delegated; the memo cannot. Somebody senior has to know last month's number. That is real work we are asking you to do before the product helps you at all.
Who this is wrong for
- Teams with a large committed-spend contract. If you already beat public rates, run the arithmetic against your actual rate card before anything else.
- Single-service, single-provider deployments. One key, one service, nobody asking for attribution — a direct SDK call is genuinely correct and a gateway is overhead.
- Organisations that forbid a third party in the request path. Self-hosting is the answer, and no feature parity argument changes a compliance boundary.
- Anyone who needs a free evaluation tier. There is not one. The $5 minimum is a real charge.
- Buyers who need every governance feature in a signed enterprise agreement before piloting. You can have that conversation via enterprise, but the features themselves are already on the cheapest plan, which surprises people.
How you can hold us to it
Every outcome above is checkable without talking to us.
- Total spend: compare the pricing page against the table in outcome 1. If they disagree, the pricing page is authoritative and this post is a defect worth an email.
- Unit cost: read
x-nr-request-costoff a live response, sum a day of them, and reconcile against your ledger. Reading a spend ledger is the how. - Ceilings: set a $1 budget on a test key and prove the 402 arrives before the provider call, using hard spend limits.
- Performance: the status page is public history, not a marketing claim.
- Feature parity: create a guardrail on pay as you go. If it asks you to upgrade, outcome 1's last paragraph is false.
- Compliance posture: the trust page states SOC 2 Type II as in progress. If you ever see us write "certified" before it is, that is the sentence to hold us to.
zero-loss containment against runaway budget incidents through strict pre-call virtual key ceilings.
What happens to unallocated or runaway LLM spend during a provider incident?
Without a gateway, a client retry storm or upstream provider degradation repeatedly hits downstream billing without attribution. With nRouter, per-key RPM/TPM velocity caps and hard balance reservations halt runaway loops before provider egress, ensuring blocked calls cost exactly $0.
Does an enterprise agreement change core feature availability on nRouter?
No. nRouter provides the complete feature set — guardrails, A/B evaluation, PII redaction, prompt templates, and per-team budgets — across every plan, including self-serve. nRouter Enterprise adds dedicated tenancy, VPC/BYO-cloud deployment, SSO/SCIM provisioning, custom MSAs, and committed SLAs rather than locking security features behind paywalls.
How quickly can an engineering team migrate production traffic to nRouter?
Migration requires changing only two client configuration parameters: setting the SDK base_url to https://api.nrouter.ai/v1 and supplying an NROUTER_API_KEY. Because nRouter maintains strict OpenAI wire compatibility, zero application rewriting is required.
Try it
For the evaluation budget in your business case, eligible new accounts can receive $100 in promotional credits after email and phone verification, without a card. Promotional access has a restricted model set and spending limits; see current pricing and promotion terms.
Write the one-page memo from the five-line template above, then spend an afternoon replacing its guesses with measurements. Create an account at signup, load the $5 minimum, point one existing service at https://api.nrouter.ai/v1 with NROUTER_API_KEY, and let it run for a day. You will have a real per-request cost distribution, a real attribution split, and a real monthly spend figure — which is a considerably better memo than any capability grid. The vendor-neutral version of the same exercise is the LLM gateway buyer's guide. If you need custom MSAs, dedicated infrastructure, or security reviews, contact our team via nRouter Enterprise or explore nRouter.ai.
See also
- LLM gateway buyer's guide 2026 — the vendor-neutral evaluation this memo sits inside.
- Every Feature on Every Plan: No Fee, No Gate — the commercial position that makes outcome 1's last row true.
- Pay as you go or a subscription: which LLM gateway plan is cheaper? — how pay as you go compares to grandfathered subscriptions.
- Attribute LLM spend by team, customer, and feature — how outcome 2 stops being an estimate.
- Provider fallback chains: surviving an OpenAI outage — outcome 3's mechanism, including the double-billing trap.
- The four ceilings every LLM request passes — the containment story to put in the incident line of the memo.
- Pricing — the authoritative 0% platform fee, minimum purchase, and pay as you go in their live form.
- Secure LLM Gateway for Enterprise — dedicated tenancy, VPC peering, and custom procurement agreements for high-volume enterprise teams.
Sources
Verified 2026-08-23. If any linked page has changed since, email hello@nrouter.ai and we will correct this post.
- nRouter plans and fees: nrouter.ai/pricing — pay as you go at a 0% platform fee, a credit purchase charges exactly the credits bought ($5 costs $5.00, $100 costs $100.00), and the $5 minimum purchase.
- OpenAI API pricing: OpenAI rate card — per-model rates referenced by the unit-cost argument.
- Anthropic pricing: anthropic.com/pricing — per-model rates for the Claude family.
- AWS Bedrock pricing: aws.amazon.com/bedrock/pricing — Bedrock is live on nRouter and AWS publishes its own rates.
- OpenAI API reference: platform.openai.com/docs/api-reference — the request shape the
https://api.nrouter.ai/v1endpoint is compatible with. - OpenAI pricing, developer-docs copy: platform.openai.com/docs/pricing — the per-million-token rates the unit-cost argument is priced against.
- Azure OpenAI Service pricing: azure.microsoft.com — one of the pages that moves under a capability matrix.
- Google Vertex AI generative-AI pricing: cloud.google.com — another.
- AICPA/CIMA trust services criteria (2017, revised points of focus 2022): aicpa-cima.com — what a SOC 2 Type II attestation is evaluated against.
- nRouter Enterprise procurement & deployment: nrouter.ai/enterprise
OpenAI, Anthropic, AWS, Microsoft and Google are trademarks of their respective owners. nRouter is not affiliated with or endorsed by them. All claims above are sourced from their public pricing or documentation on the date shown.
Frequently asked questions
How do I calculate the ROI of an LLM gateway for an internal business case?
Calculate ROI across three financial levers: direct token cost reduction via intelligent model routing (e.g. routing simple queries to lighter models like Claude Haiku or Gemini Flash), engineering hours saved from unified API and retry maintenance, and
When is an LLM gateway not worth it for a business?
A gateway is overhead when you run a single service on a single provider with nobody asking for attribution, when a large committed-spend contract already beats public rates, or when compliance forbids a third party in the request path. In those cases a direct SDK call or self-hosting is the correct answer.
How can I verify an LLM gateway business case before committing?
Check the claims yourself: compare the pricing page against the vendor cost table, read the per-request cost header (x-nr-request-cost) off live responses and reconcile it against your ledger, and set a $1 budget on a test key to prove the spend ceiling fires before the provider call.
The team building nRouter.
More from Company
All posts →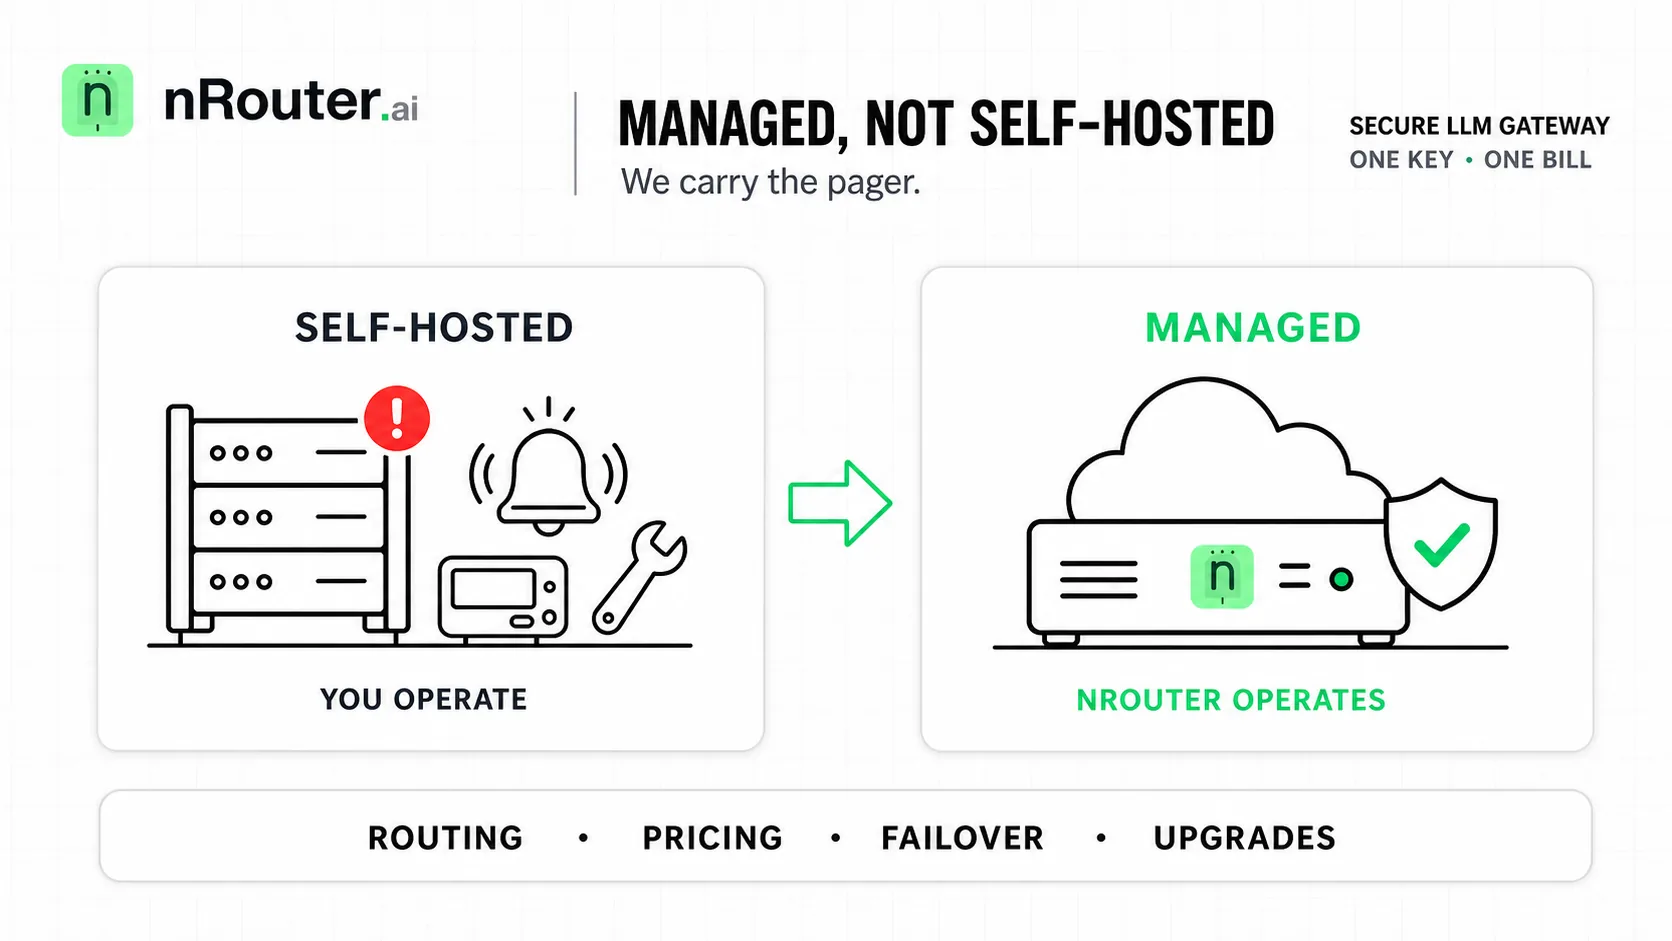
Managed LLM Gateway vs Self-Hosted: Why We Carry the Pager
Why nRouter is a managed LLM gateway rather than self-hosted software: the operational burden of proxy hosting, and when running your own infra still wins.
 nRouter Team
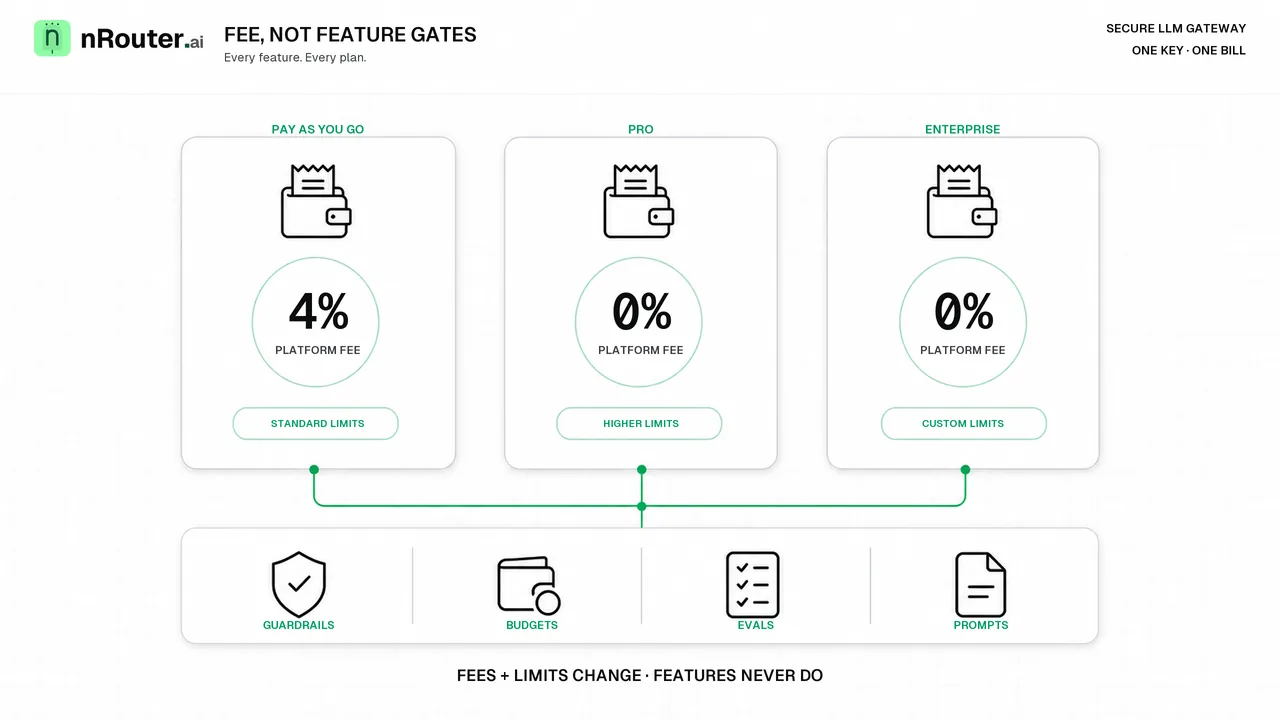
Every Feature on Every Plan: No Fee, No Gate
Guardrails, audit trails, budgets, evals, A/B tests and prompt management are on every nRouter plan, and the one plan on sale is pay as you go at a 0% platform fee. Nothing is gated and nothing is marked up — here is the reasoning and what the bet costs us.
nRouter Team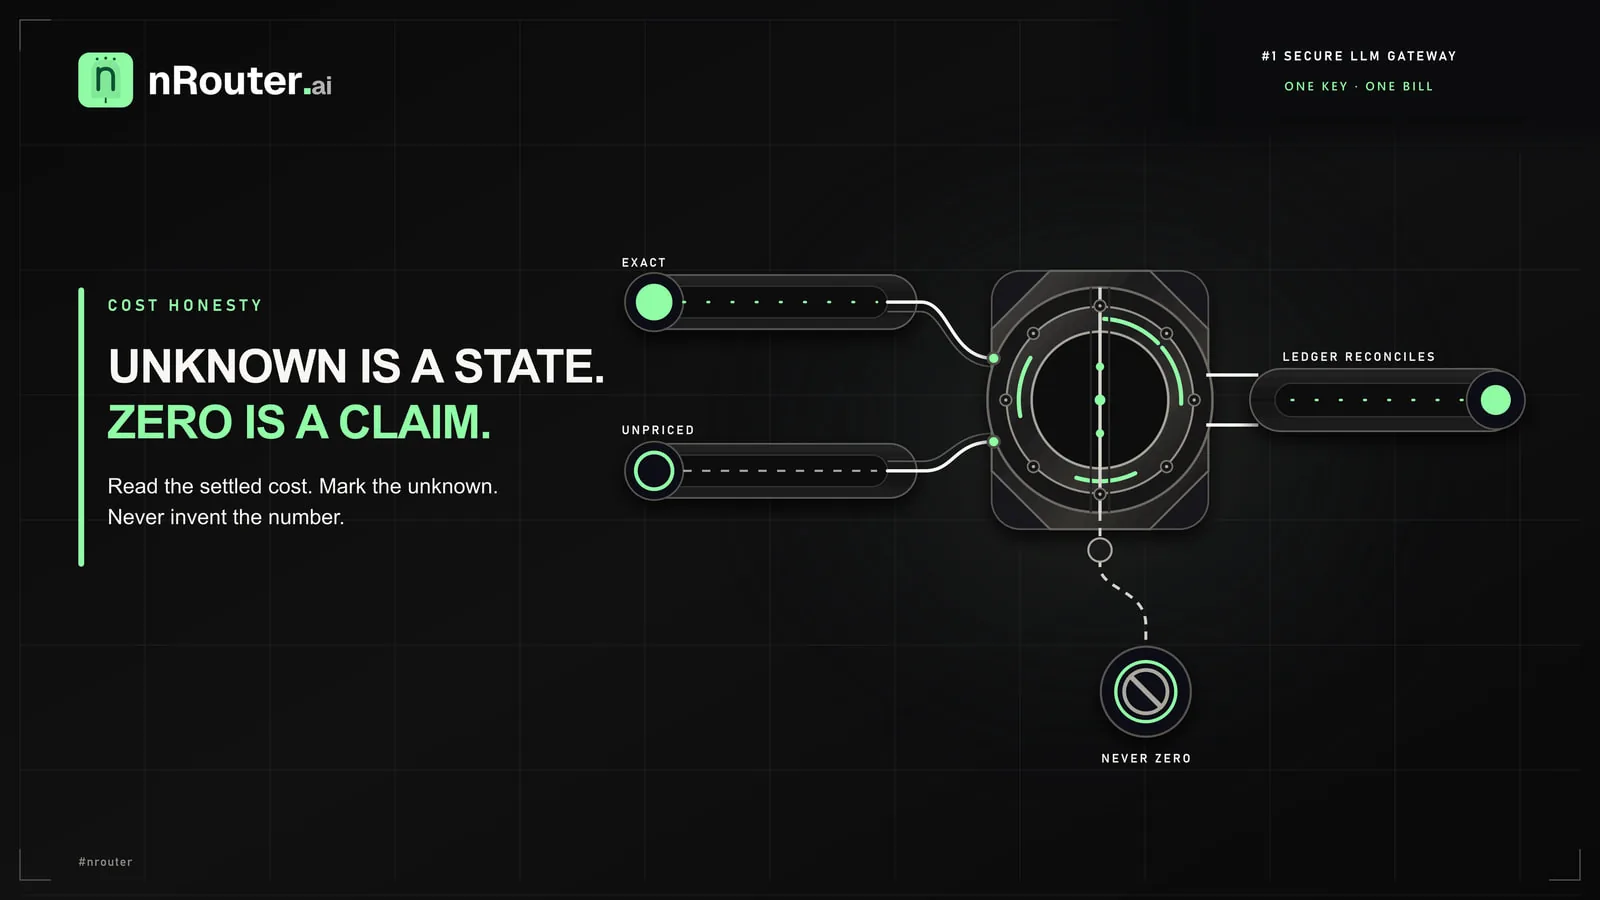
Cost Honesty: Unpriced Is Never $0 on Your LLM Bill
Why nRouter reads the settled LLM cost directly from providers instead of guessing, and why unknown model costs are reported as unpriced rather than as $0.
nRouter Team