


What Is an LLM Gateway? The Six Jobs It Takes Off Your Code
An LLM gateway is one endpoint in front of every model provider that owns six cross-cutting jobs — auth, cost, limits, safety, observability and failover. What it does, what happens to a request inside it, and when you need one.
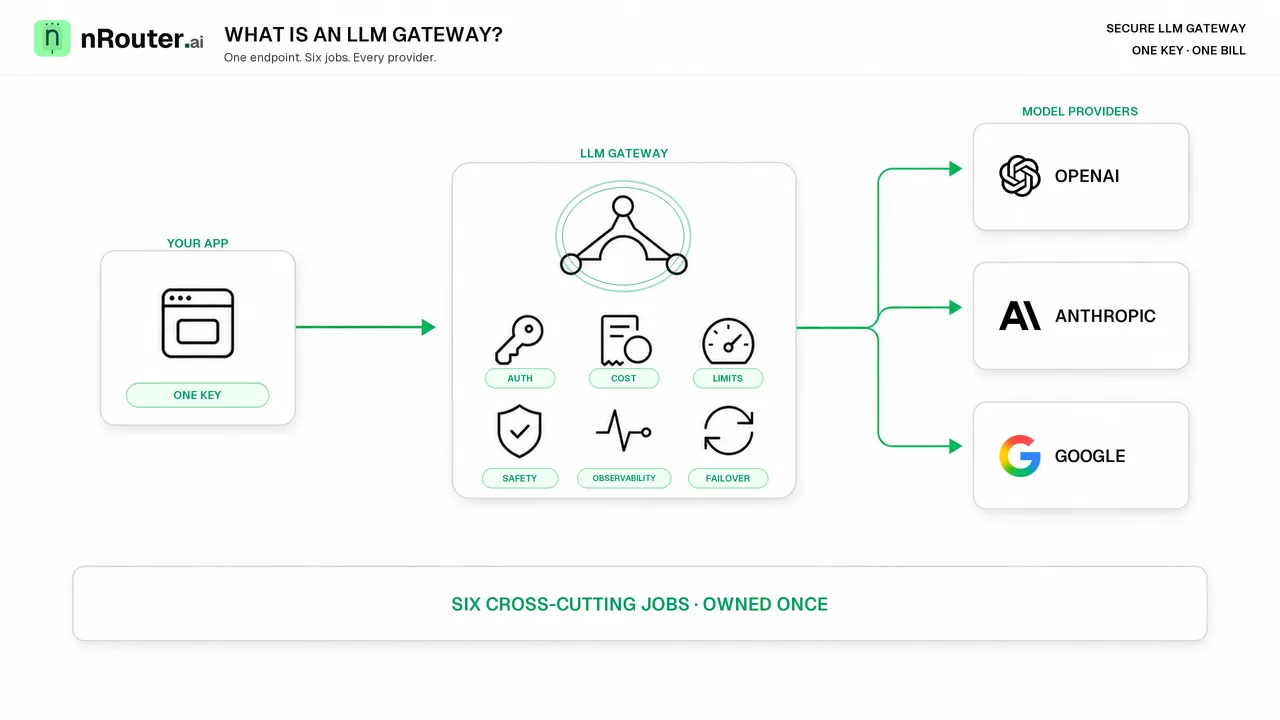
The short answer: an LLM gateway is a single API endpoint between your
application and every model provider. Your code sends one request with one key; the gateway authenticates it, checks money and limits, screens content, routes to a provider, prices the result, logs it, and fails over when the provider does not answer. Six cross-cutting jobs, owned once instead of once per call site.
Figure 1: An LLM gateway sits between your application and every model provider, owning routing, guardrails, and spend in one place.
The short answer
If you call more than one model — or one model from more than one place in your codebase — you eventually build a small layer in front of it. A place to keep the key. A place to count what it cost. A retry. A switch so you can try a cheaper model without editing forty call sites.
That layer has a name. It is an LLM gateway, and the interesting thing about it is how predictable the shape is: almost every team that builds one arrives at the same six responsibilities, in the same order, usually in the same sequence of incidents. This primer sets out what those six are, what actually happens to a request as it passes through, how the three market shapes differ, and how to tell a real gateway from a thin proxy with a marketing page.
The six jobs a gateway takes off your application
The defining property is not "it forwards requests". It is that your application code stops caring which provider serves a request. It asks for a model; the gateway owns everything else.
| Job | What your code stops doing | What it looks like when absent |
|---|---|---|
| Authentication | Holding one credential per provider | N SDKs, N secrets, N rotation schedules |
| Cost accounting | Reconstructing spend from token counts and a price table | A monthly invoice nobody can attribute |
| Limits | Building budget caps and throughput ceilings per service | One retry loop bills a quarter's budget |
| Safety | Bolting PII and injection screening onto each call site | The check exists in the service that remembered it |
| Observability | Instrumenting every service that calls a model | An incident that starts with a timestamp search |
| Reliability | Writing failover per provider, per SDK | A provider's bad hour is your bad hour |
Every one of those is cross-cutting, which is precisely why they belong at a seam rather than in application code. A control implemented in four services is four controls, three of which are out of date.
The seam is cheap to adopt because the industry converged on one request shape. OpenAI's Chat Completions contract is what most clients speak, it is described the ordinary way with OpenAPI, and the officially maintained clients — the OpenAI Python SDK among them — let you override the base URL. That is why pointing an existing application at a gateway is a two-argument change rather than a rewrite.
The last one is worth a sentence of its own because teams consistently under-rate it until the first outage: failover has to be configuration, not a redeploy, or it will not be there when you need it. The mechanics are in Provider fallback chains: surviving an OpenAI outage.
Gateway vs proxy vs router: the terminology
These three terms get used interchangeably. They describe different things:
| Gateway | Proxy | Router | |
|---|---|---|---|
| Definition | A policy enforcement point for LLM traffic: one endpoint that applies routing, guardrails, budgets, and audit to every request | A forwarding intermediary: passes requests to a provider, usually with minimal transformation | A decision function: picks which model or provider serves a given request |
| Operates at | Request path, before provider egress | Network boundary, between client and provider | Inside the gateway (or standalone), at decision time |
| Key functions | Authentication, policy resolution, cost attribution, failover, observability | TLS termination, header injection, retries | Model selection, fallback chains, load balancing |
A gateway contains a router. A proxy forwards without deciding. If a product only forwards requests, it is a proxy, not a gateway — regardless of what the marketing page says.
What actually happens to a request, in order
"It forwards the call" hides the part that matters. A request through a gateway clears a fixed sequence, and knowing the order tells you which failure you are looking at when something comes back non-200.
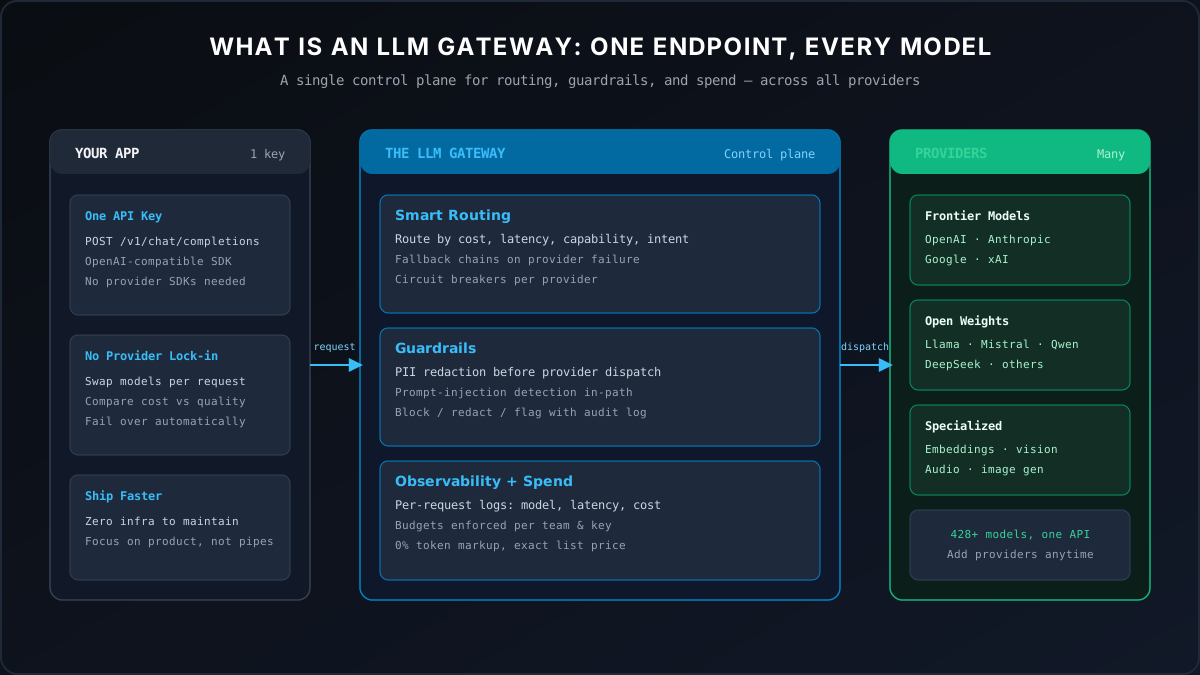
- Authenticate. The credential resolves to an organization, a team and a key. Tenancy comes from the credential, never from a header or body field a caller could set — a gateway that trusts a caller-supplied tenant id has a spend-attribution spoof.
- Check money. The estimated cost is reserved against the balance. No balance, no provider call.
- Check policy. Budget caps for the relevant scope, then rate limits (RPM and TPM) for velocity.
- Screen content. Guardrails run before egress: PII detection, regex filters, keyword blocklists, prompt-injection detection, or a webhook of your own.
- Route. Resolve the model name to a provider and a deployment, translate the request shape, and send it with the provider credential the gateway holds. "Request shape" is not a metaphor: OpenAI's Chat Completions and Anthropic's Messages are different JSON contracts for the same idea, and translating between them is work your application no longer does.
- Screen the response, then price it from the provider's reported usage, settle the reservation against the real cost, and log the row.
Steps 2 through 4 are the reason a gateway is not a proxy: they can all reject a request before a provider is contacted, which means a blocked call costs nothing. The four gates and the exact status code each returns are enumerated in Credits, budgets, rate limits, guardrails: four pre-flight gates.
Why not just call the provider SDK directly
Calling the provider SDK directly is correct for a prototype and stays correct for a surprisingly long time. It stops being correct the moment one of these is true:
| You have… | …and direct SDK calls cost you |
|---|---|
| More than one provider | N SDKs, N keys, N billing dashboards to reconcile |
| More than one team | No per-team attribution and no per-team ceiling |
| Production traffic | No failover when a provider 5xxs or throttles you |
| Data you cannot leak | No inline redaction or injection screening |
| A finance team | Spend is a monthly surprise rather than a live number |
| A compliance obligation | Controls scattered across every service that calls a model |
The trade is explicit: a few milliseconds of pass-through latency in exchange for not re-implementing cost, safety and reliability at every call site — badly, and once per provider. If latency is the objection, measure it against your model's own p95 before deciding; the methodology is in LLM latency: p50, p95, p99, and time-to-first-token.
Aggregator, self-hosted, managed: three shapes, three bills
The word "gateway" covers three products that fail in different ways.
| Aggregator | Self-hosted | Managed | |
|---|---|---|---|
| Who runs it | The vendor | You | The vendor |
| Typical revenue model | Markup on every token | Your infrastructure bill | Subscription or platform fee |
| Governance depth | Usually thin | Whatever you build | Built in |
| Ops burden | None | Scaling, upgrades, storage, on-call | None |
| Data residency | Vendor's | Yours | Vendor's |
| Failure mode to watch | Cost you cannot audit | An unowned service | Vendor lock-in on config |
Aggregators route to many models and commonly recover their cost as a per-token markup, which is invisible in exactly the place you would want to check it. Self-hosted gives you total control and hands you a database, an upgrade path and a pager rotation. Managed runs the infrastructure with governance included and asks you to accept that the data traverses someone else's system.
nRouter is the third kind, with the markup question answered by pricing rather than a promise: nRouter sells one plan, pay as you go, at a 0% platform fee. A credit purchase charges exactly the credits bought ($100 costs $100.00), nRouter absorbs the card-processing cost, and usage settles at the served model's exact list price (0% markup). The argument in full is Markup-free LLM credits, and the managed-versus-self-hosted trade specifically is Managed LLM gateway vs self-hosted.
What a gateway does not do
Being clear about the boundary saves an evaluation cycle.
- It does not make a bad prompt good. Routing, caching and failover do nothing about output quality. Prompt management and evals help you measure quality; they do not manufacture it.
- It does not remove the provider's rate limits. It gives you your own limits on top, which is a different and complementary thing.
- It is not a vector database or a RAG framework. It serves the embedding and chat calls a RAG system makes — see An LLM gateway for RAG — and knows nothing about your chunks.
- It is not an agent framework. It is what an agent framework calls. The cost-attribution problem agents create is real and specific: Multi-agent cost tracking.
- It does not store your prompts by default, and should not. On nRouter, request and response content is never written to the log; metadata is. That is the privacy-safe default, and the field list is in What an LLM request log should contain.
The numbers that decide whether it pays for itself
A gateway is worth its cost when the cost is legible, so here is nRouter's, worked rather than asserted.
nRouter sells one plan, pay as you go, at a 0% platform fee, with a $0 subscription. A credit purchase charges exactly the credits bought ($5 costs $5.00, $100 costs $100.00), nRouter absorbs the card-processing cost, and usage settles at the served model's exact list price (0% markup). No subscription plan is sold (existing subscribers keep theirs).
There is no hidden variable, because every feature is included on every account — guardrails, A/B tests, prompt management, evals and per-team budgets are included, not gated behind plans.
Signup is card-required and takes a real charge; pay as you go from $5, 0% platform fee; a purchase charges exactly the credits bought ($5 costs $5.00). Current numbers are always on Pricing.
Twelve questions that separate a gateway from a proxy
Take these to any vendor, including this one.
- Is the cost figure read or estimated? A real gateway prices from the provider's reported usage, not from a token count it guessed.
- What happens when a call cannot be priced? The right answer is a stated
unknown. A confident
$0is the wrong answer — the reasoning is Cost honesty. - Can I cap spend, and does the cap hold under concurrency? Ask specifically what happens when many requests race the last dollar: Reserve-and-settle.
- Are there separate controls for total spend and for velocity? One number cannot do both jobs — Budgets vs rate limits.
- Is safety gated behind a tier? Redaction you have to upgrade to buy is a statement about the vendor's incentives.
- What happens when a provider is down? Configuration, or a redeploy?
- Is governance multi-tenant? Per-team budgets, per-key limits and roles matter the moment two people share the account.
- Where does tenancy come from? From the authenticated credential, or from something the caller can set?
- Do I hand over a provider key? If yes, that secret is now in two estates and both are in your audit scope — Why we don't do BYOK.
- What is stored, and for how long? Ask about content specifically, not "logs" generally.
- What is the real price? Separate the provider cost from the gateway's cut. A gateway with no visible price is charging you somewhere.
- What is the compliance posture, stated exactly? "In progress" and "certified" are different words — SOC 2 for an LLM gateway.
Reading the response: the signals a gateway gives back
A gateway earns its place partly through what it hands back on every call. On
nRouter the response carries x-nr-* headers you can capture from the SDK you
already use:
import os
import time

from openai import OpenAI

client = OpenAI(
    api_key=os.environ["NROUTER_API_KEY"],
    base_url="https://api.nrouter.ai/v1",
)

started = time.perf_counter()
resp = client.chat.completions.with_raw_response.create(
    model="gpt-5.4-mini",
    messages=[{"role": "user", "content": "hello"}],
)
elapsed_ms = (time.perf_counter() - started) * 1000

print(resp.headers.get("x-nr-request-id"))     # always present
print(resp.headers.get("x-nr-request-cost"))   # ABSENT when the call is unpriced
print(resp.headers.get("x-nr-cost-status"))    # "exact" or "unpriced"
print(resp.headers.get("x-nr-model"))          # the model that actually served it
print(round(elapsed_ms, 1))                    # latency is yours to measure
x-nr-request-cost is absent when a call cannot be priced, which is not the
same as zero and must never be read as zero. Client code that defaults a missing
header to 0.0 under-reports its own spend while the ledger stays correct.
Latency is the one signal that does not arrive as a header: time the call on your
own clock, as above, and store the elapsed value beside x-nr-request-id so the
two views reconcile. Percentiles across your whole traffic are on the dashboard.
When a request is rejected, the code field tells you which of the gates fired —
and the status code alone is not enough, because two gates return 402 and two
return 429. Both are ordinary HTTP: 402 is reserved by
RFC 9110 and 429 Too Many Requests is defined in
RFC 6585, so the transport
carries nothing bespoke and the code field is what disambiguates.
| Situation | Status | code |
|---|---|---|
| Balance cannot cover the call | 402 | insufficient balance |
| Org / team / user budget hit | 402 | budget_exceeded |
| Per-key budget hit | 429 | key_budget_exceeded |
| RPM or TPM exceeded | 429 | rate_limit_exceeded |
| Content blocked pre-egress | 400 | guardrail_blocked |
Branching client retries on code rather than status is the single highest-value
thing to get right in an integration —
Handling 429 and 402 errors.
When you do not need one
Honest scoping, because the wrong answer here wastes a month.
You do not need a gateway if you call exactly one model from exactly one service, the spend is small enough that nobody asks about it, the data is not sensitive, and an outage is an inconvenience rather than an incident. The provider SDK is genuinely fine, and adding infrastructure to that situation buys you a dependency.
You are past the line the moment you can say yes to any of: I call more than one model; more than one team shares the spend; this serves production traffic; or I handle data I cannot afford to leak. Notice that three of those four are organizational rather than technical, which is why the decision usually arrives from finance, security or a customer questionnaire rather than from engineering.
If you already run a gateway and are comparing, the vendor-by-vendor version of this page is LLM gateway buyer's guide 2026.
zero dollars.
Try it
The fastest way to understand a gateway is to send one request through one and
read the headers that come back. That takes about two minutes: point the OpenAI
client you already import at https://api.nrouter.ai/v1, pass an nRouter key,
and print x-nr-request-cost.
Every governance feature described above — guardrails, per-team budgets, rate limits, A/B tests, prompt management, evals and request logs — is included. nRouter sells one plan, pay as you go, at a 0% platform fee; a credit purchase charges exactly the credits bought, and usage settles at the served model's exact list price (0% markup).
Load the $5 minimum (charging exactly $5.00, 0% platform fee) at app.nrouter.ai/signup. Browse what is currently servable on Models, send a call from the browser in the Playground, or follow the step-by-step build in Ship your first AI feature. For organizations requiring dedicated VPC deployment, custom MSA terms, or private networking, consult nRouter Enterprise. Broader architecture and product guides are available on nRouter.ai. Questions get answered in the nRouter community.
See also
- Ship your first AI feature: signup to production in an afternoon — the procedural version of this primer, with the commands and dashboard fields.
- Credits, budgets, rate limits, guardrails: four pre-flight gates — the four checks from step 2–4 above, each with its scope and status code.
- Virtual keys vs master key: scoping a key per job — how the authentication job is meant to be used once you have more than one service.
- LLM gateway buyer's guide 2026 — the vendor-comparison layer above this page, once you know what a gateway is.
- Managed LLM Gateway vs Self-Hosted: Why We Carry the Pager — the third shape from the market table, argued rather than asserted.
- Handling 429 and 402 errors from an LLM gateway — what to do with the status codes in the table above, on the client side.
- Pricing — the 0% platform fee, the credit minimum, and exact list-price settlement.
- Explore nRouter Enterprise — dedicated tenancy, VPC deployment, SSO/SCIM governance, and procurement documentation for enterprise AI.
Sources
Verified 2026-06-14; every external reference was re-checked on 2026-08-23. Product behaviour, headers, status codes and pricing come from nRouter's own documentation and pricing page; the definitional claims about the wire contract come from the providers' own references, linked below. If something has drifted, email hello@nrouter.ai and we will correct it.
- The request shape most clients speak, and what a gateway must accept: OpenAI Chat Completions reference
- The other native contract a gateway translates to and from: Anthropic Messages reference
- How that contract is described, and why swapping a base URL is enough: OpenAPI Specification 3.1
- The HTTP statuses behind the rejection table: RFC 9110 for
402, RFC 6585 for429 - OpenAI Python SDK
base_urloverride: github.com/openai/openai-python - Base URL, key format and authentication: Authentication
- First call in curl, Python and Node: Quick Start
- Budget scopes, durations and codes: Budget Controls
- Guardrail types, actions and pre/post placement: Guardrails
- Response headers and error shapes: Chat Completions API
- Pay as you go, 0% platform fee, and the $5 credit minimum: nrouter.ai/pricing
- Enterprise deployment options and architecture: nrouter.ai/enterprise
Frequently asked questions
What is an LLM gateway and why does it matter?
If you call more than one model — or one model from more than one place in your codebase — you eventually build a small layer in front of it: a place to keep the key, a place to count what it cost, a retry, a switch to try a cheaper model without editing forty call sites. That layer is an LLM gateway, and almost every team that builds one arrives at the same six responsibilities: authentication, cost accounting, limits, safety, observability, and reliability.
What does an LLM gateway take off your application's plate?
The defining property is not that it forwards requests. It is that your application code stops caring which provider serves a request: it asks for a model, and the gateway owns authentication, cost accounting, budget and rate limits, content screening, logging, and failover. Those controls are cross-cutting, which is why they belong at one seam rather than re-implemented in every service.
What happens to a request inside an LLM gateway, in order?
A request clears a fixed sequence: authenticate the credential (tenancy comes from the credential, never from a caller-set field), reserve the estimated cost against the balance, check budget caps and rate limits, screen the content with guardrails, route to the provider and translate the request shape, then screen the response, price it from the provider's reported usage, settle the reservation, and log the row. The money, policy, and screening gates can all reject before a provider is contacted, so a blocked call costs nothing.
How does an enterprise LLM gateway handle provider outages and failover?
Failover is configuration, not a redeploy. A request moves to the next model in the fallback list you configured when the provider cannot take it: an upstream 429, 503 or Anthropic 529, a 401 or 404 from a misconfigured deployment, a connection that never opened, or no first byte in time. It never fails over on a 500, 502 or 504, or on a read timeout after the connection opened, and it makes at most three provider calls under one reservation, so the client needs no custom retry loop of its own.
What deployment options are available for organizations with strict compliance requirements?
nRouter is a managed service: you call one endpoint with one key and there is no gateway software to deploy. For organizations with stricter requirements — dedicated tenancy, network isolation, or a specific compliance review — the options are scoped with the team; the Enterprise page sets out what is available, and the contact page is the route to start that conversation.
How does credit reservation and spend settlement work?
nRouter uses a two-phase reserve-and-settle architecture. Before dispatching a request to an upstream provider, the gateway holds an estimated maximum cost based on prompt length and model output ceilings. Once the provider streams the response, the gateway calculates the exact token usage at the flat upstream list price (0% per-token markup), settles the exact charge against the balance, and immediately releases any unused hold.
Support engineer at nRouter, writing routing and performance guides from real customer workloads.
More from Guides
All posts →
Measure TTFT and Trace an LLM Request Step by Step in Python
Send an nrouter/auto request with the Python SDK, read routing, guardrails and cost from its headers, fetch the request back by id, print every gateway step with its start, end and duration, then measure TTFT and latency over N runs.
 nRouter Team
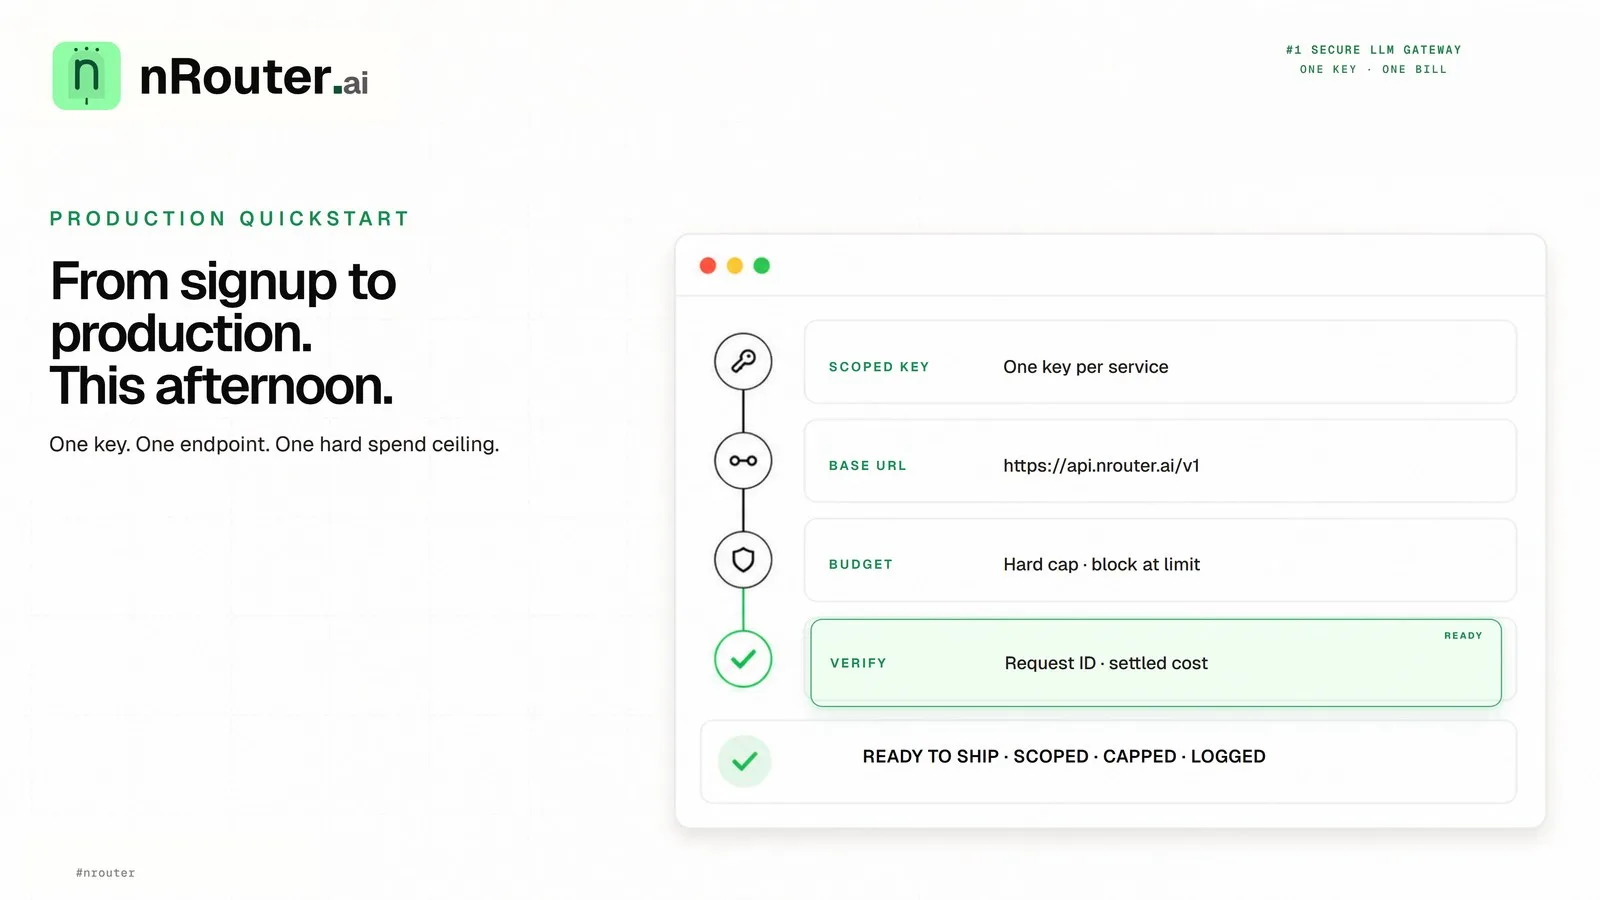
Ship Your First AI Feature: Signup to Production in an Afternoon
A step-by-step path from a funded nRouter account to a production LLM call with a spend ceiling on it — create a scoped key, point your existing OpenAI client at one base URL, cap the key, and verify the cost header came back.
Latency Routing and Automatic Failover Without Retry Code
Measure candidate model latency, configure explicit fallbacks, understand the gateway attempt budget, and verify the result on your own p95.