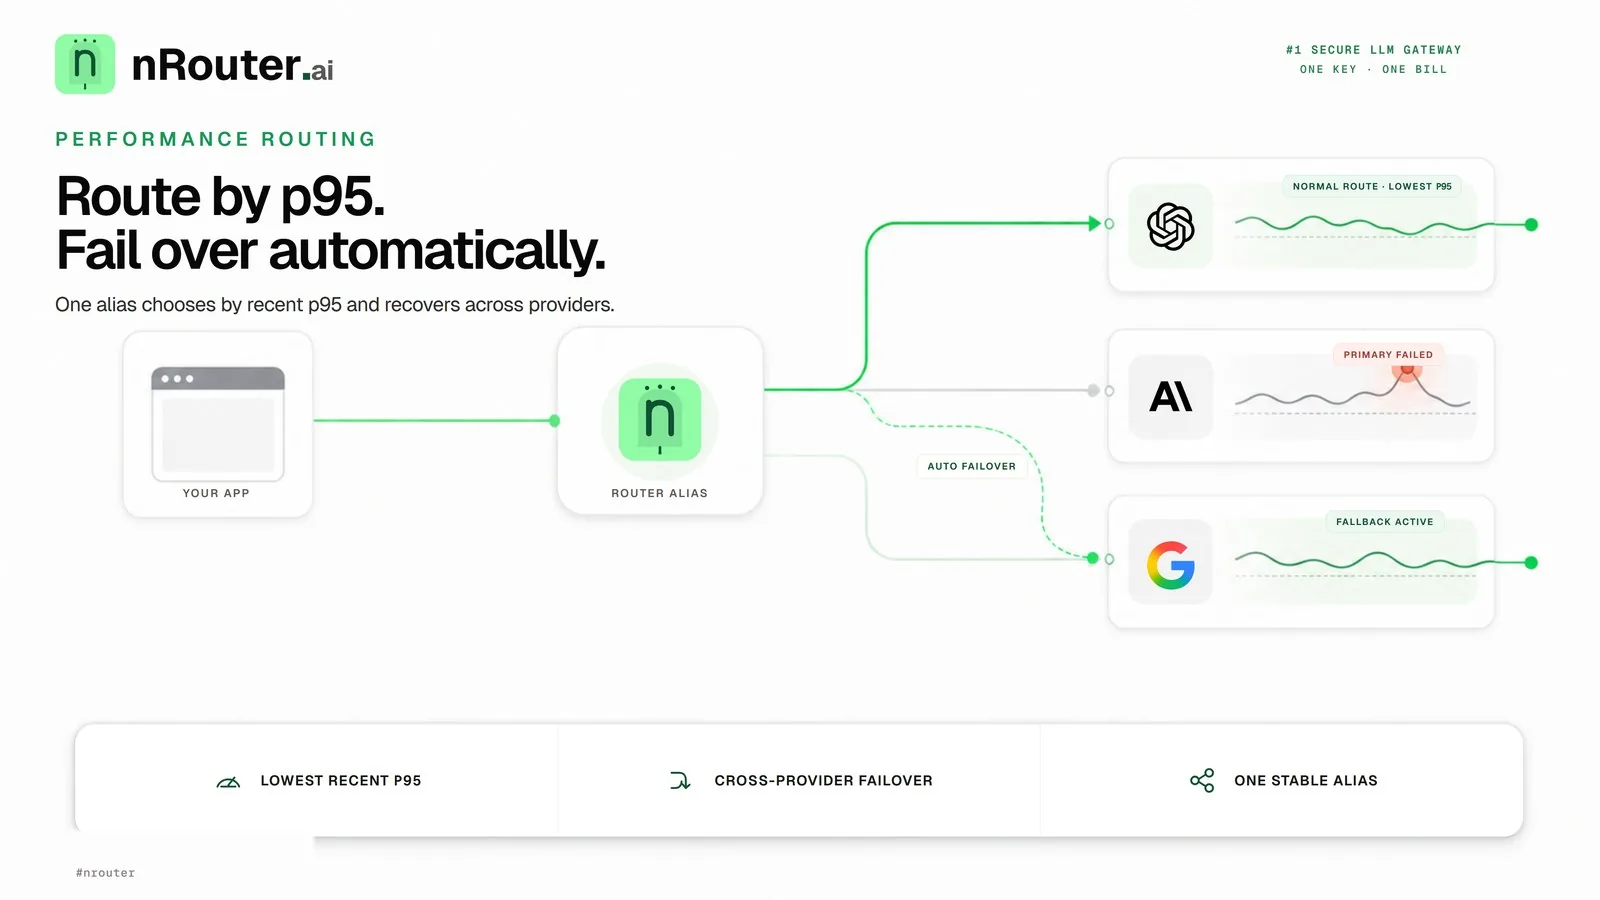
Tag

observability

13 posts tagged "observability".

Editorial Guide

Full-Stack LLM Observability: Tracing, Spend Ledgers & Telemetry

Operating production LLMs without granular observability turns generative workflows into opaque black boxes. Full-stack LLM observability binds edge request parameters, prompt token counts, completion latencies, guardrail inspection scores, and exact monetary costs into a unified distributed trace. High-cardinality telemetry empowers engineering teams to detect latency regressions, diagnose provider errors, and audit regulatory compliance.

Key Engineering Challenges

Disconnected Request Traces Across Services

Tracing requests across multiple microservices, proxy layers, guardrail sidecars, and third-party model providers often leaves fragmented log files with no common correlation identifier, complicating root-cause debugging.

High-Volume Streaming Log Ingestion

Real-time token streaming generates massive log volumes. Systems must capture precise tokenomics and timing metrics without creating disk I/O bottlenecks or slowing down inference.

Sensitive Content Retention Liabilities

Indiscriminately storing full prompt and response payloads creates severe privacy risks for GDPR and HIPAA compliance, requiring granular data retention policies.

Accurate Per-Request Cost Attribution

Calculating exact dollar spend in real time requires reconciling differing input, output, cached, and multimodal token rates across dozens of foundation model providers.

Architecture Taxonomy & Core Components

Unified x-nr-request-id

Request identifier binding edge WAF logs, the dashboard request trace, and immutable database spend rows.

22-Column Spend Ledger

High-precision financial audit records capturing exact token counts, provider rates, and funding sources.

Request Log & CSV Export

Dashboard request logs with a per-request trace, exportable as CSV.

nRouter Enterprise Observability Engine

Every inference request routed through nRouter receives an immutable x-nr-request-id generated at the edge WAF. As requests traverse Preflight Phases 1 through 4 and stream from downstream providers, nRouter records token metrics, latency milestones, and exact costs into a 22-column spend row. Request metadata is always stored because it is the billing record; prompt and response text are never stored. Request logs are viewable in the dashboard and exportable as CSV, and every response carries x-nr-request-id, x-nr-request-cost, and x-nr-model headers.

Explore our observability guides to discover how to debug agentic loops, monitor p99 latency percentiles, and set up real-time spend anomaly alerts.

Posts

Latest first

Measure TTFT and Trace an LLM Request Step by Step in Python
Guides

Measure TTFT and Trace an LLM Request Step by Step in Python

Send an nrouter/auto request with the Python SDK, read routing, guardrails and cost from its headers, fetch the request back by id, print every gateway step with its start, end and duration, then measure TTFT and latency over N runs.

nRouter TeamnRouter Team
12 minRead →
Warm Connection Pools in an LLM Gateway, and What They Do Not Fix
Engineering

Warm Connection Pools in an LLM Gateway, and What They Do Not Fix

What a reused provider connection saves an LLM request, what it cannot save, and how to measure the gateway's share of your latency instead of trusting a headline number.

Suresh
11 minRead →
LLM Observability: Traces, Spend Logs, and Request Debugging
Product

LLM Observability: Traces, Spend Logs, and Request Debugging

Inspect end-to-end inference traces, exact-cent spend rows, and multi-provider routing decisions under one request ID, with response headers on every call.

Suresh
11 minRead →
How to Benchmark an LLM Gateway in Production: Cost, Latency, Reliability, and Quality
Engineering

How to Benchmark an LLM Gateway in Production: Cost, Latency, Reliability, and Quality

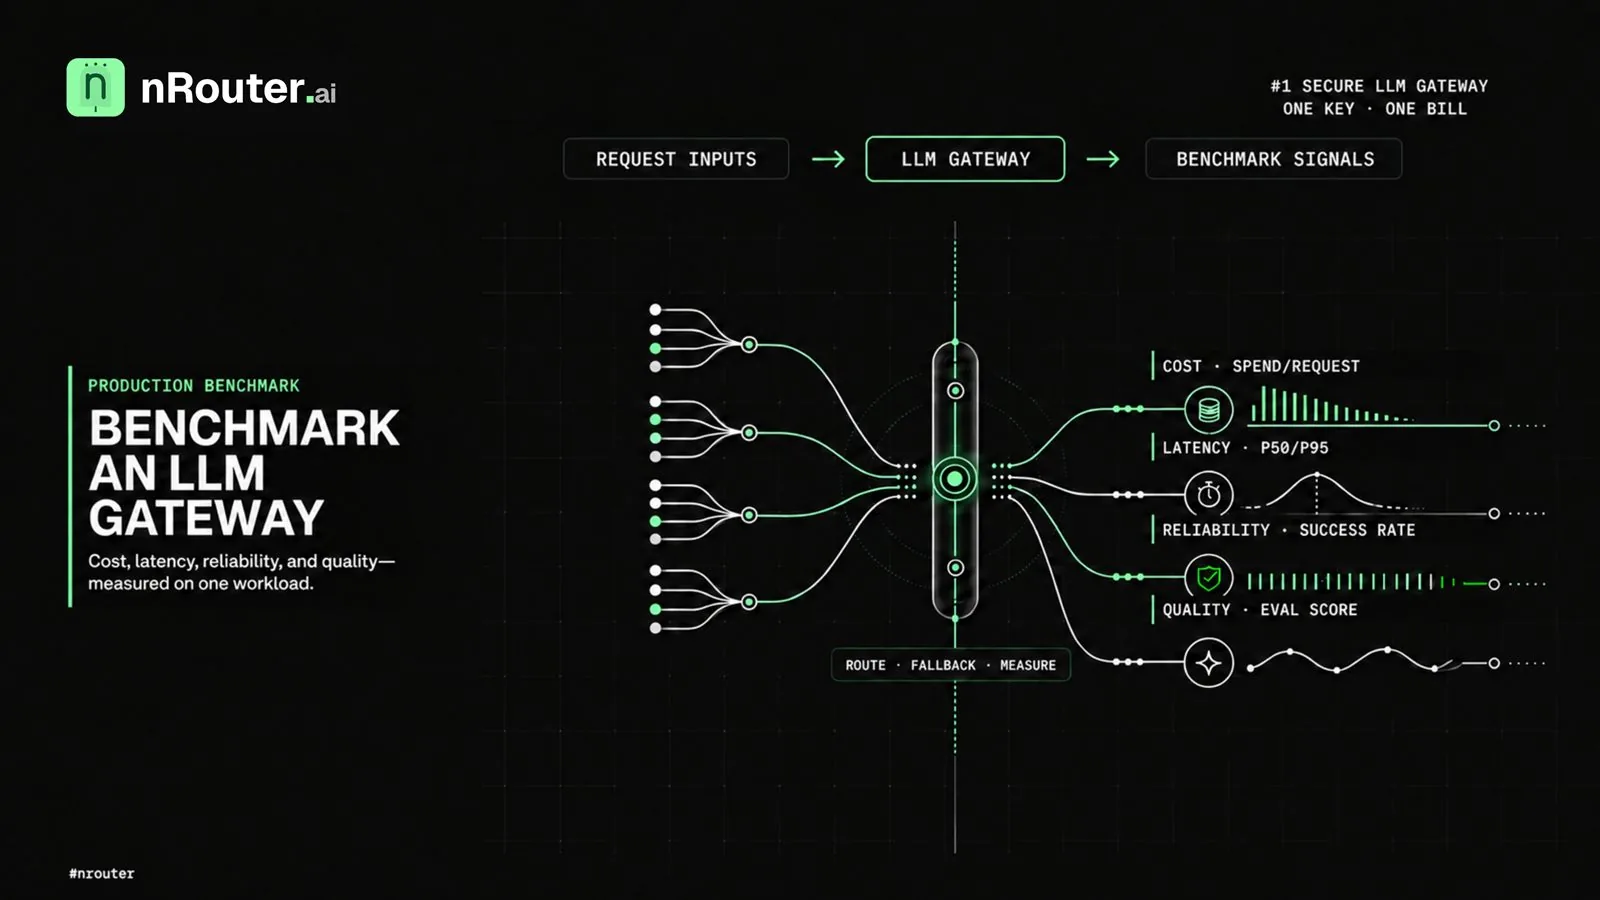
Follow a repeatable LLM gateway benchmark methodology for cost, latency, reliability, failover, and output quality before publishing measured results.

Suresh
13 minRead →
LLM Streaming Failures: Why Mid-Stream Retry Duplicates Output
Engineering

LLM Streaming Failures: Why Mid-Stream Retry Duplicates Output

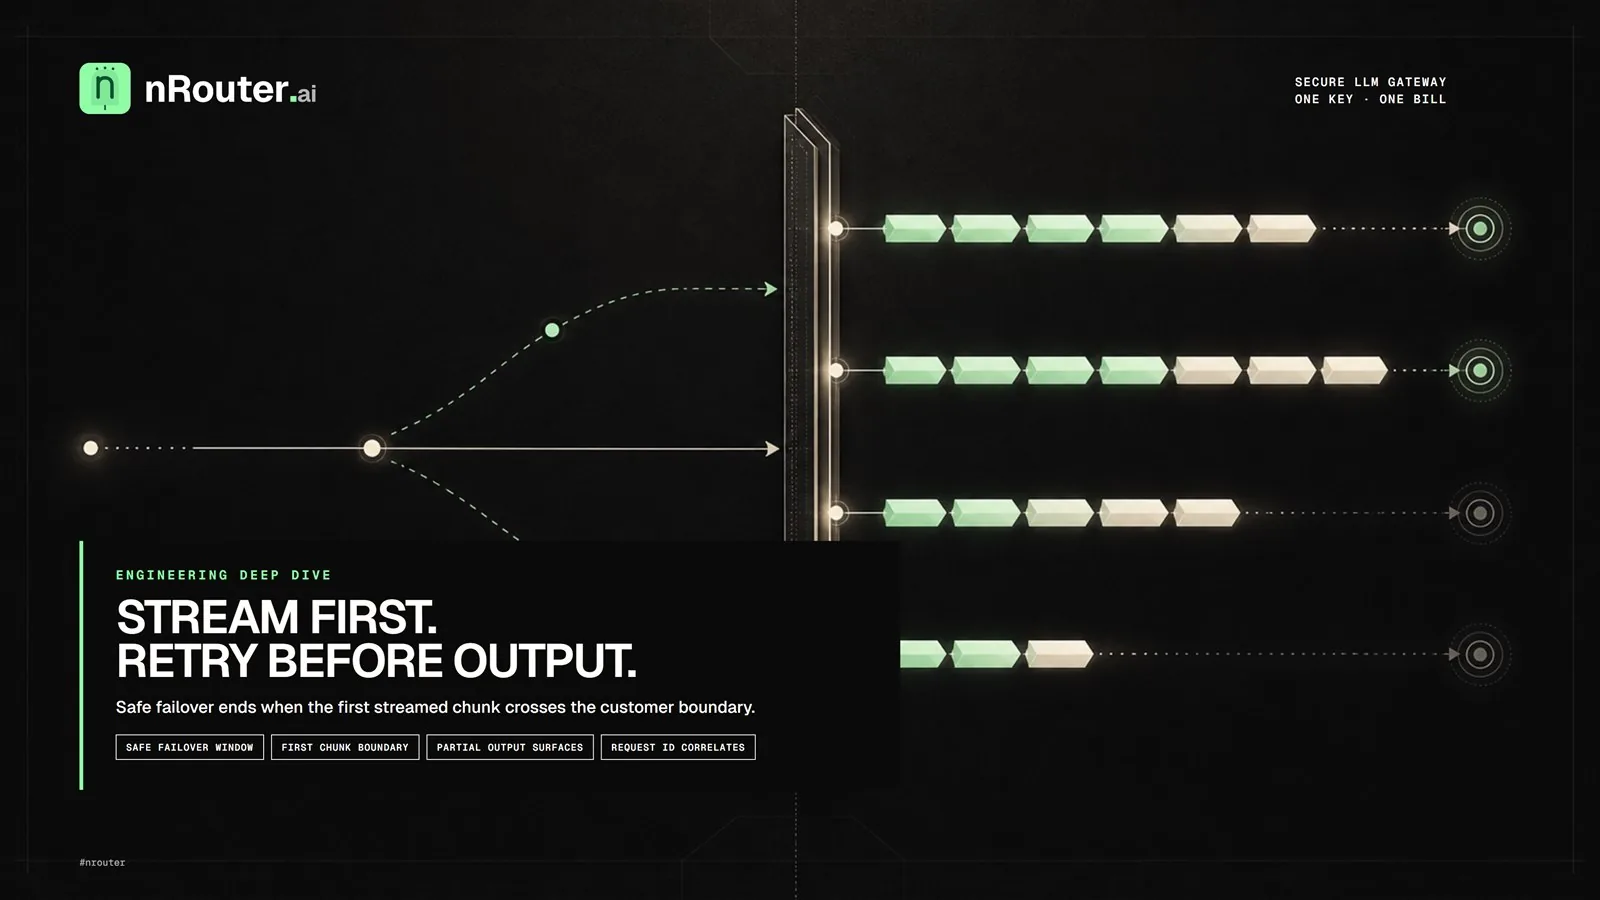
Understand where LLM streaming failover stops being safe, why partial output cannot be replayed silently, and how clients recover without duplicated text.

Suresh
11 minRead →
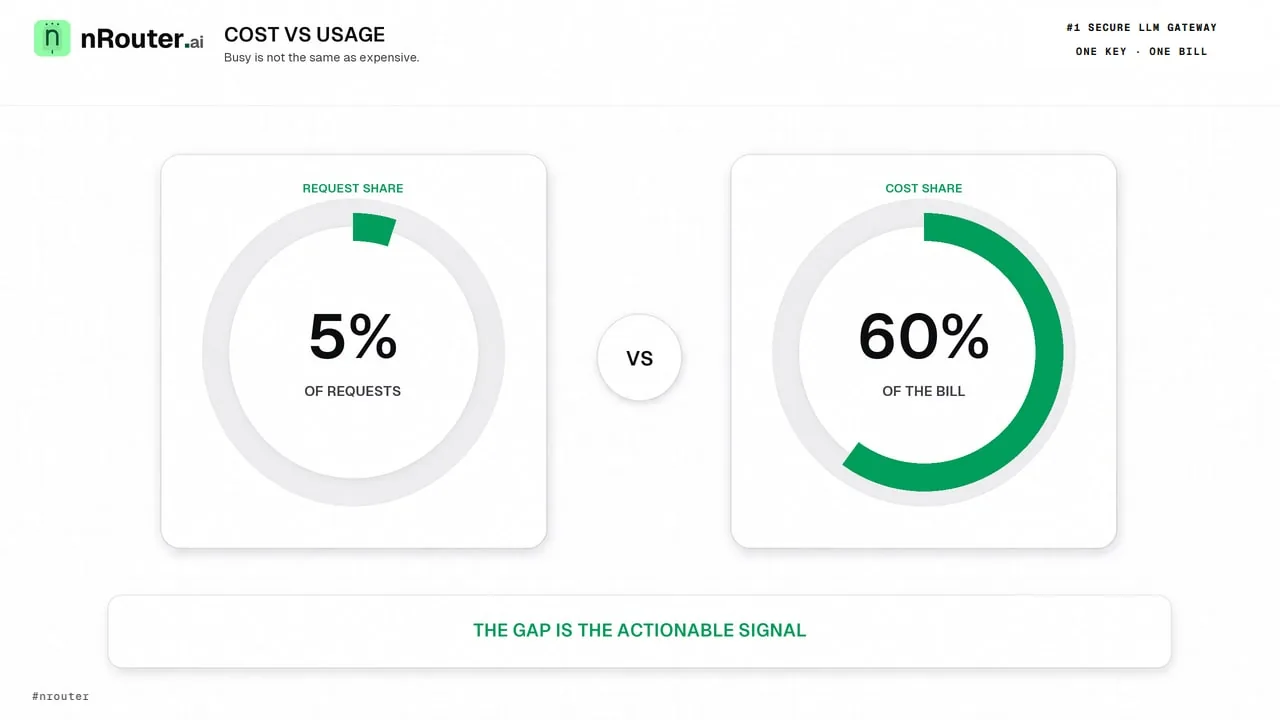
5% of Requests, 60% of the Bill: Reading Cost Against Usage
Engineering

5% of Requests, 60% of the Bill: Reading Cost Against Usage

Request count and dollar cost tell different stories, and the gap between them is where the savings are. Here are the four shapes an overlay of cost and usage produces, which one to chase first, and what makes the numbers trustworthy enough to act on.

Suresh
11 minRead →
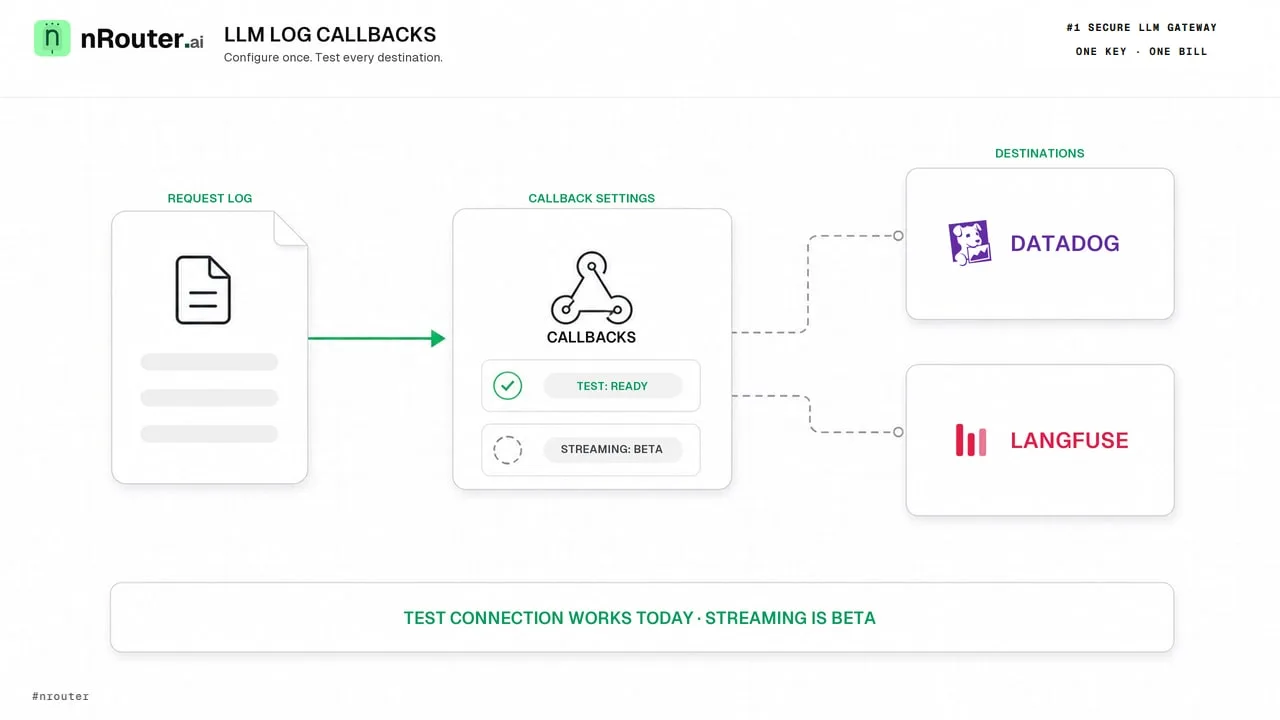
LLM Logs in Datadog and Langfuse: What Works Today
Guides

LLM Logs in Datadog and Langfuse: What Works Today

nRouter does not deliver request logs to Datadog or Langfuse yet. Here is what works today: response headers, request tags, CSV export and alert channels.

Sugumar
10 minRead →
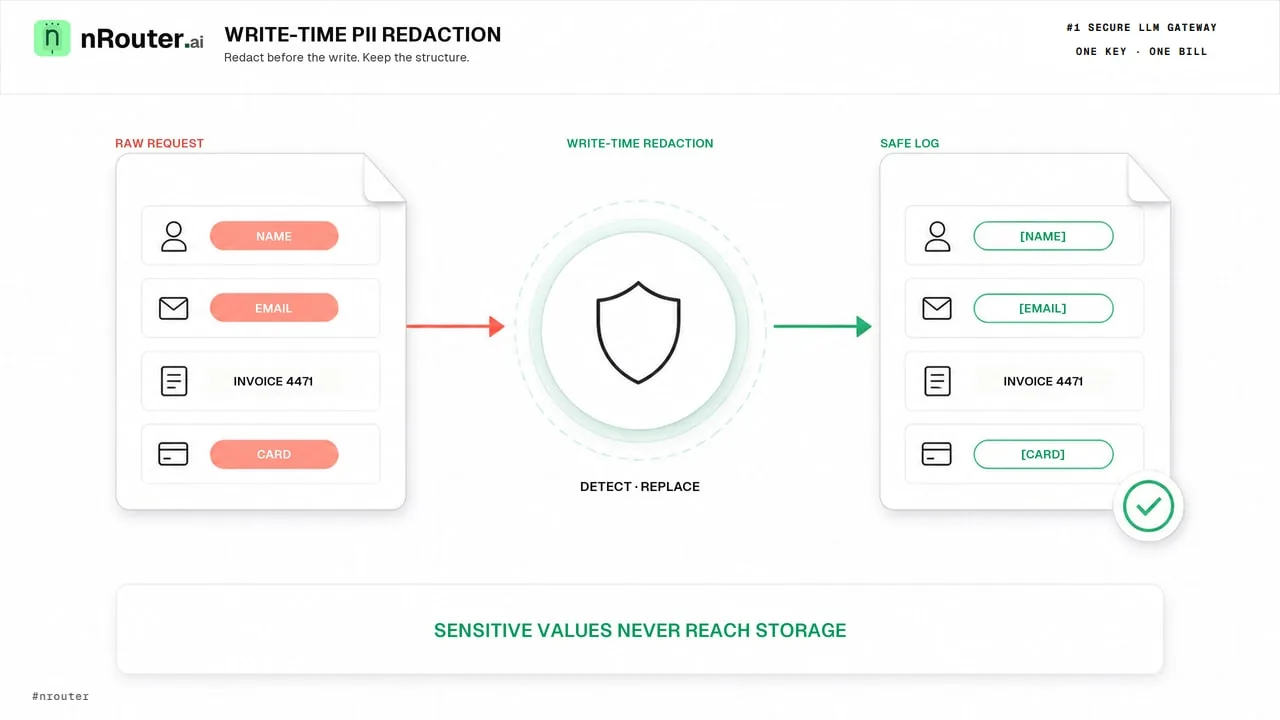
Write-Time PII Redaction in LLM Logs, Without Losing Debug Detail
Engineering

Write-Time PII Redaction in LLM Logs, Without Losing Debug Detail

Learn how write-time redaction, typed placeholders, and metadata scrubbing keep LLM request logs fully debuggable without storing sensitive customer PII.

Suresh
11 minRead →
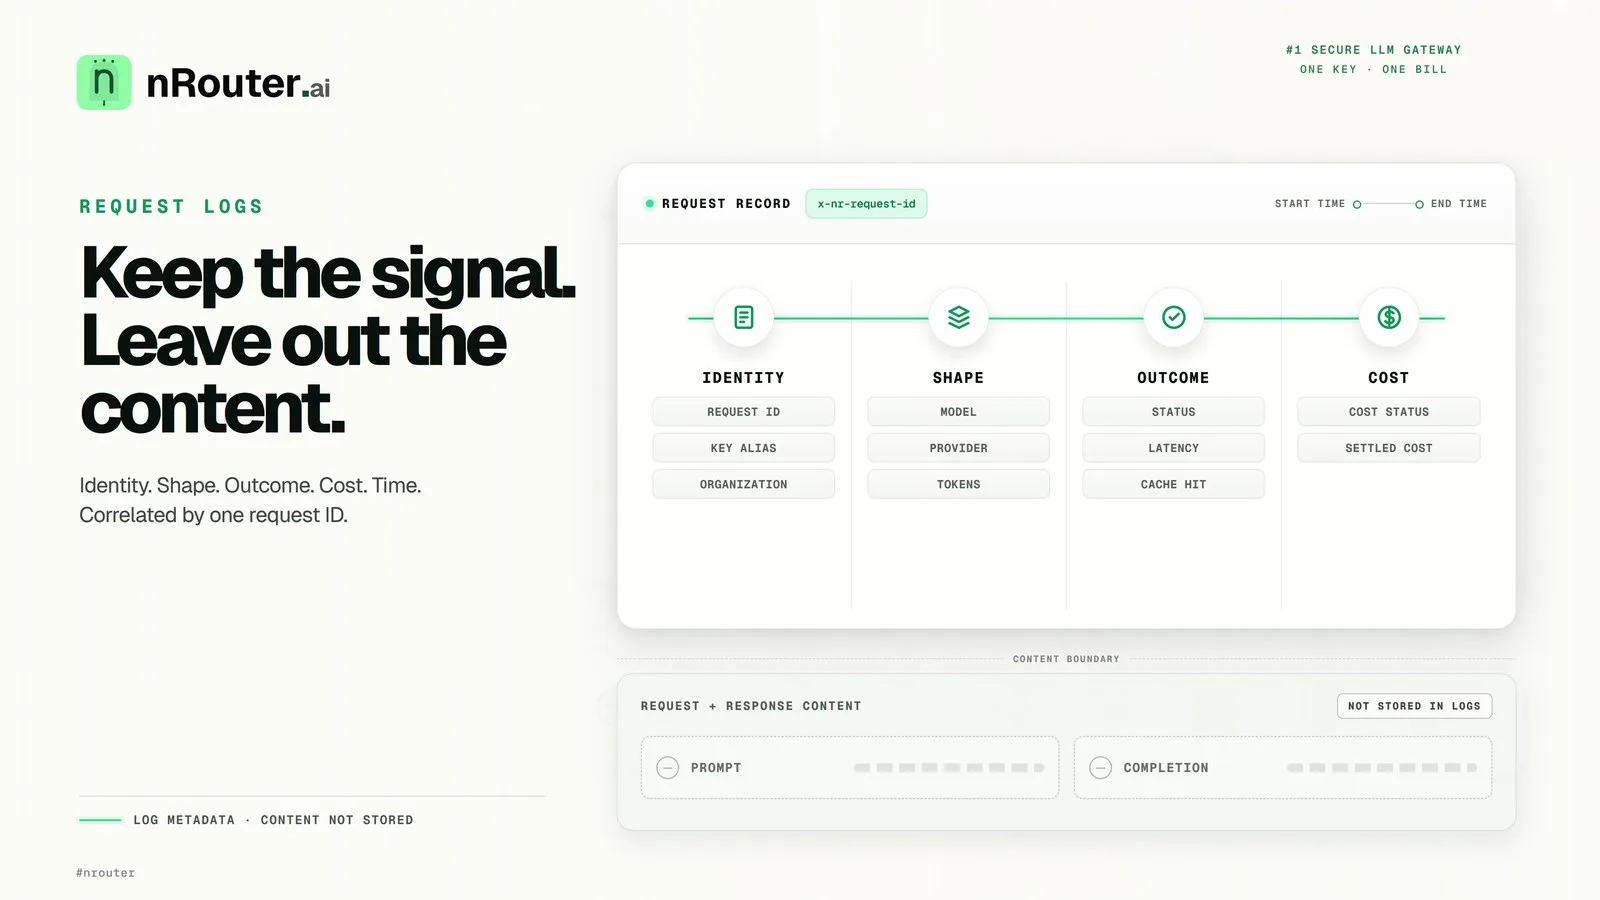
What an LLM Request Log Should Contain — and What to Leave Out
Guides

What an LLM Request Log Should Contain — and What to Leave Out

The fields that make an LLM request log worth keeping, the content that turns it into a liability, and how a gateway's built-in logs compare with running your own self-hosted trace store.

Sugumar
10 minRead →
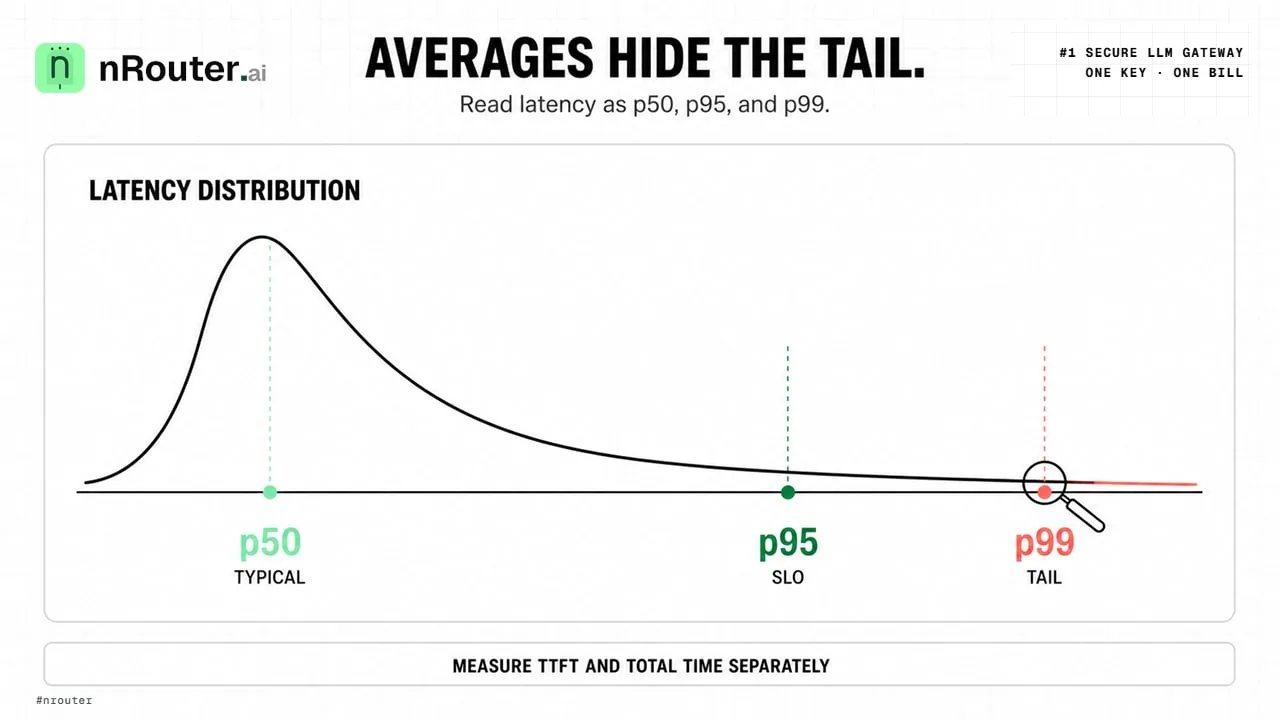
LLM Latency: p50, p95, p99, and Time-to-First-Token
Engineering

LLM Latency: p50, p95, p99, and Time-to-First-Token

Why average LLM latency misleads, how to analyze p50/p95/p99 distributions and time-to-first-token, and how to isolate tail delays across model providers.

Suresh
11 minRead →
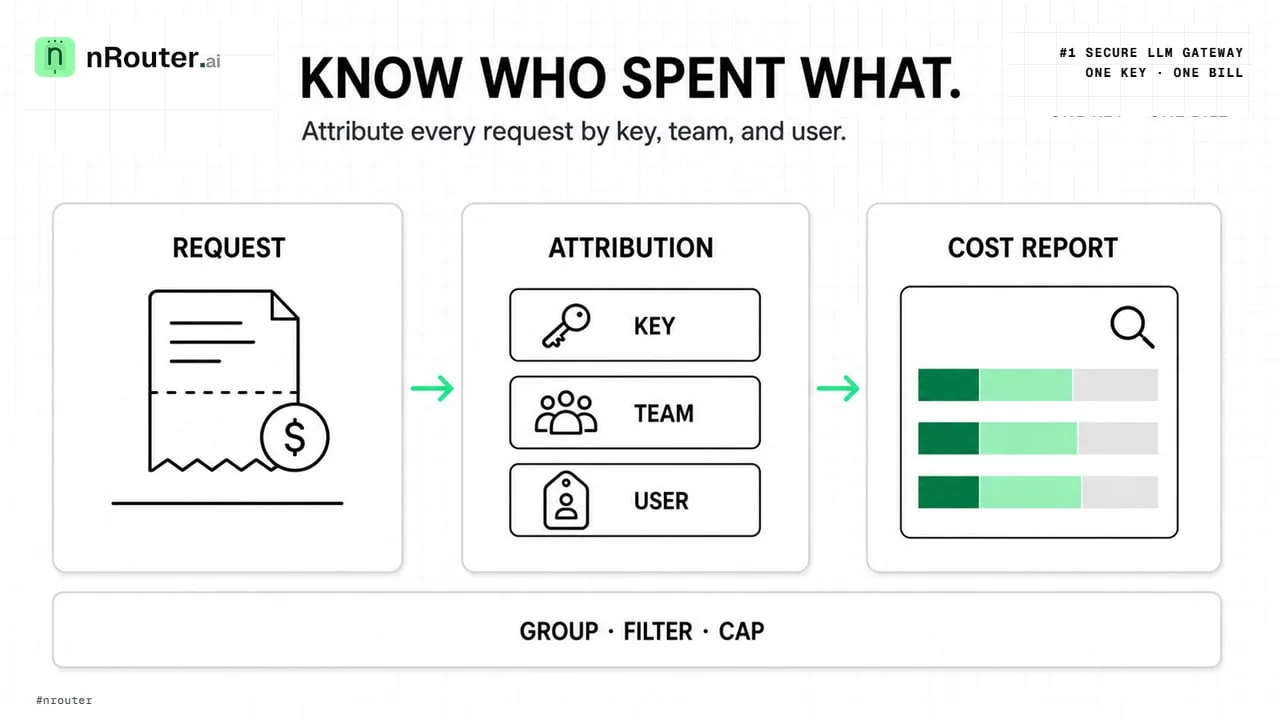
LLM Cost Attribution: Keys, Teams, and the user Field
Guides

LLM Cost Attribution: Keys, Teams, and the user Field

"The AI bill went up" becomes a query once spend carries structure. Three attribution layers — virtual keys, teams, and the OpenAI-spec user field — turn one opaque total into a breakdown you can group, filter, and cap.

Sugumar
10 minRead →
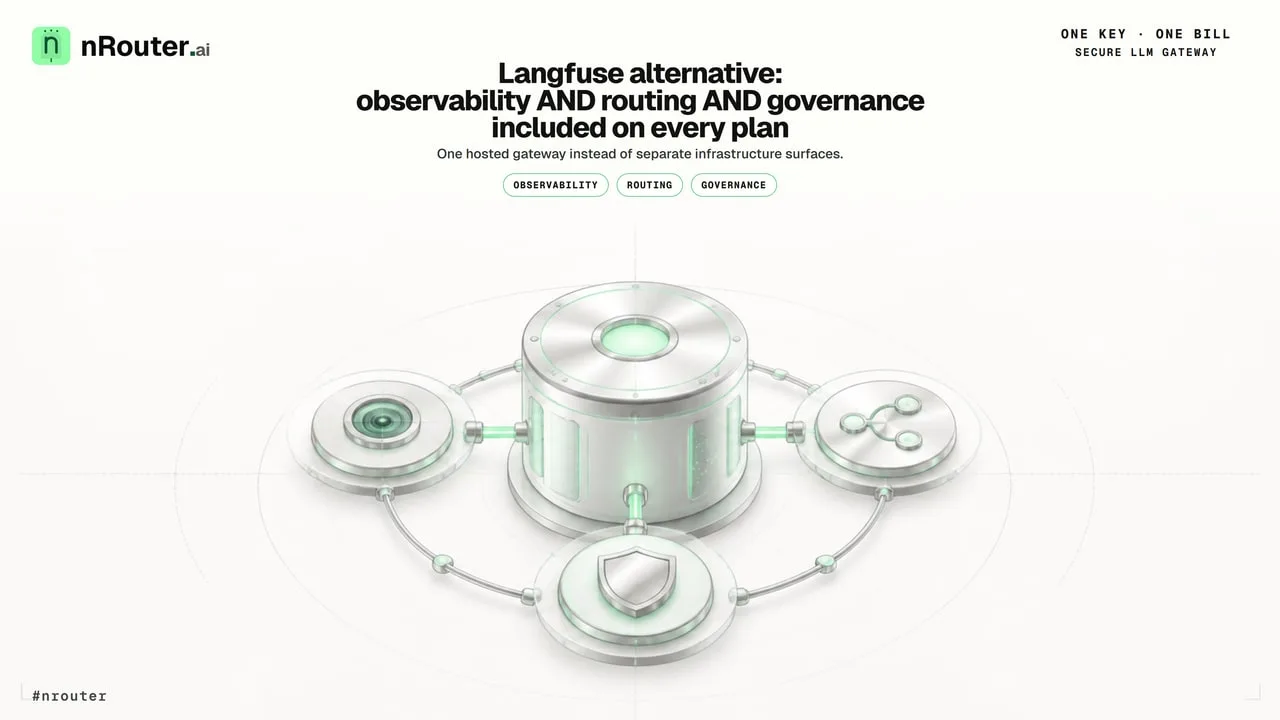
Langfuse alternative: observability AND routing AND governance included on every plan
Comparison

Langfuse alternative: observability AND routing AND governance included on every plan

Head-to-head: nRouter vs Langfuse. A self-hostable observability + prompt + evals specialist vs a hosted LLM gateway that bundles observability, routing, and governance — every feature included on every plan. A 0% platform fee on pay as you go. Models available in your live catalog behind one API key.

nRouter TeamnRouter Team
20 minRead →
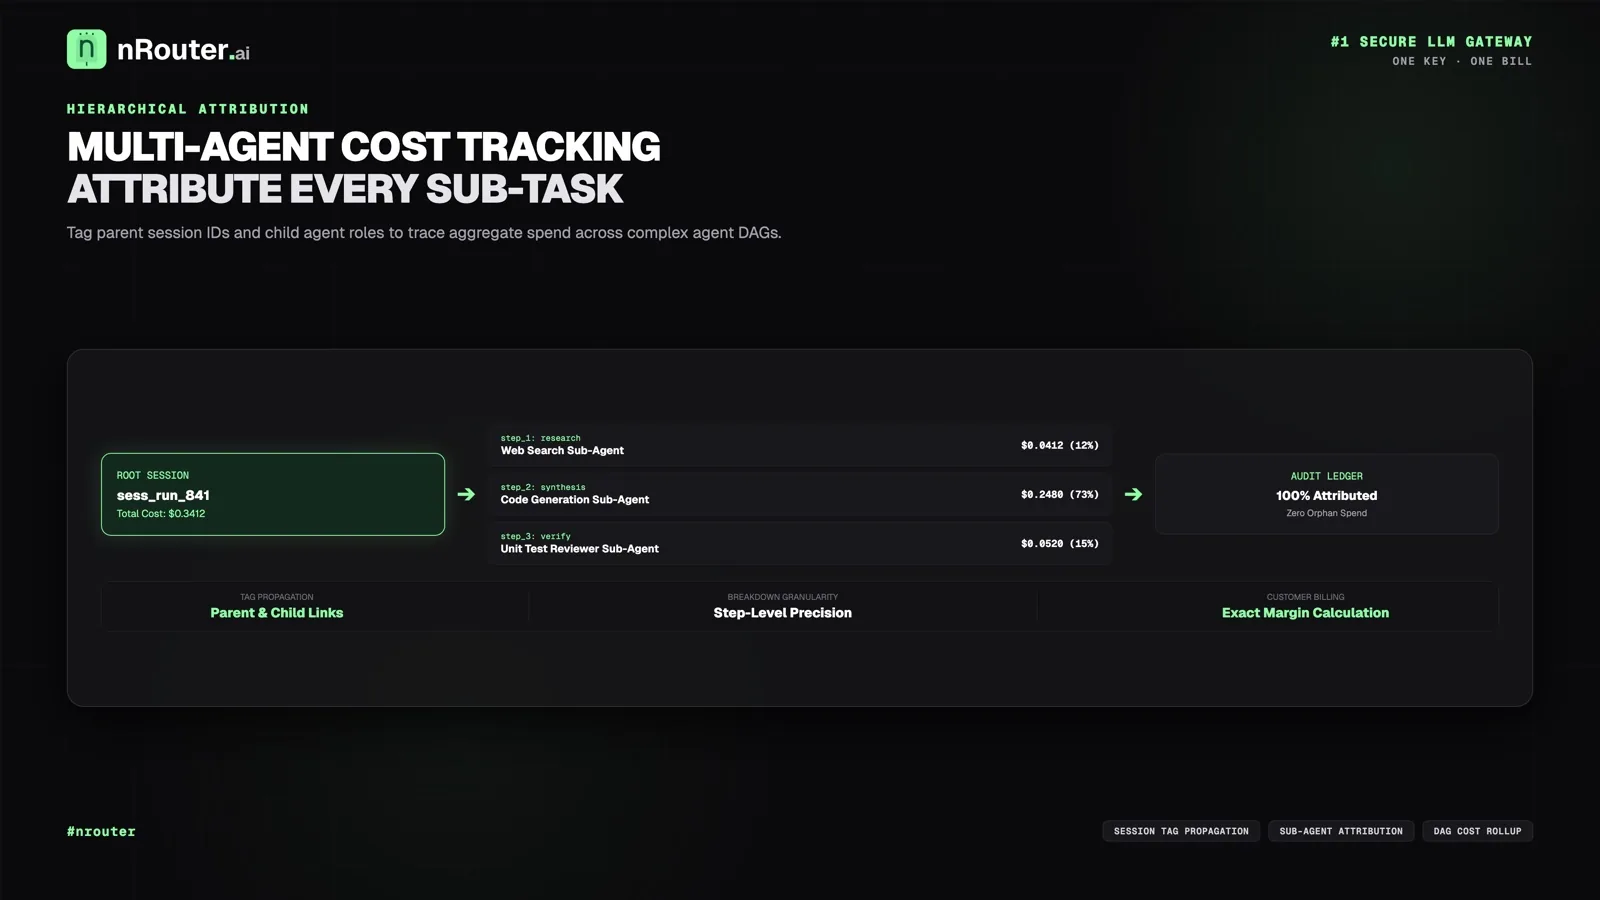
Multi-Agent Cost Tracking: Attributing Spend Across an Agent Run
Engineering

Multi-Agent Cost Tracking: Attributing Spend Across an Agent Run

Attribute LLM spend across multi-agent workflows by role, run, and step, reconcile usage against the credit ledger, and enforce hard gateway budget caps.

Suresh
11 minRead →