Tag

llm-routing

15 posts tagged "llm-routing".

Editorial Guide

Intelligent LLM Routing: Intent Classification & Latency Optimization

Static routing to a single frontier foundation model is financially inefficient and operationally fragile. Intelligent LLM routing dynamically matches incoming prompt complexity, modality requirements, and service level objectives with the optimal downstream model and provider deployment. By classifying prompt intent in real time, intelligent routing architectures slash token expenditure by up to 70% while improving response latency and uptime.

Key Engineering Challenges

Overpaying for Trivial Queries

Routing simple chitchat, classification, or extraction queries to costly frontier models (like GPT-4o or Claude 3.5 Sonnet) unnecessarily inflates token spend when smaller, faster models (such as GPT-4o-mini or Gemini 2.0 Flash) provide equivalent accuracy.

Provider Outages and Rate Limiting

Single-provider architectures suffer downtime during provider incidents or sudden tier exhaustion. Systems need dynamic fallback chains that automatically switch deployments within milliseconds.

Latency vs. Cost Trade-Off Optimization

Balancing cost constraints against strict time-to-first-token SLAs requires continuous evaluation of provider queue depths, historical response latencies, and regional geographic proximity.

Context Window and Modality Constraints

Intelligent dispatchers must inspect token counts, multimodal attachments (images, audio, video), and tool schemas to filter only candidate models capable of serving the exact request specification.

Architecture Taxonomy & Core Components

Strategy::Intent Classifier

11-intent categorization engine distinguishing light tasks from complex multi-step reasoning.

Dynamic Fallback Matrix

Configurable tier cascades with per-org retry budgets, timeout thresholds, and automated cooldowns.

Capability Filter Pre-Gate

Evaluates context ceilings, tool-calling support, and vision capabilities before candidate ranking.

nRouter Algorithmic Intent & Priority Routing

nRouter implements Strategy::Intent to categorize incoming prompts across 11 distinct intent categories—from light tasks (chitchat, simple QA, summarization) to heavy computational tasks (code synthesis, mathematical reasoning, agentic planning). During Preflight Phase 3, nRouter calculates intent scoring alongside moderation, resolving the winning model tier before credit reservation. If a primary provider degrades or encounters rate limits, nRouter transparently executes configured fallback chains across alternative providers without dropping client streams. All models are billed at their exact upstream list prices with zero per-token markup.

Examine our engineering guides on smart routing algorithms, fallback chain patterns, and multi-model cost reduction below.

Posts

Latest first

Measure TTFT and Trace an LLM Request Step by Step in Python
Guides

Measure TTFT and Trace an LLM Request Step by Step in Python

Send an nrouter/auto request with the Python SDK, read routing, guardrails and cost from its headers, fetch the request back by id, print every gateway step with its start, end and duration, then measure TTFT and latency over N runs.

nRouter TeamnRouter Team
12 minRead →
Two Ways to Ask for a Model: Direct, or nrouter/auto
Product

Two Ways to Ask for a Model: Direct, or nrouter/auto

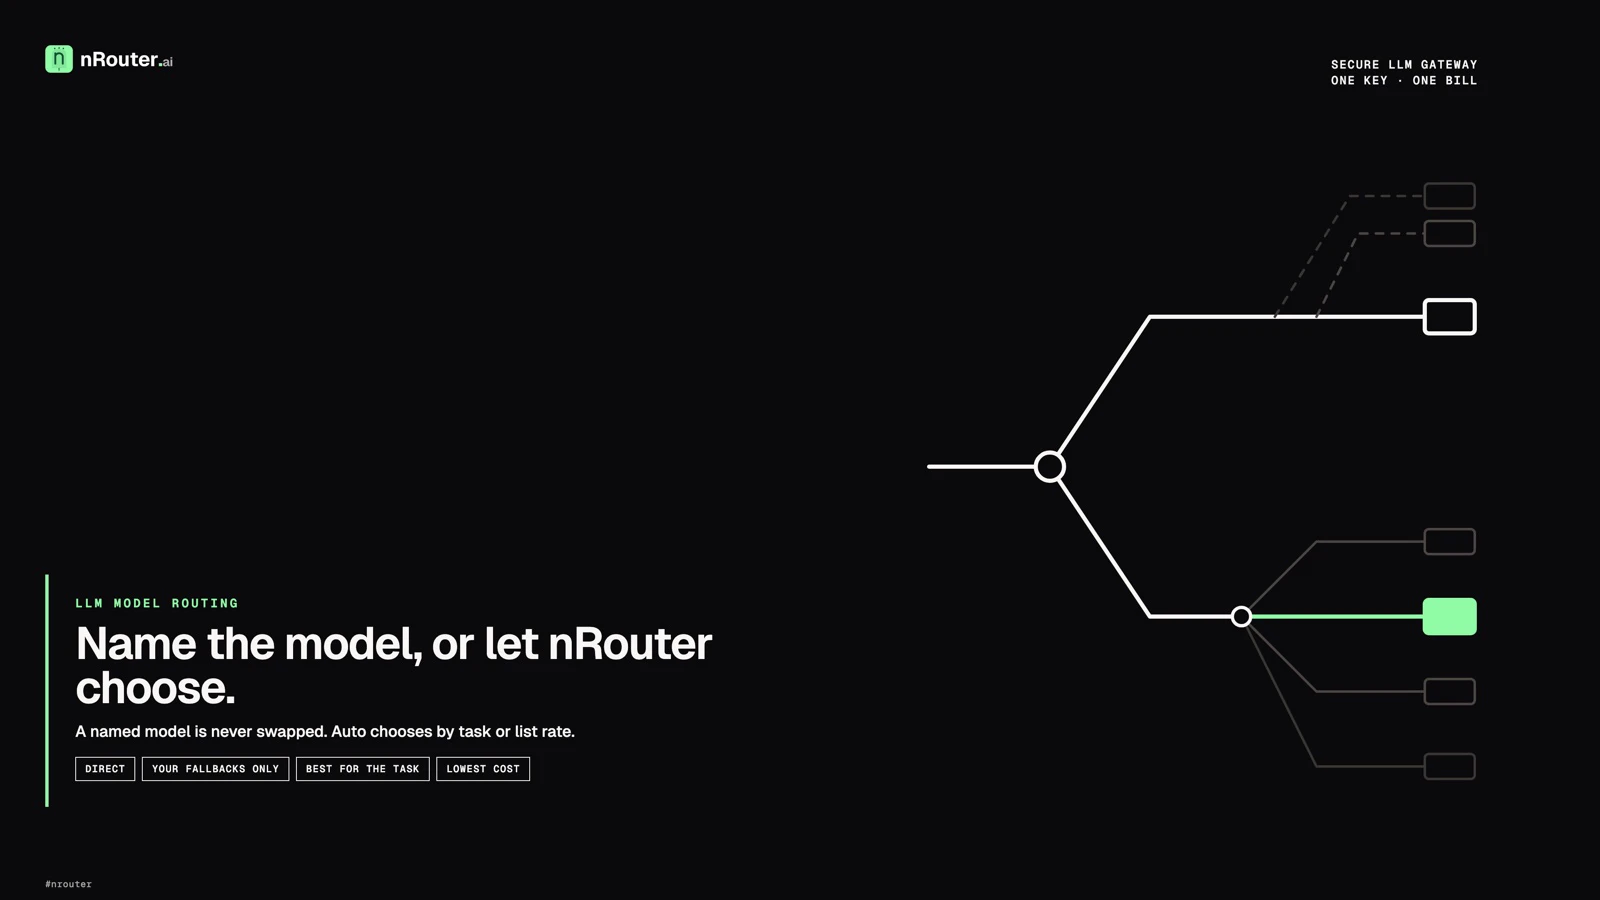
nRouter gives you two ways to ask for a model. Name one and it is never swapped, except through a fallback you configured. Send nrouter/auto and nRouter chooses, by Best for the task or Lowest cost.

nRouter TeamnRouter Team
9 minRead →
Warm Connection Pools in an LLM Gateway, and What They Do Not Fix
Engineering

Warm Connection Pools in an LLM Gateway, and What They Do Not Fix

What a reused provider connection saves an LLM request, what it cannot save, and how to measure the gateway's share of your latency instead of trusting a headline number.

Suresh
11 minRead →
Latency Routing and Automatic Failover Without Retry Code
Guides

Latency Routing and Automatic Failover Without Retry Code

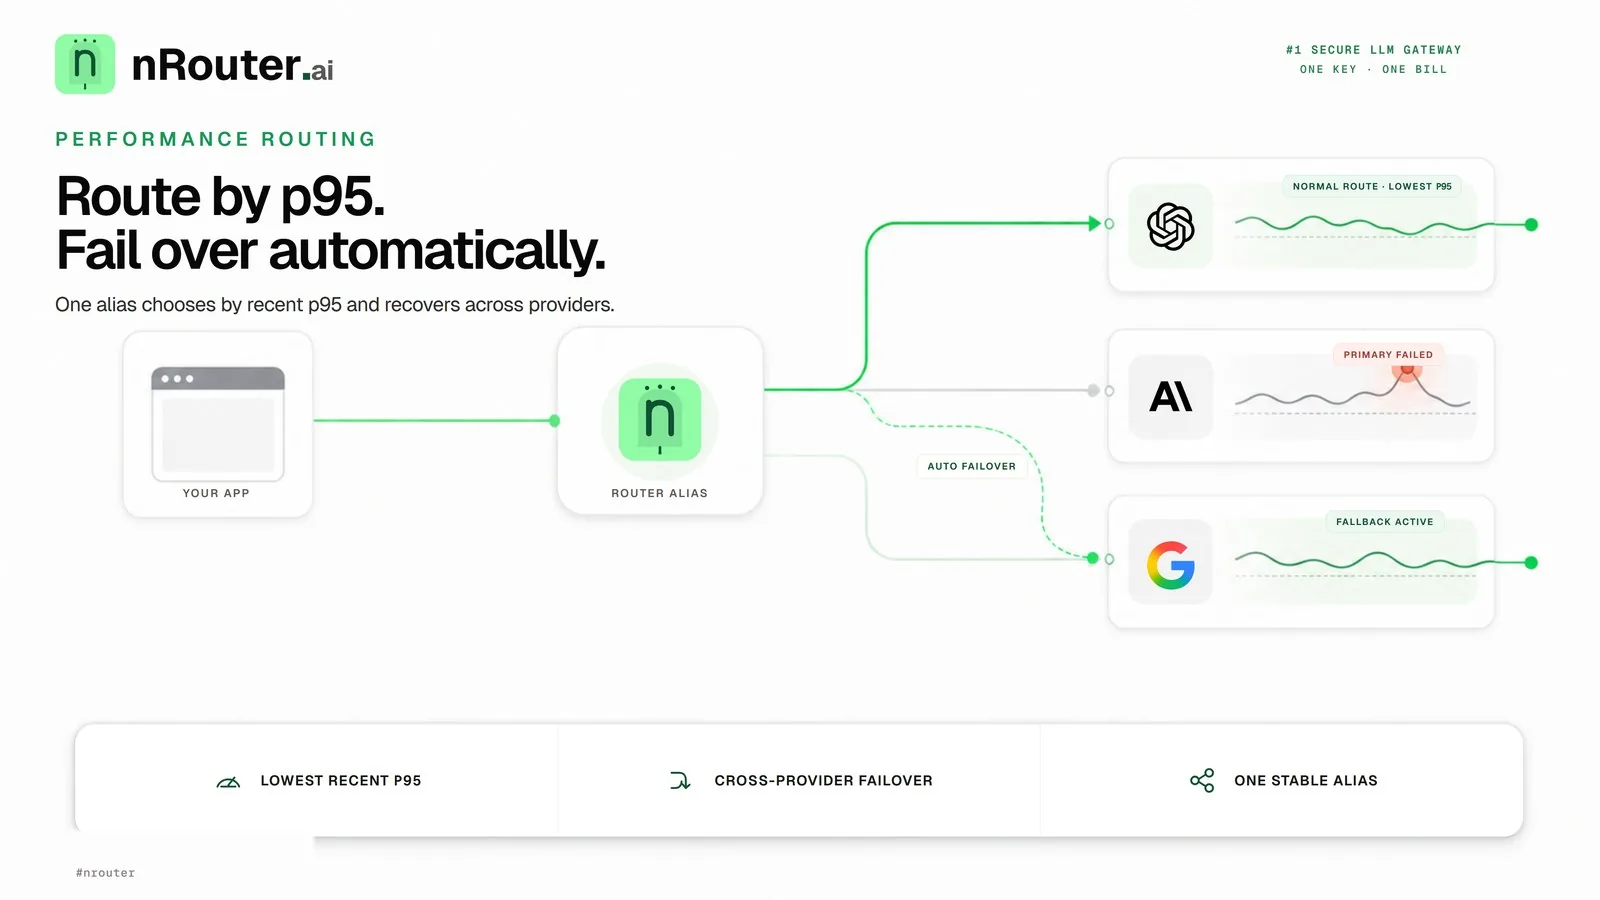
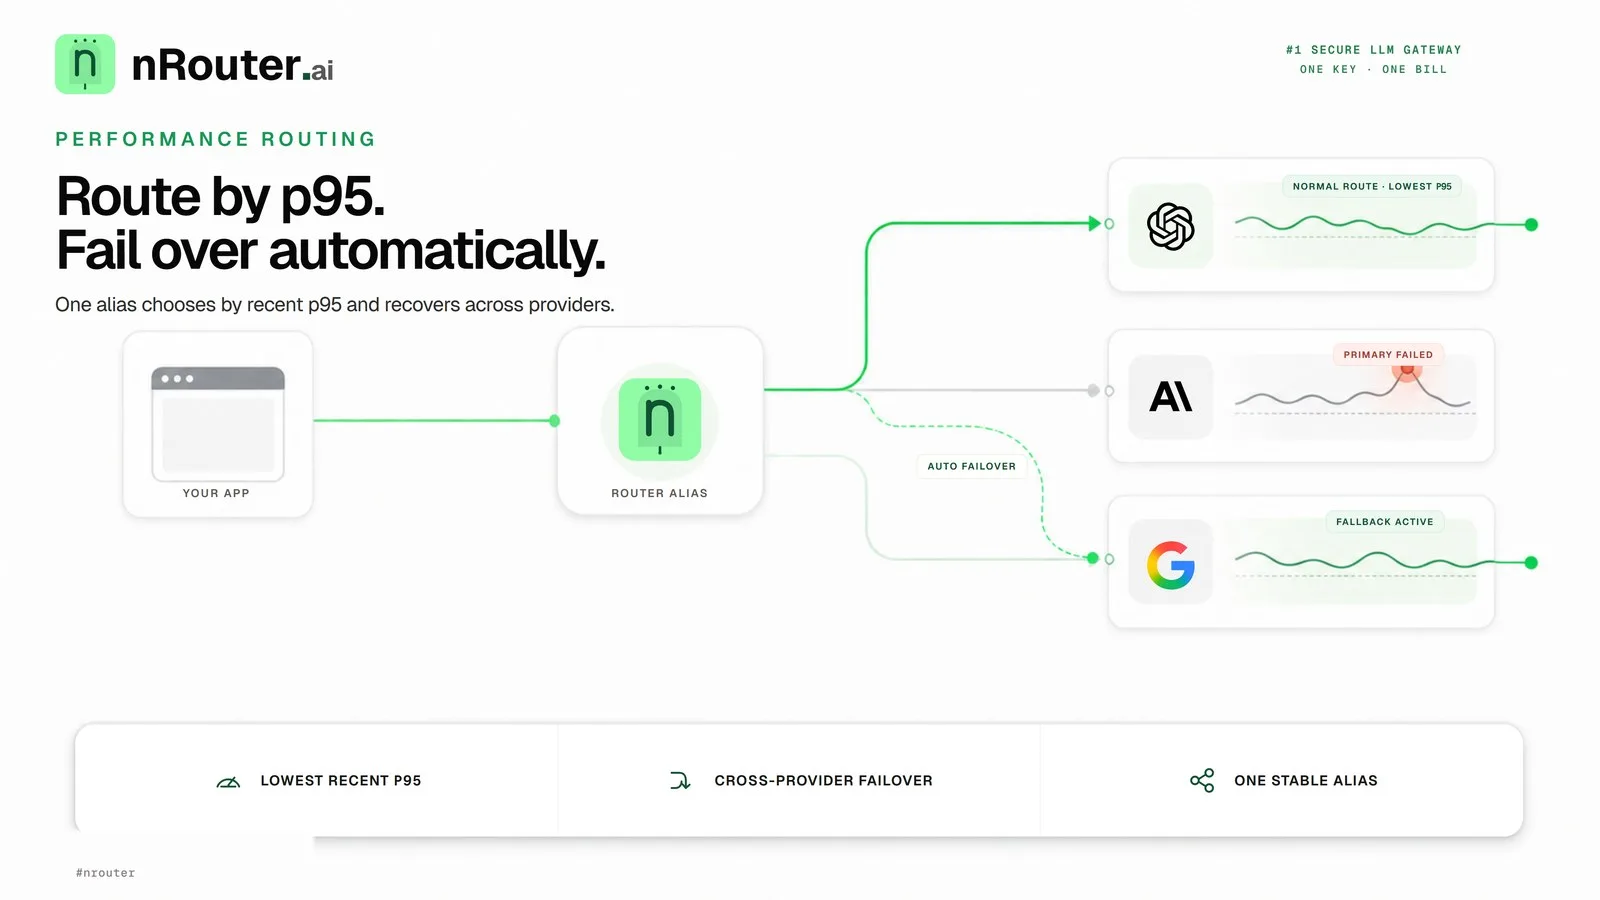
Measure candidate model latency, configure explicit fallbacks, understand the gateway attempt budget, and verify the result on your own p95.

Sugumar
11 minRead →
Cut LLM Costs by Routing, Not by Rewriting Your App
Product

Cut LLM Costs by Routing, Not by Rewriting Your App

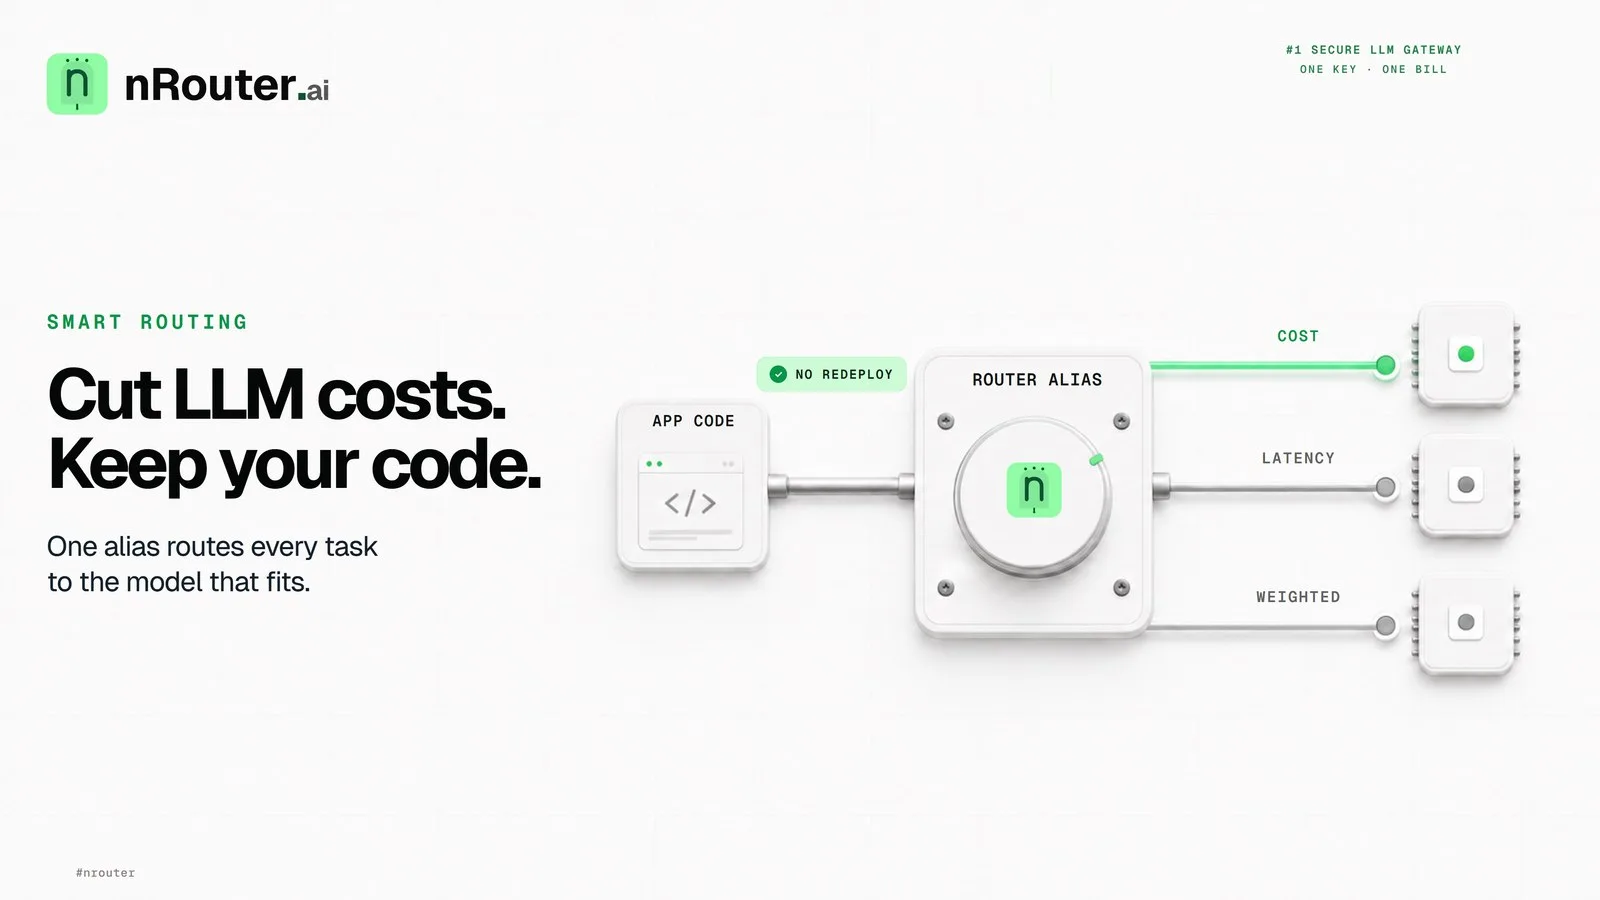
Routing is the one cost lever you can pull from a dashboard. Compare eligible models, use Best for the task or Lowest cost, and measure what a request costs without touching a line of application code.

Suresh
11 minRead →
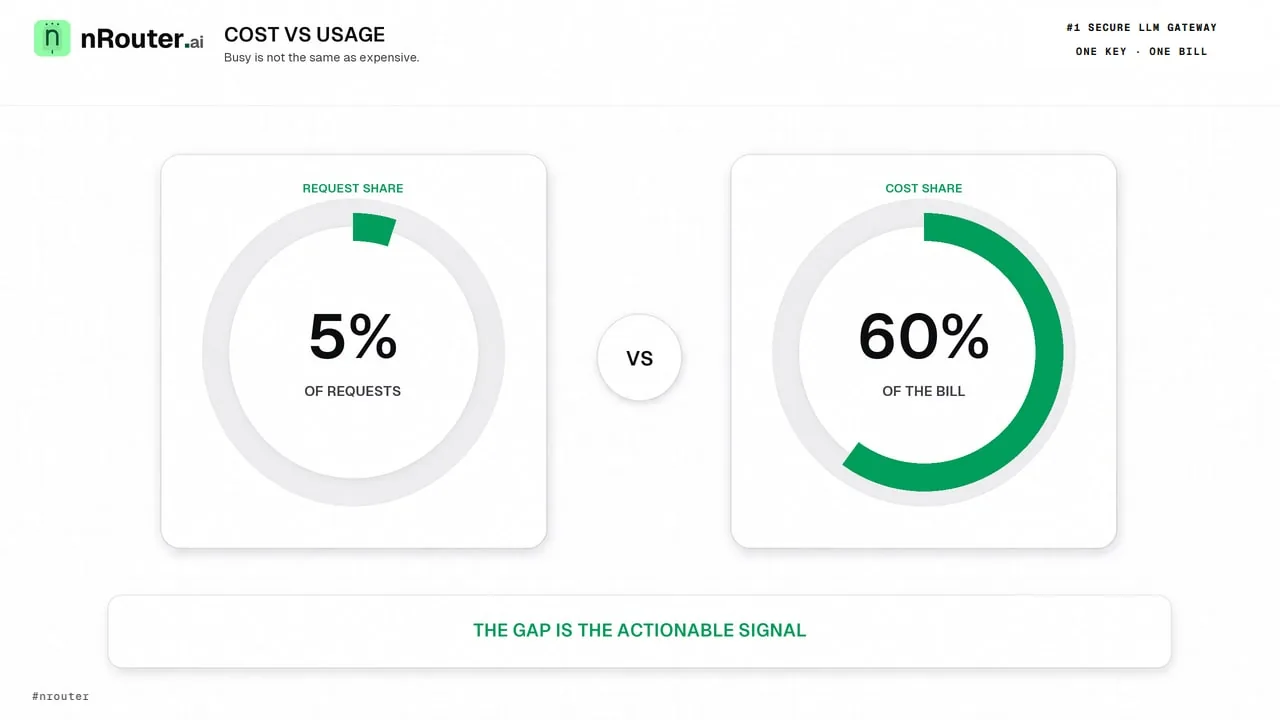
5% of Requests, 60% of the Bill: Reading Cost Against Usage
Engineering

5% of Requests, 60% of the Bill: Reading Cost Against Usage

Request count and dollar cost tell different stories, and the gap between them is where the savings are. Here are the four shapes an overlay of cost and usage produces, which one to chase first, and what makes the numbers trustworthy enough to act on.

Suresh
11 minRead →
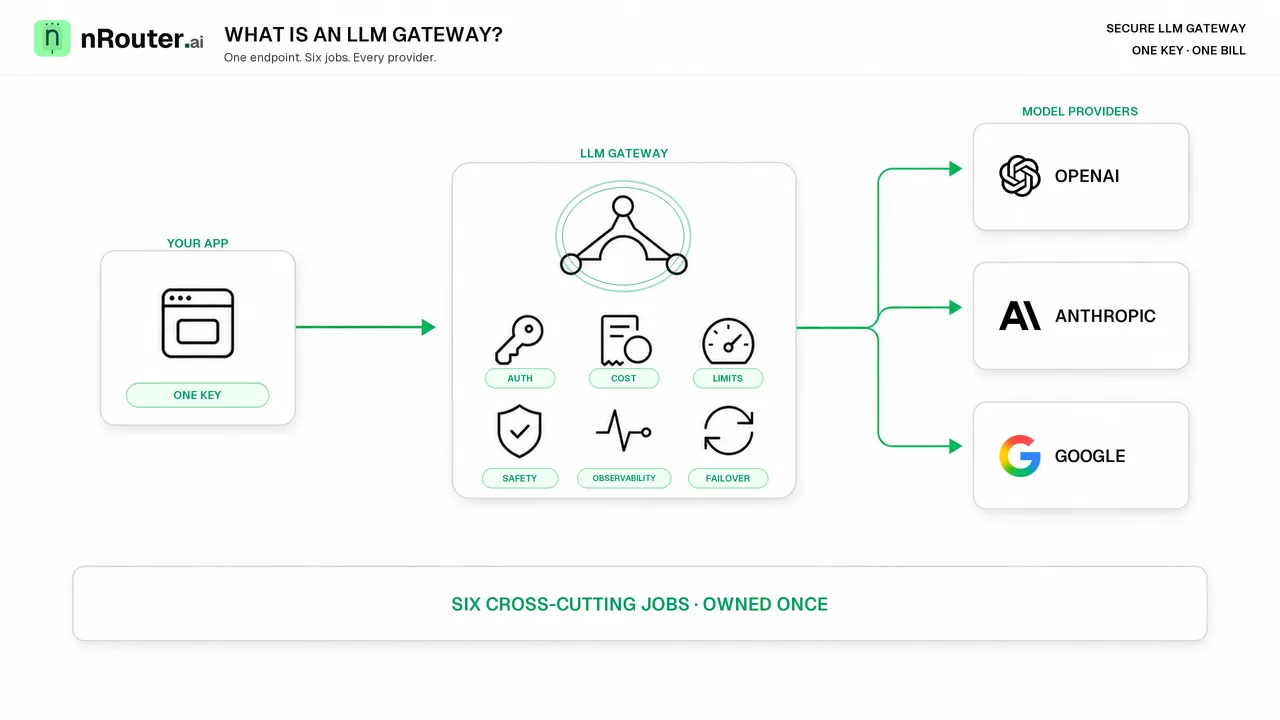
What Is an LLM Gateway? The Six Jobs It Takes Off Your Code
Guides

What Is an LLM Gateway? The Six Jobs It Takes Off Your Code

An LLM gateway is one endpoint in front of every model provider that owns six cross-cutting jobs — auth, cost, limits, safety, observability and failover. What it does, what happens to a request inside it, and when you need one.

Sugumar
11 minRead →
Cost-vs-Quality LLM Routing: Which Tasks Can Go Cheap
Guides

Cost-vs-Quality LLM Routing: Which Tasks Can Go Cheap

Quality is a property of a task, not of a model. Here is how to inventory your traffic by task, compare eligible models with nrouter/auto, prove each downgrade with an A/B test, and read the saving off the Cost vs Usage report.

Sugumar
11 minRead →
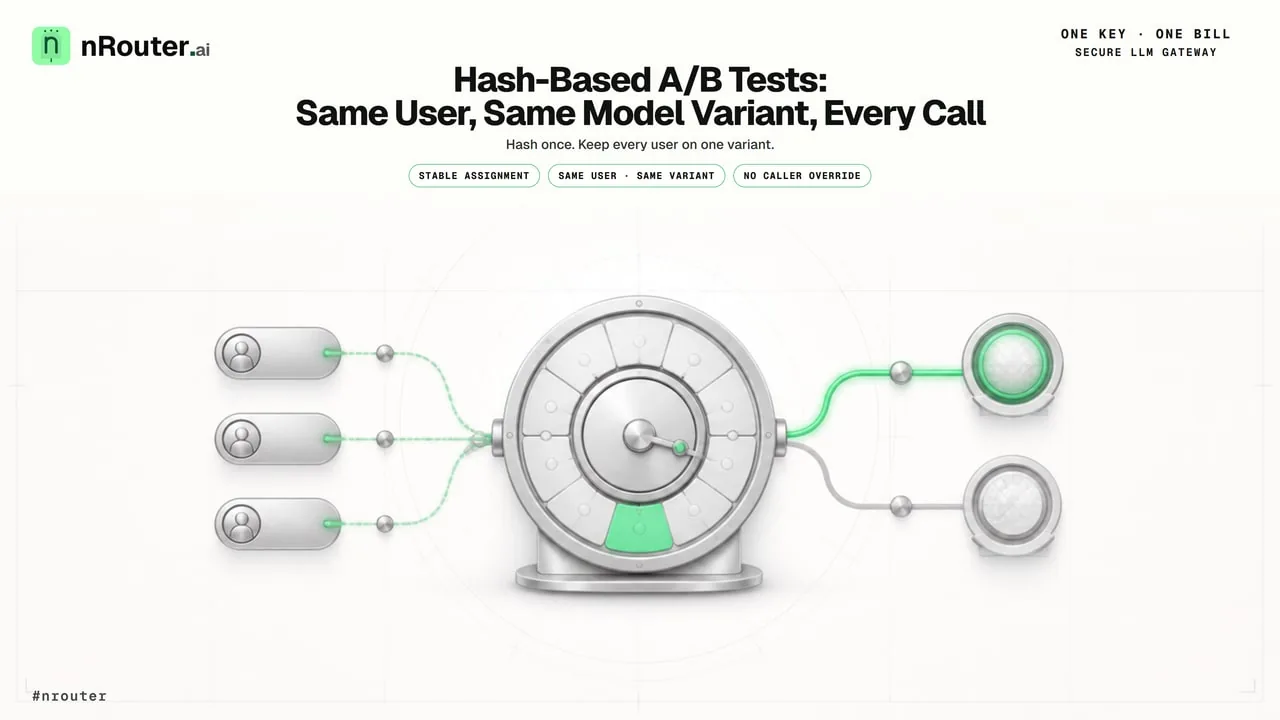
Hash-Based A/B Tests: Same User, Same Model Variant, Every Call
Engineering

Hash-Based A/B Tests: Same User, Same Model Variant, Every Call

A coin flip on every request is not an experiment — it is noise with a dashboard. Here is how deterministic hash-based assignment gives each user a stable variant for the life of a test, why the experiment id belongs in the hash, and what the gateway refuses to let a caller override.

Suresh
11 minRead →
Provider Fallback Chains: Surviving an OpenAI Outage
Engineering

Provider Fallback Chains: Surviving an OpenAI Outage

How an ordered LLM fallback chain reroutes failing requests to healthy providers, advances only on retryable errors, and bills spend for exactly one hop.

Suresh
11 minRead →
LLM routing strategies 2026: benchmark-anchored vs ML-classifier vs operator-controlled — how to pick the routing intelligence that fits your team
Buyer's Guide

LLM routing strategies 2026: benchmark-anchored vs ML-classifier vs operator-controlled — how to pick the routing intelligence that fits your team

Vendor-neutral buyer's-guide decision tree across the three durable LLM routing-intelligence shapes — benchmark-anchored (Unify-style), ML-classifier (NotDiamond-style), and operator-controlled (nRouter-style). Three questions, one shape, one product. Pick the failure mode your team is best equipped to own.

nRouter TeamnRouter Team
13 minRead →
NotDiamond alternative: router versus managed LLM gateway
Comparison

NotDiamond alternative: router versus managed LLM gateway

Not Diamond returns a model recommendation and charges $0.05 per million tokens routed — you still hold every provider key and make the call yourself. What that leaves you to build, and how deterministic A/B tests compare to a trained router when you have to reproduce a decision.

nRouter TeamnRouter Team
12 minRead →
Unify AI alternative: measure quality-per-dollar on your own traffic
Comparison

Unify AI alternative: measure quality-per-dollar on your own traffic

nRouter vs Unify AI for teams weighing benchmark-driven model arbitration against operator-pinned routing. Why a vendor leaderboard is not your eval, and how to compute cost-per-passing-answer from your own requests.

nRouter TeamnRouter Team
12 minRead →
LLM gateway buyer's guide 2026: routing, guardrails, evals, prompt management
Buyer's Guide

LLM gateway buyer's guide 2026: routing, guardrails, evals, prompt management

Eight axes that actually matter when picking an LLM gateway in 2026. Shortlist matrix across OpenRouter, Portkey, Helicone, nRouter. Decision tree by buyer profile, 90-minute evaluation.

nRouter TeamnRouter Team
14 minRead →
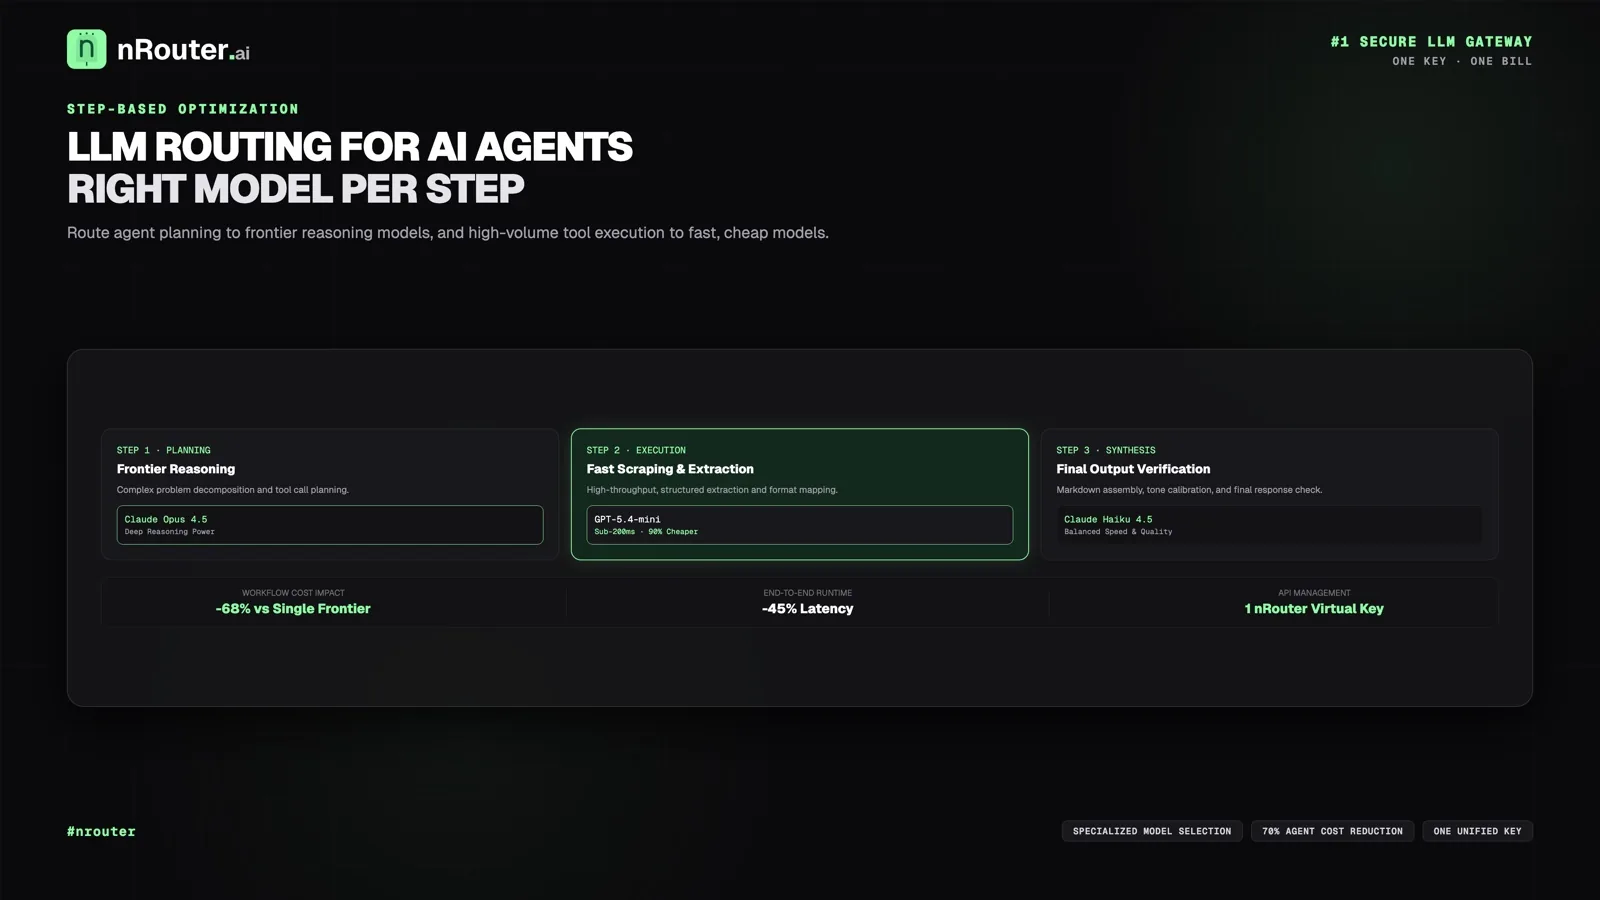
LLM Routing for AI Agents: One Model Per Step, One Key
Engineering

LLM Routing for AI Agents: One Model Per Step, One Key

Route each agent step to the model that fits its complexity, survive mid-chain provider outages, and capture one settled cost per run with an LLM gateway.

Suresh
11 minRead →