


Claude Proxy: One Base URL for Budgets, Fallback and Cost Data
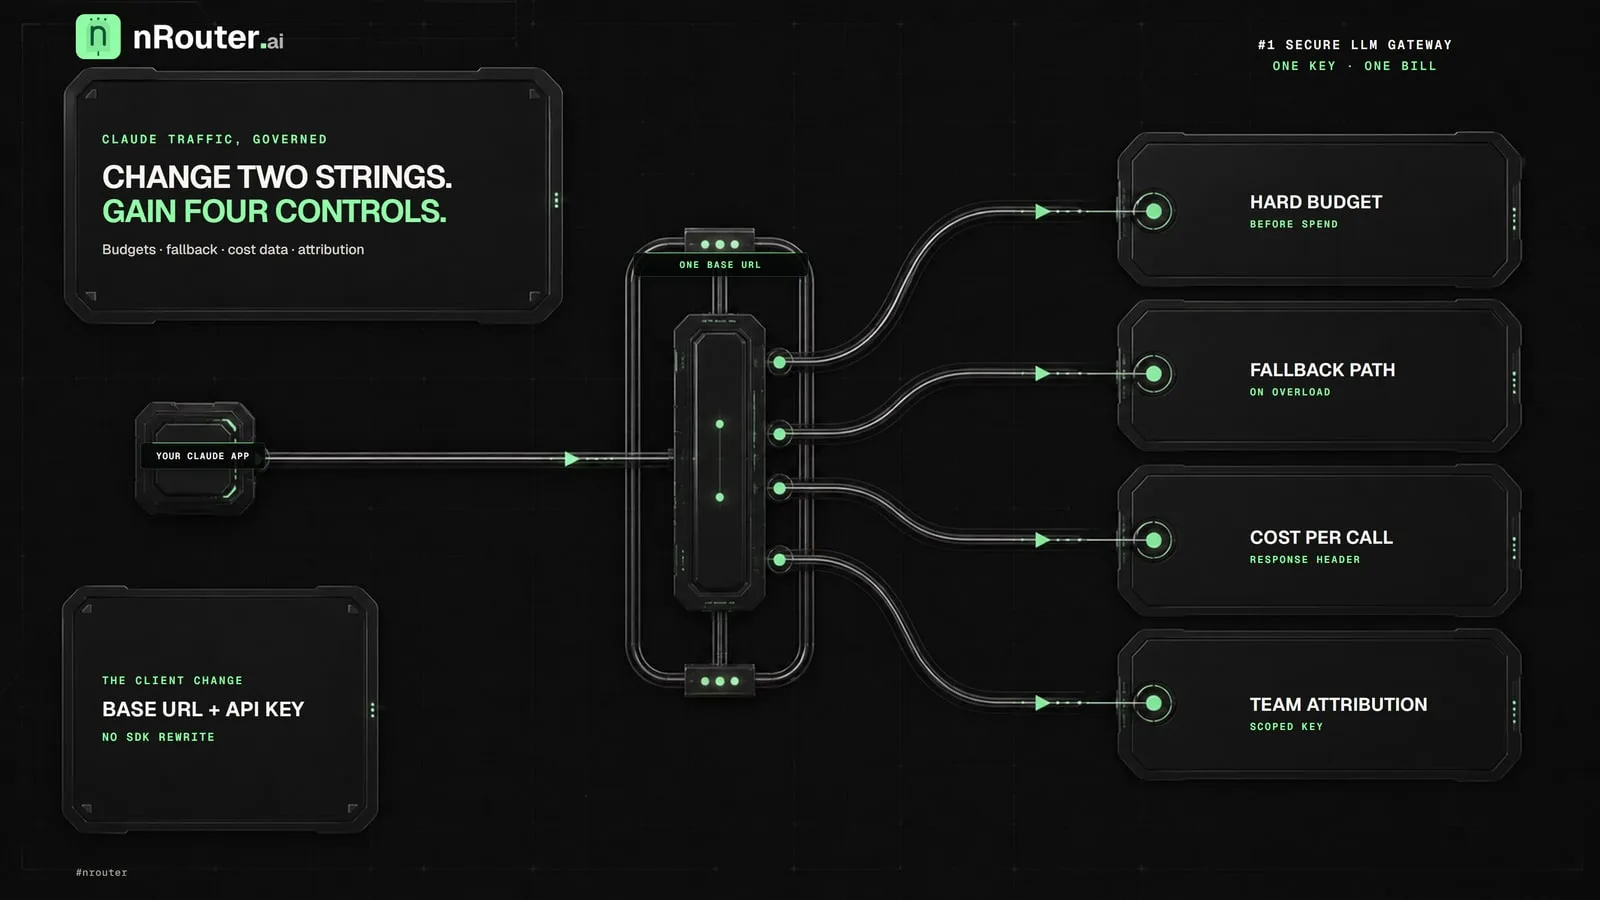
Point your Anthropic client at one gateway base URL and every Claude call arrives with a hard budget, a fallback path, a per-request cost header, and a team it can be billed to. No SDK rewrite, no provider key to paste.
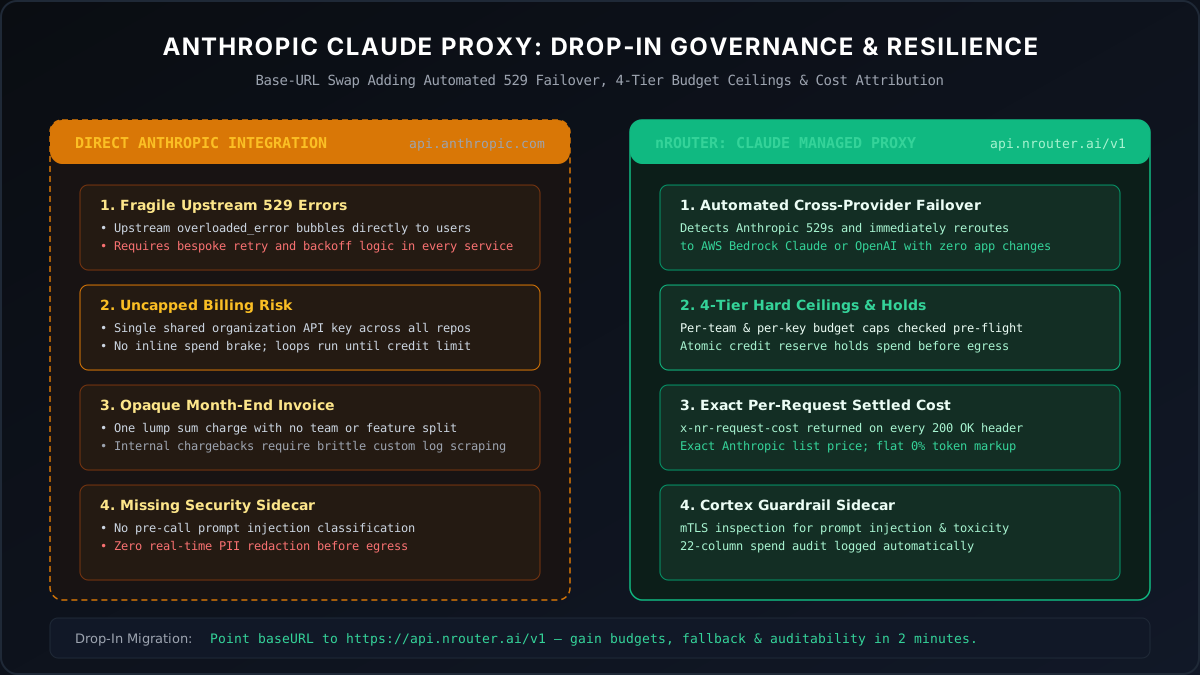
The Direct Answer: Calling Anthropic models directly risks application downtime during upstream 529 overloaded_error incidents, unbounded billing on runaway loops, and opaque monthly invoices. Setting up a Claude proxy via nRouter requires only swapping your client's base URL to https://api.nrouter.ai/v1. This immediately injects automated cross-provider failover (to AWS Bedrock Claude or OpenAI), 4-tier budget ceilings, real-time prompt injection defense, and exact per-call list price settlement with 0% token markup.
Figure 1: Managed Claude Proxy Architecture — Base-URL swap adding automated 529 failover, 4-tier budget ceilings, and per-team spend attribution.
What it does
A Claude proxy on nRouter is a base-URL change. Your existing Anthropic-shaped or OpenAI-shaped client keeps its code; every Claude call then passes through a place that can cap it, reroute it, price it, and attribute it to a team — and you never hold an Anthropic key.
The long version is barely longer. You change two strings — the base URL to https://api.nrouter.ai/v1 and the API key variable to NROUTER_API_KEY — and the request goes out to Anthropic exactly as it did before. The endpoint speaks the same OpenAI-compatible API your SDK already implements, so the client needs no rewrite. What changes is everything that wraps it: a ceiling that stops a runaway loop, a fallback path when the provider is overloaded, an exact cost on the response, and a spend row tagged with the team, the key and the model. Those four things are what teams are actually building when they type "Claude proxy" into a search box.
This post is about the capability as a customer uses it: what it does, how to turn it on, what one month of real traffic looks like costed out, and where it stops being the right answer.
Request flow
What happens inside nRouter when your app calls a model.
Your application
OpenAI SDK · sk-nrouter-…
nRouter Rust Gateway
direct customer inference
- Virtual-key auth · tenancy
- Route · IP · lifecycle policy
- Budgets · rate limits
- Pre-call guardrails
- Cortex sidecar
- Reserve credits
- Provider routing
Providers
- OpenAI
- Anthropic
- Vertex
- Azure
- Alibaba
response ↩ read cost · settle credits · log · stream back
Onboarding
From sign-up to your first API call in six steps.
Sign up
Email & password
Verify email
magic-link or pwd
Activate
Verify phone or add $5+
Set up team
Default auto-created
Create key
sk-nrouter-… (once)
First call
x-nr-* headers
One org per user · Default team auto-created · key shown once
Architecture
The services in the request path and where data lives.
Your application
nRouter Rust Gateway
Policy · tenancy · money
- Virtual-key auth · Guardrails
- Credits · Budgets · Rate limits
- Tenant derived from key row
Provider routing
- Provider transforms · Fallbacks
- Cost settle · Spend logging
- Canonical Postgres store
Providers
OpenAI · Anthropic · Google Vertex AI · Azure Foundry · Alibaba
What happens inside nRouter when your app calls a model.
The job it does for you
Here is the workflow most teams are running before a gateway sits in front of Claude, and the one that replaces it.
Before. An Anthropic key lives in a secret manager and is read by four services. When the monthly invoice arrives, it is one number for the whole organisation; splitting it by team means somebody wrote a log parser, and splitting it by customer means somebody wrote a better one. When Anthropic returns a 529 overloaded_error in real traffic, each service handles it differently, because each service's retry code was written by a different engineer in a different sprint. When a batch job loops, nobody finds out until the invoice. When security asks what a model saw, the answer is whatever your application happened to log.
After. Each service holds its own scoped key. Each key has a budget and a rate limit. The response to every call carries the cost of that call, so attribution is a sum rather than a reconstruction. A 529 is handled once, in one place, by a fallback chain you configured rather than four retry loops you maintain. A looping job stops at its ceiling with a specific error code, not at the end of the month.
The difference is not that the second list is impossible to build. It is that the second list is six separate builds — rate limiting, budgets, fallback chains, cost tracking, guardrails and request logging — and each one arrives on your backlog only after the incident that demanded it.
Claude and Anthropic are trademarks of Anthropic PBC. OpenAI is a trademark of OpenAI. nRouter is not affiliated with or endorsed by either. All provider claims below are sourced from their public documentation on the dates linked in
## Sources; if any have changed, email hello@nrouter.ai and we will correct this post.
What a Claude proxy has to do before it is useful
Teams that write their own proxy tend to write the same six features, and they tend to write them in this order — because the order is set by which production incident lands first.
| # | Capability | The incident that triggers it | Available on every plan |
|---|---|---|---|
| 1 | Retry and fallback on provider overload | First weekend of real traffic | Yes |
| 2 | Per-team and per-key spend attribution | First end-of-month invoice audit | Yes |
| 3 | Guardrails in front of every call | First security review | Yes |
| 4 | Budgets and alerts | First runaway script | Yes |
| 5 | Request and response logging to your own sink | First "what did the model actually see" debug | Yes |
| 6 | A/B testing one Claude model against another | First "is the cheaper model enough" question | Yes |
The column that matters is the last one. On nRouter these are not tiered: every feature is included, and nRouter sells one plan, pay as you go, at a 0% platform fee. Usage settles at the served model's exact list price (0% markup) rather than gating capabilities behind a subscription. The reasoning behind that pricing choice is in Every Feature on Every Plan: No Fee, No Gate.
How it works
The customer-visible contract has three parts: what you configure, what happens to a request, and what comes back.
What you configure. A virtual key, scoped to one organisation and one team. On that key: a budget ceiling, an RPM and TPM limit, and which models it may reach. Optionally a guardrail set and a fallback chain. All of it lives in the dashboard; none of it lives in your application code. The key/team/organisation scoping model is described in org, team, member.
What happens to a request. The key is authenticated and resolved to an organisation and a team. Pre-call guardrails run. The ceilings are checked before any money is spent — which matters, because a check that happens after the provider call is a bill you have already incurred. Credit is held against the call, the provider is called, and on the way back post-call guardrails run before the body reaches you. Then the hold is settled against the real cost. That reserve-then-settle shape is what stops a burst of concurrent calls from slipping past a ceiling, and it is worked through in reserve-and-settle.
What comes back. The provider's response, plus x-nr-* headers. The one to read first is x-nr-request-cost, the exact cost of that call, paired with x-nr-cost-status. When the cost cannot be determined, the cost header is absent and the status reads unpriced. It is never a zero, for the reason argued in cost honesty: a fabricated $0 is worse than a missing number, because a missing number gets investigated and a zero gets summed.
When a ceiling bites, the error is specific rather than generic:
| Ceiling | Status | Error code |
|---|---|---|
| Organisation, team or user budget | 402 | budget_exceeded |
| Per-key budget | 429 | key_budget_exceeded |
| Per-key RPM/TPM rate limit | 429 | rate-limit code naming the limit it hit |
Handling both families in a client is a small amount of code and is written out in handling 429 and 402.
Set it up
Ten minutes, and the only irreversible step is the first one.
- Create an account and load credits. Sign up, add a card, and load the $5 minimum; pay as you go from $5, 0% platform fee; a purchase charges exactly the credits bought ($5 costs $5.00).
- Create a virtual key. From the dashboard, create a key scoped to the team that owns the service you are migrating. The full
sk-nrouter-…value is shown exactly once; put it straight into your secret manager. The lifecycle is documented in API key management. - Put a ceiling on it before you use it. Set a budget and an RPM limit on the key at creation time, not after the first surprise. Budget controls covers both.
- Change two strings in the client. Base URL and key variable. Nothing else.
- Send one request and read the headers. Confirm the call succeeds and that
x-nr-request-costis present and plausible.
The client change, for an OpenAI Node SDK already pointed at Anthropic through something else — Anthropic documents the same OpenAI-shaped access to Claude on its own compatibility page, so the shape is not a nRouter invention:
  const client = new OpenAI({
-   baseURL: 'https://api.anthropic.com/v1/',
-   apiKey: process.env.ANTHROPIC_API_KEY,
+   baseURL: 'https://api.nrouter.ai/v1',
+   apiKey: process.env.NROUTER_API_KEY,
  });

  const reply = await client.chat.completions.create({
    model: 'claude-sonnet-5-5',
    messages: [{ role: 'user', content: 'Summarize this in one sentence.' }],
  });
And the verification step, which is the part people skip:
from openai import OpenAI
import os

client = OpenAI(
    base_url="https://api.nrouter.ai/v1",
    api_key=os.environ["NROUTER_API_KEY"],
)

resp = client.chat.completions.with_raw_response.create(
    model="claude-sonnet-5-5",
    messages=[{"role": "user", "content": "ping"}],
)

print(resp.headers.get("x-nr-request-cost"))   # absent when unpriced
print(resp.headers.get("x-nr-cost-status"))    # "exact" | "unpriced"
Which Claude models the key can reach is a live question rather than a fixed list — the models page is the current answer, and the full request/response contract is in the chat completions reference. If your service uses the Anthropic Messages shape rather than the OpenAI Chat Completions shape, you do not have to standardise your codebase first; both shapes are served from the same base URL.
Worked example with numbers
Take a support-automation team spending $6,000/month on Claude across three services, and work the two things a proxy changes: the overhead, and the attribution.
Overhead. nRouter sells one plan, pay as you go, at a 0% platform fee. Loading $6,000 of credits is charged exactly $6,000.00, nRouter absorbs the card-processing cost, and usage settles at the served model's exact list price (0% markup) — the platform overhead is $0.00 on this month's $6,000. The pricing details live on the pricing page.
No subscription plan is sold (existing subscribers keep theirs). Credit purchases pay the same 0% platform fee, and usage settles at exact list price with 0% markup. Details on plan economics live in from credits to Pro.
Attribution. Split the same $6,000 across three scoped keys and the invoice stops being one number:
| Key | Team | Share of spend | Monthly cost | Budget set |
|---|---|---|---|---|
support-triage | Support | 55% | $3,300 | $4,000 |
docs-summarizer | Docs | 30% | $1,800 | $2,200 |
internal-eval | Platform | 15% | $900 | $1,200 |
Those budgets are not decoration. If the eval harness loops overnight, it stops at $1,200 with a 429 key_budget_exceeded rather than at $9,000 with an invoice. The containment argument is the whole point of a scoped key, and it is argued properly in virtual keys vs master key. Adding tags to each call turns the same data into a per-customer or per-feature breakdown — see attribution tags.
What it costs
Plainly, from the pricing page:
- Pay as you go — $0 subscription, 0% platform fee; a credit purchase charges exactly the credits bought ($5 costs $5.00, $100 costs $100.00). nRouter absorbs card-processing costs; usage settles at the served model's exact list price (0% markup). No subscription plan is sold (existing subscribers keep theirs).
- Enterprise — custom terms, contact sales only. There is no self-serve checkout for it.
Two things that catch people out, so they are stated here rather than discovered in a procurement call. First, paid usage requires purchased credits: a card is required and a real $5 minimum charge is taken (a purchase charges exactly the credits bought). Second, the token rates themselves are the provider's — usage settles at the served model's exact list price with 0% markup. If you have negotiated committed-spend pricing directly with Anthropic, that rate does not travel through us; see ## Limits below.
Where it fits with the rest of the platform
A Claude proxy is one use of a control plane that does not care which provider is behind it. The adjacent capabilities, each with the post that covers it:
- Multi-provider routing. The same key reaches every model in your live catalog, so testing a non-Anthropic model against a Claude one is a string change, not an integration. Route by cost and quality is the decision framework.
- Guardrails. PII redaction and content rules run pre-call and post-call on every request, on every plan. Guardrails on every request.
- A/B testing. Compare two Claude models, or Claude against another family, on live traffic with a stable assignment. Deterministic A/B testing.
- Prompt management. Version prompts server-side so a wording change is not a deploy. Server-side prompt templates.
- Getting logs out. Request logs are viewable in the dashboard and exportable as CSV; delivery to Datadog, Langfuse, S3 or Slack is not available yet, so you send the response headers from your own code. LLM Logs in Datadog and Langfuse: What Works Today.
- Agent workloads. A coding agent is the most demanding case for the ceilings above. An LLM gateway for coding agents.
When calling Anthropic directly is still right
Some honest disqualification, because a capability post without it reads as a brochure.
- Small, single-service usage. One service, one key, nobody asking for attribution, a bill under a couple of hundred dollars a month. A direct call is correct and a gateway is overhead.
- A committed-spend contract with Anthropic. If you already beat public rates, run the arithmetic against your own rate card first. Our fee sits on a public rate.
- A hard rule against a third party in the request path. That is a compliance boundary, not a feature gap, and no capability argument changes it.
- You need a free evaluation. There is not one. The $5 minimum is a real charge.
Limits and what it will not do
- No BYOK. You cannot paste an Anthropic key and have us forward it. nRouter holds the provider relationship and you hold credits. The reasoning is in why we do not do BYOK, and it genuinely rules some teams out.
- We are a hop. A direct SDK call has one dependency; through us it has two. That is why the status page is public and fallback behaviour is documented rather than implied. The trade is argued in Managed LLM Gateway vs Self-Hosted: Why We Carry the Pager.
- Fallback does not make a retry free. A retried call is a second call to a provider and therefore a second charge. What the gateway guarantees is that the credit hold is taken once per customer request, not once per attempt — the failure mode and the fix are both in provider fallback chains.
- An unpriceable call is reported, not guessed. If a model's rate cannot be resolved,
x-nr-request-costis absent and the status isunpriced. Your reconciliation has to handle that state rather than treating a missing header as zero. - We do not log or retain bodies for you. Metadata is complete; bodies are not part of it. The one qualification is a short-lived serving cache — a response body may be held for a few minutes, keyed to your organisation and team, so a byte-identical repeat request skips the provider call. It is a cache and not a record: you cannot read it back, it is not exported, and it expires on its own. If you want the bodies, forward them to a sink you control and read what to log and not log first, because prompt text is personal data.
- SOC 2 Type II is in progress, not certified. If a procurement checklist needs a completed report today, say so early. Current posture is on the trust page.
Try it
When evaluating Claude access, eligible new accounts can receive $100 in promotional credits after email and phone verification, without a card. Promotional access has a restricted model set and spending limits; see current pricing and promotion terms.
Create an account at signup and load the $5 minimum (charging exactly $5.00, 0% platform fee). Create one key scoped to one team, put a small budget on it, change the two strings in a single service, and let it run for a day against real traffic. At the end of the day you will have a real per-request cost distribution for your Claude workload and exact list-price usage tracking. If you want the head-to-head against other gateways before committing, the comparisons live at /vs, and the vendor-neutral version of the evaluation is the LLM gateway buyer's guide.
See also
- Virtual keys vs master key — how to scope the keys in the attribution table so one bad job cannot become everyone's incident.
- Provider fallback chains: surviving an OpenAI outage — the mechanism behind the
529story, including the double-billing trap. - Handling 429 and 402 errors from an LLM gateway — the client-side half of the ceiling table above.
- From credits to Pro — plan economics and how pay-as-you-go credits operate.
- Why we do not do BYOK — the limit most likely to disqualify you, argued rather than asserted.
- An LLM gateway for coding agents — the same ceilings under the workload that stresses them hardest.
- Pricing — the 0% platform fee, pay as you go terms, and minimum purchase in their live form.
Sources
Verified 2026-08-23. If a linked page has changed since, email hello@nrouter.ai and we will re-audit this post.
- Anthropic rate limits: docs.anthropic.com/en/api/rate-limits — the per-organisation RPM/TPM limits referenced above, checked 2026-08-23.
- Anthropic error reference: docs.anthropic.com/en/api/errors — the
529 overloaded_errorthe fallback story turns on, checked 2026-08-23. - Anthropic's own OpenAI-SDK compatibility page: docs.anthropic.com/en/api/openai-sdk — evidence that the OpenAI request shape is a supported way to reach Claude, checked 2026-08-23.
- OpenAI Node SDK: github.com/openai/openai-node — the client in the diff above, and the
baseURLoption that makes the swap two strings, checked 2026-08-23. - Anthropic Messages API: docs.anthropic.com/en/api/messages — the native request shape served alongside the OpenAI Chat Completions shape, checked 2026-08-23.
- Anthropic pricing: anthropic.com/pricing — the per-model list rates usage settles against at 0% markup, checked 2026-08-23.
- OpenAI API reference: platform.openai.com/docs/api-reference — the Chat Completions contract
https://api.nrouter.ai/v1is compatible with, checked 2026-08-23. - nRouter plans and fees: nrouter.ai/pricing — pay as you go at a 0% platform fee, a credit purchase charges exactly the credits bought, $5 minimum purchase.
- nRouter live model catalog: nrouter.ai/models — which Claude models a key can reach today.
Anthropic and OpenAI are trademarks of their respective owners. nRouter is not affiliated with or endorsed by them.
Frequently asked questions
What does nRouter do for claude proxy?
A Claude proxy on nRouter is a base-URL change. Your existing Anthropic-shaped or OpenAI-shaped client keeps its code; every Claude call then passes through a place that can cap it, reroute it, price it, and attribute it to a team — and you never hold an Anthropic key.
What problem does nRouter solve for claude proxy?
Here is the workflow most teams are running before a gateway sits in front of Claude, and the one that replaces it.
What should teams know about a claude proxy has to do before it is useful?
Teams that write their own proxy tend to write the same six features, and they tend to write them in this order — because the order is set by which production incident lands first.
Senior SEO engineer at nRouter, focused on search, AEO, and content performance.
More from Product
All posts →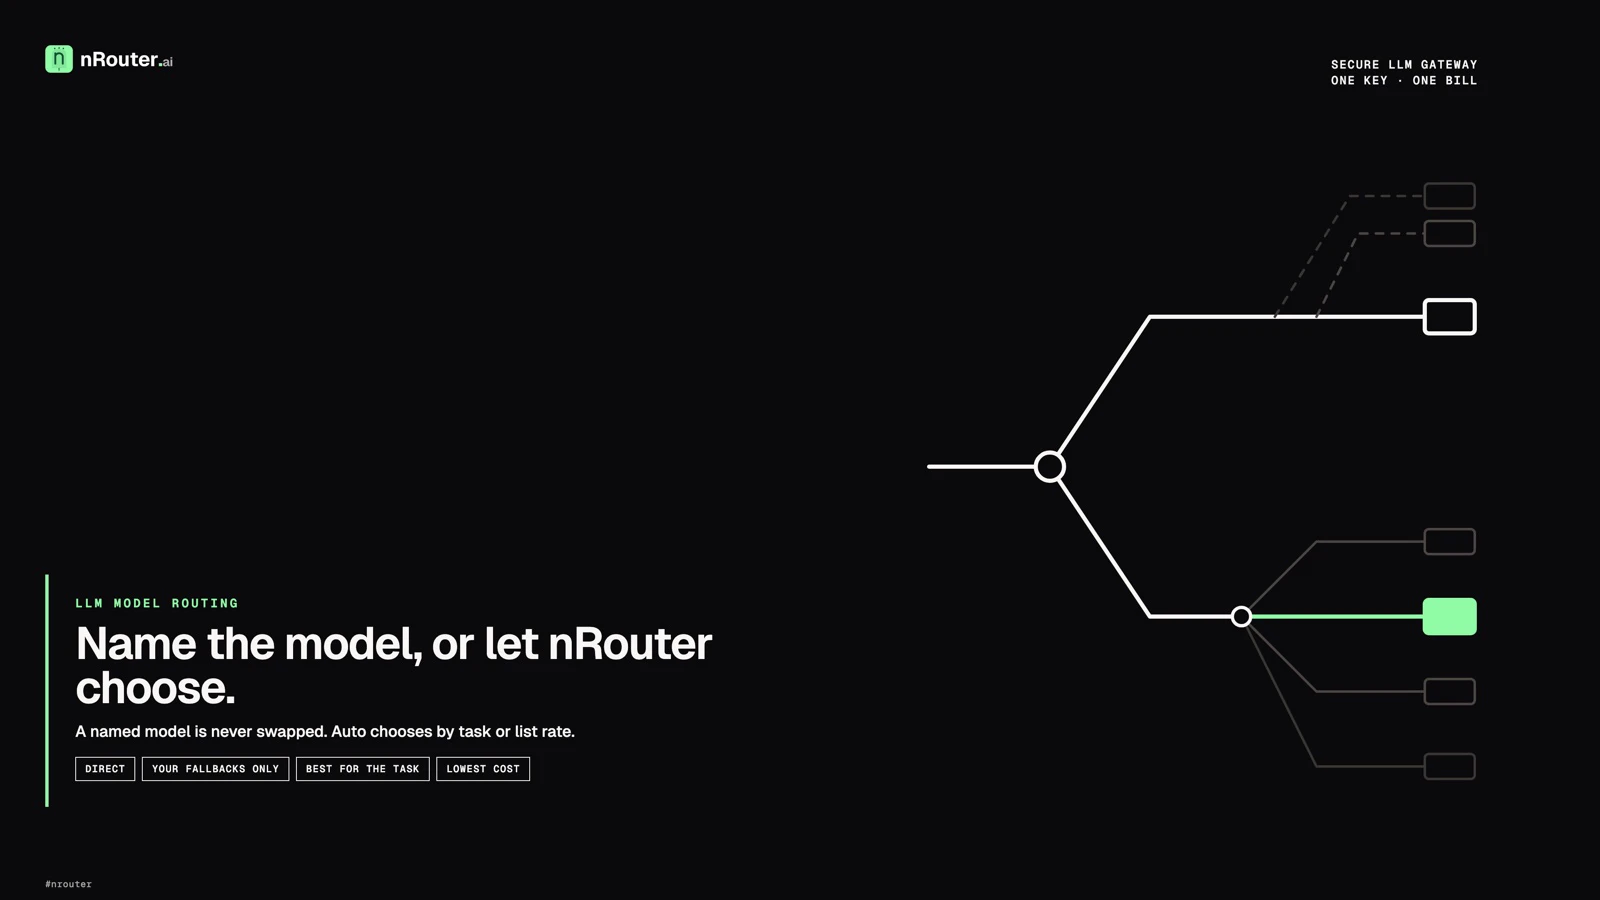
Two Ways to Ask for a Model: Direct, or nrouter/auto
nRouter gives you two ways to ask for a model. Name one and it is never swapped, except through a fallback you configured. Send nrouter/auto and nRouter chooses, by Best for the task or Lowest cost.
 nRouter Team
LLM Observability: Traces, Spend Logs, and Request Debugging
Inspect end-to-end inference traces, exact-cent spend rows, and multi-provider routing decisions under one request ID, with response headers on every call.
Budget Ceilings That Turn AI Spend Into a Forecast
A forecast is only a forecast if the worst case is bounded. Set hard dollar ceilings at the org, team, user and key scope, decompose next month's number into them, and know exactly which code your client gets when one bites.