


Cost-vs-Quality LLM Routing: Which Tasks Can Go Cheap
Quality is a property of a task, not of a model. Here is how to inventory your traffic by task, compare eligible models with nrouter/auto, prove each downgrade with an A/B test, and read the saving off the Cost vs Usage report.
Figure 1: Evaluate task quality and actual cost before changing model selection.
The short answer: route by task, not by request volume. Score each task against four questions, use nrouter/auto with the Lowest cost preference, then prove the downgrade with an A/B test before you move all of that task's traffic. Read the result as cost per 1,000 tokens on the Cost vs Usage report at
/[organization]/advanced-analytics/cost-vs-usage— not as a headline rate-card comparison.
The short answer
Use cost-aware routing — the core job of an LLM gateway — as one part of a broader LLM cost optimization strategy.
The most expensive habit in production LLM work is sending everything to the flagship "to be safe". It feels careful and it is quietly the largest line on the bill, because the traffic that is cheap to downgrade is usually also the traffic with the highest volume — classification, extraction, tagging, short rewrites, formatting. Those are the rows where a smaller model is genuinely indistinguishable, and they are the rows you are paying flagship rates for.
Fixing it is a four-move loop: inventory traffic by task, decide which tasks can go cheap, wire the routing so the change is a dashboard edit rather than a deploy, and prove the downgrade held quality before it becomes permanent. This guide walks each move with the exact page, field and header involved.
When you need this
Your bill grew faster than your traffic. Requests are up 20% and spend is up 90%. That gap is almost always model mix: a task quietly migrated onto a more expensive model, or a prompt grew and pulled its token count with it. The diagnosis lives in cost vs usage, which is specifically the chart that separates "more traffic" from "more expensive traffic".
You have one model name hardcoded in a dozen services. Every model change is a deploy, so nobody makes one, so the mix never improves. Use nrouter/auto for per-request model selection, or update a named model after an evaluation. Neither requires another provider SDK.
Somebody has proposed switching everything to the cheap model. This is the opposite error and it is worth naming, because it fails in a way that is much harder to see: the cheap model does not fall over, it degrades. Outputs get slightly worse in ways nobody catches until a customer does. The answer to both extremes is the same — decide per task, and measure.
What you need first
- An organization with credits. nRouter is credit-based and paid pay-as-you-go access requires a card: the minimum purchase is $5 at a 0% platform fee (a purchase charges exactly the credits bought). See Pricing.
- Owner or admin role. Router Settings is editable by owners and admins; members and viewers see it read-only with the save controls disabled. Roles are in Team Management.
- At least two models you are willing to compare, from the catalog at /models. Each entry shows provider, mode, max tokens, input and output cost, capabilities and health, so the candidate set is a filtering exercise rather than a memory test. Reference: Model Catalog.
NROUTER_API_KEYexported. Every block below runs as written againsthttps://api.nrouter.ai/v1.
export NROUTER_API_KEY="sk-nrouter-your-key-here"

curl -sS https://api.nrouter.ai/v1/models \
  -H "Authorization: Bearer $NROUTER_API_KEY" | head -c 300
Step 1 — Inventory traffic by task, not by model
There is no model that is better in the abstract, only a model that is better at something. So the unit of routing is the task, and the first job is to find out what your tasks actually are and how much each one costs you.
Open Advanced Analytics → Cost at /[organization]/advanced-analytics/cost, set the window to 30
days, and group by model. That gives you the shape of the bill. Then group by
tag or key to get closer to what the money is buying — a key per job or a
tag per feature turns "gpt-5.5 costs $3,100" into "ticket summarisation costs
$3,100", which is the sentence you can act on. Attribution mechanics are in
attribute LLM spend by team, customer and feature.
Write the result down as a table of tasks with a volume and a cost, then sort by cost. The candidates are the top rows.
| Task | Reasoning depth | Output verifiable? | Typical routing |
|---|---|---|---|
| Classify / tag / route | Low | Yes, mechanically | Cheap model |
| Extract fields from text | Low | Yes, against a schema | Cheap model |
| Short rewrite / reformat | Low | Yes, by eye | Cheap model |
| Summarise (short) | Medium | Partly | Mid model, A/B it |
| Multi-step reasoning or planning | High | No | Flagship |
| Complex code generation | High | Only by running it | Flagship |
Step 2 — Score each task against four questions
For any task, route it down to a cheaper model unless one of these is true.
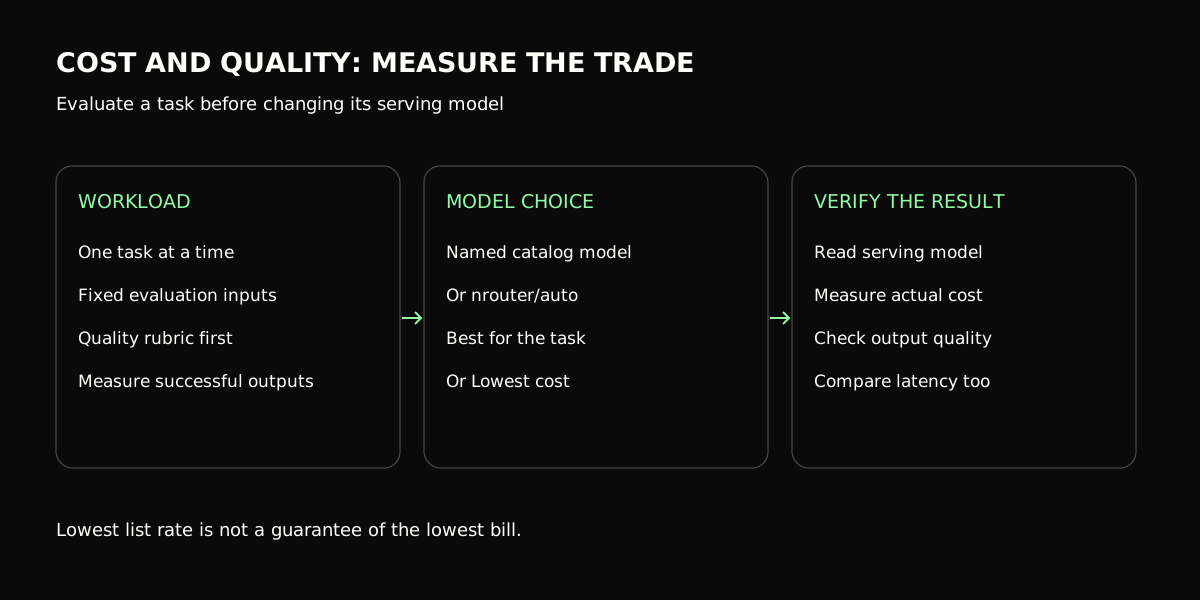
- Does it require multi-step reasoning or planning? Chains of inference are where small models diverge most sharply. Keep it on the flagship.
- Is the output hard to verify? If you cannot mechanically tell a good answer from a plausible-looking bad one, a cheaper model's mistakes reach production silently. Verifiability, not difficulty, is what makes a downgrade safe.
- Is it customer-visible and brand-critical? The cost of a slightly worse answer is not the token price.
- Is it long-context or multimodal in a way small models handle poorly? Check the max-tokens and capability columns on /models before assuming — context windows and modality support vary sharply inside a single provider's own line-up, as OpenAI's model list shows.
Four noes means a cheap-model candidate. Most extraction, classification and formatting work answers no four times, which is precisely why it is the biggest available saving.
One trap to name explicitly: a cheap model that needs three attempts is not cheap. Route on measured cost per successful output for your workload, never on the headline per-token rate. The published rate cards — OpenAI, Anthropic and AWS Bedrock each quote per-million-token input and output prices — are the input to that calculation, not the answer to it. Two models within a few cents per million tokens of each other can differ by an order of magnitude in retries on your particular prompts, and no rate card can tell you which.
Step 3 — Choose Direct or nrouter/auto
Name a catalog model when your evaluation has selected one for a task. Send nrouter/auto when you want nRouter to choose an eligible model per request. Smart Router aliases and Per-Model Weights were withdrawn on 2026-10-15; do not create an application-specific alias for these examples.
| Selection | What it does | What to measure |
|---|---|---|
| Named catalog model | Uses the model you selected, with only configured fallbacks | Quality, cost per successful result and latency |
| Best for the task | Uses smart model selection when available | Which model answered and whether quality holds |
| Lowest cost | Orders models fit for the task by equally weighted input/output list rates | Actual token mix and measured total cost |
Lowest cost is a list-rate preference, not a guarantee of the lowest bill or a latency preference. Set the organization's preference through the current routing setup guide, or override it per call with nrouter_optimize: "cost". Keep the candidate set within the models your organization and key allow.
from openai import OpenAI
import os

client = OpenAI(base_url="https://api.nrouter.ai/v1", api_key=os.environ["NROUTER_API_KEY"])
resp = client.chat.completions.create(
    model="nrouter/auto",
    messages=[{"role": "user", "content": "Summarise this ticket in one line: ..."}],
    extra_body={"nrouter_optimize": "cost"},
)
print(resp.model)
print(resp.choices[0].message.content)
The stock OpenAI SDK uses extra_body for gateway-specific fields; raw JSON clients put the field beside model. See the Chat Completions API and the upstream OpenAI client contract. Inspect x-nr-model and measured cost rather than assuming a preference proves a saving.
See current attempt limits and per-request controls.
Response caching is on by default for eligible repeated requests; nrouter_cache: false bypasses it for a controlled comparison.
Step 4 — A/B the downgrade before you commit
A routing decision is a hypothesis: "this task is fine on the cheaper model." Treat it like one. An A/B test splits live traffic between variants server-side, so the comparison runs on real production calls with no application change.
A/B definitions are account administration, not inference, so they are created
and driven from the dashboard rather than with a virtual key — the request body
below is what the Create test form submits to
POST https://app.nrouter.ai/api/ab-tests:
POST https://app.nrouter.ai/api/ab-tests?orgId=<your-org-uuid>
Content-Type: application/json

{
  "name": "gpt-5.4-mini vs gpt-4.1-nano for ticket summaries",
  "description": "Does the cheaper model hold quality on one-line summaries?",
  "variants": [
    { "name": "control",    "model": "gpt-5.4-mini",  "weight": 0.7 },
    { "name": "challenger", "model": "gpt-4.1-nano", "weight": 0.3 }
  ]
}
Start, pause and complete the test through the same route with an action query
parameter — POST /api/ab-tests?action=start&testId=<uuid>, and likewise pause,
stop, complete, update and delete. Read the test back with
GET /api/ab-tests?testId=<uuid>, which returns the definition together with
per-variant requests, latency, tokens, errors and spend; the individual recorded
rows are at GET /api/ab-tests?action=results&testId=<uuid>.
Selection happens in pre-flight, before guardrails and before the provider call. The bucketing hash is salted server-side, so a client cannot pin itself to its preferred variant by crafting request identifiers — which is what keeps the experiment honest. Settlement uses the model that actually served the call, so your spend numbers stay accurate per variant.
One constraint worth respecting: the credit reservation is sized for the model
your application originally asked for, so keep variants in the same pricing class
rather than pitting a flagship against something twenty times cheaper in a single
test. Tests move through draft → running → paused → completed, status changes
propagate in about 30 seconds, and completed is terminal — clone rather than
reopen. The design reasoning is in
deterministic A/B testing across model variants;
the field reference is A/B Testing.
Start at 70/30 rather than 50/50. If the challenger is worse, you have exposed 30% of one task's traffic, not half of it.
Step 5 — Read the saving as cost per 1,000 tokens
Total spend is the wrong number to judge a routing change by, because traffic moves at the same time and one masks the other. The number that isolates the change is a unit cost.
Open Advanced Analytics → Cost vs Usage at /[organization]/advanced-analytics/cost-vs-usage.
It reports cost per request and cost per 1,000 tokens, plotted against
requests and against tokens, with nRouter tool charges deliberately excluded so
the unit ratios stay clean. That is your before-and-after.
Then open Advanced Analytics → Benchmark at /[organization]/advanced-analytics/benchmark for the
model-by-model table on your own traffic: requests, tokens, spend, cost per 1k
tokens, cost per request, average and p95 latency, throughput, error rate and
cache-hit rate. A rate card tells you what a model charges; this tells you what it
costs you, including the retries. Advanced Analytics → Compare at
/[organization]/advanced-analytics/compare overlays the current window against the
previous one and calls out which models and keys moved the most.
Verifying it worked
- Confirm nrouter/auto resolves to an allowed model. Send one call through nrouter/auto and read the resolved model off the response, plus the cost headers:
curl -sS -D - -o /tmp/body.json https://api.nrouter.ai/v1/chat/completions \
  -H "Authorization: Bearer $NROUTER_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"nrouter/auto","messages":[{"role":"user","content":"ping"}]}' \
  | grep -i '^x-nr-'
python3 -c "import json;print(json.load(open('/tmp/body.json'))['model'])"
x-nr-request-cost carries the settled cost in USD and pairs with
x-nr-cost-status. When a call cannot be priced the cost header is absent and
the status reads unpriced — that is not zero, and a pipeline that treats it as
zero will under-report the very saving you are trying to measure.
- Check the split is real. With a running A/B test,
send a few dozen calls and count the resolved models. The distribution should
approach your weights; if every call resolves the same way, the test is not
runningor the application is not sending the experiment traffic. - Check unit cost, not total cost. Cost per 1,000 tokens on
/[organization]/advanced-analytics/cost-vs-usageshould drop for the task you moved. If total spend fell but unit cost did not, you had a quiet week, not a saving. - Check quality did not move. Whatever signal you already trust — a rubric, a downstream success rate, a human spot-check on 50 outputs — run it per variant before you promote the challenger.
- Check latency. There is no latency header — time each call on your own
clock and store the elapsed value beside
x-nr-request-id— and per-key averages and p95 are on the Key Usage report. A cheaper model that is slower may still be the right trade, but it should be a decision rather than a surprise.
What goes wrong
You routed on the rate card instead of on measured cost. A cheap model that retries, or that needs a longer prompt to get the same result, can cost more per successful output than the flagship it replaced. Measure cost per 1,000 tokens on your own traffic, on the Benchmark report.
You conflated routing with failover. They are different questions. Cost-vs-quality routing chooses which model should normally serve a task; a fallback chain handles only the eligible upstream delivery failures documented in Per-Request Options, before response bytes begin. It does not retry every 5xx or context-window rejection. Making your cheapest flaky model both the default and the fallback gives you the worst of both. See provider fallback chains.
You changed the model and the prompt in the same week. Then you cannot attribute the result to either. Change one thing; the whole point of a server-side split is that it isolates the variable for you. Managed prompts help here — see Server-Side Prompt Templates: Version, Roll Back, A/B Test.
You expected Lowest cost to lower your bill on its own. It picks the cheapest eligible model in a set you defined; if the set contains one model, or if your candidates are all expensive, nothing changes. Routing decides which model runs. Your ceilings are a separate control entirely — hard spend caps.
You named a concrete model and wondered why routing did nothing. Routing is opt-in. A concrete model name is served as asked, every time. Send nrouter/auto.
Try it
Before comparing routing cost and quality, eligible new accounts can receive $100 in promotional credits after email and phone verification, without a card. Promotional access has a restricted model set and spending limits; see current pricing and promotion terms.
Routing strategies, fallback chains, A/B tests, guardrails, prompt management and evals are included on every plan. nRouter sells one plan, pay as you go, with a 0% platform fee; a credit purchase charges exactly the credits bought ($5 costs $5.00, $100 costs $100.00) and nRouter absorbs card-processing costs. Usage settles at the served model's exact list price (0% markup). No subscription plan is sold (existing subscribers keep theirs). The reasoning behind our feature model is in Every Feature on Every Plan: No Fee, No Gate.
Load the $5 minimum — charging exactly $5.00 — then pick the single highest-volume, lowest-reasoning task you have, compare two allowed catalog models, and run a 70/30 test for a day. Start at app.nrouter.ai/signup, or compare two models by hand in the Playground before you wire anything. Bring a routing question to the nRouter community.
See also
Cost-aware routing is one component of LLM cost optimization, which also includes caching, prompt efficiency, retry limits, attribution, and hard spend caps.
Before production rollout, add hard LLM budgets and LLM observability to verify spend and routing outcomes.
- Cost vs Usage: Finding the Quietly Expensive Model — the chart that separates more traffic from more expensive traffic, and where a downgrade candidate first shows up.
- Deterministic A/B Testing Across Model Variants — how the server-side split stays honest, and why the bucketing salt matters.
- Provider Fallback Chains: Surviving an OpenAI Outage — the reliability axis this post deliberately keeps separate from cost and quality.
- Attribute LLM Spend by Team, Customer, and Feature — how to turn a model-shaped bill into a task-shaped one before you decide what to move.
- Hard LLM Spend Caps at Org, Team, User, and Key Scope — the ceilings that bound the downside while you experiment with the mix.
- Route Requests Automatically for Better Performance — the same routing machinery pointed at latency instead of price.
- Models — the live catalog with per-model cost, capabilities, context window and health.
Sources
Verified 2026-06-10; the external references were re-checked on 2026-08-23. Every strategy name, field, default and report path above comes from nRouter's own documentation, and the model names in the examples are illustrative — check the live catalog for what your organization can call today. If something has drifted, email hello@nrouter.ai and we will correct it.
- The published rate cards step 2 warns you not to route on alone: OpenAI, Anthropic, AWS Bedrock
- Context-window and modality differences inside one provider's line-up: OpenAI model list
- The Chat Completions contract the Python sample speaks: platform.openai.com
- Model selection, fallback attempts, wait budgets and caching: Router Settings
- A/B test creation, lifecycle and pre-flight selection: A/B Testing
- Cost, Cost vs Usage, Benchmark and Compare reports: Analytics and Reports
- Model catalog fields: Model Catalog
- Response headers and request shape: Chat Completions API
- Pay as you go and 0% platform fee: nrouter.ai/pricing
See also
Compare production routing policies and provider governance in the nRouter vs OpenRouter comparison.
Frequently asked questions
What is model routing and why does it matter?
The most expensive habit in production LLM work is sending everything to the flagship "to be safe". It feels careful and it is quietly the largest line on the bill, because the traffic that is cheap to downgrade is usually also the traffic with the highest volume — classification, extraction, tagging, short rewrites, formatting.
When do you need model routing?
Your bill grew faster than your traffic. Requests are up 20% and spend is up 90%.
What do you need before using model routing?
An organization with credits. nRouter is credit-based and paid pay-as-you-go access requires a card: the minimum purchase is $5, at a 0% platform fee.
Support engineer at nRouter, writing routing and performance guides from real customer workloads.
More from Guides
All posts →
Measure TTFT and Trace an LLM Request Step by Step in Python
Send an nrouter/auto request with the Python SDK, read routing, guardrails and cost from its headers, fetch the request back by id, print every gateway step with its start, end and duration, then measure TTFT and latency over N runs.
 nRouter Team
Ship Your First AI Feature: Signup to Production in an Afternoon
A step-by-step path from a funded nRouter account to a production LLM call with a spend ceiling on it — create a scoped key, point your existing OpenAI client at one base URL, cap the key, and verify the cost header came back.
Latency Routing and Automatic Failover Without Retry Code
Measure candidate model latency, configure explicit fallbacks, understand the gateway attempt budget, and verify the result on your own p95.