


Cut LLM Costs by Routing, Not by Rewriting Your App
Routing is the one cost lever you can pull from a dashboard. Compare eligible models, use Best for the task or Lowest cost, and measure what a request costs without touching a line of application code.
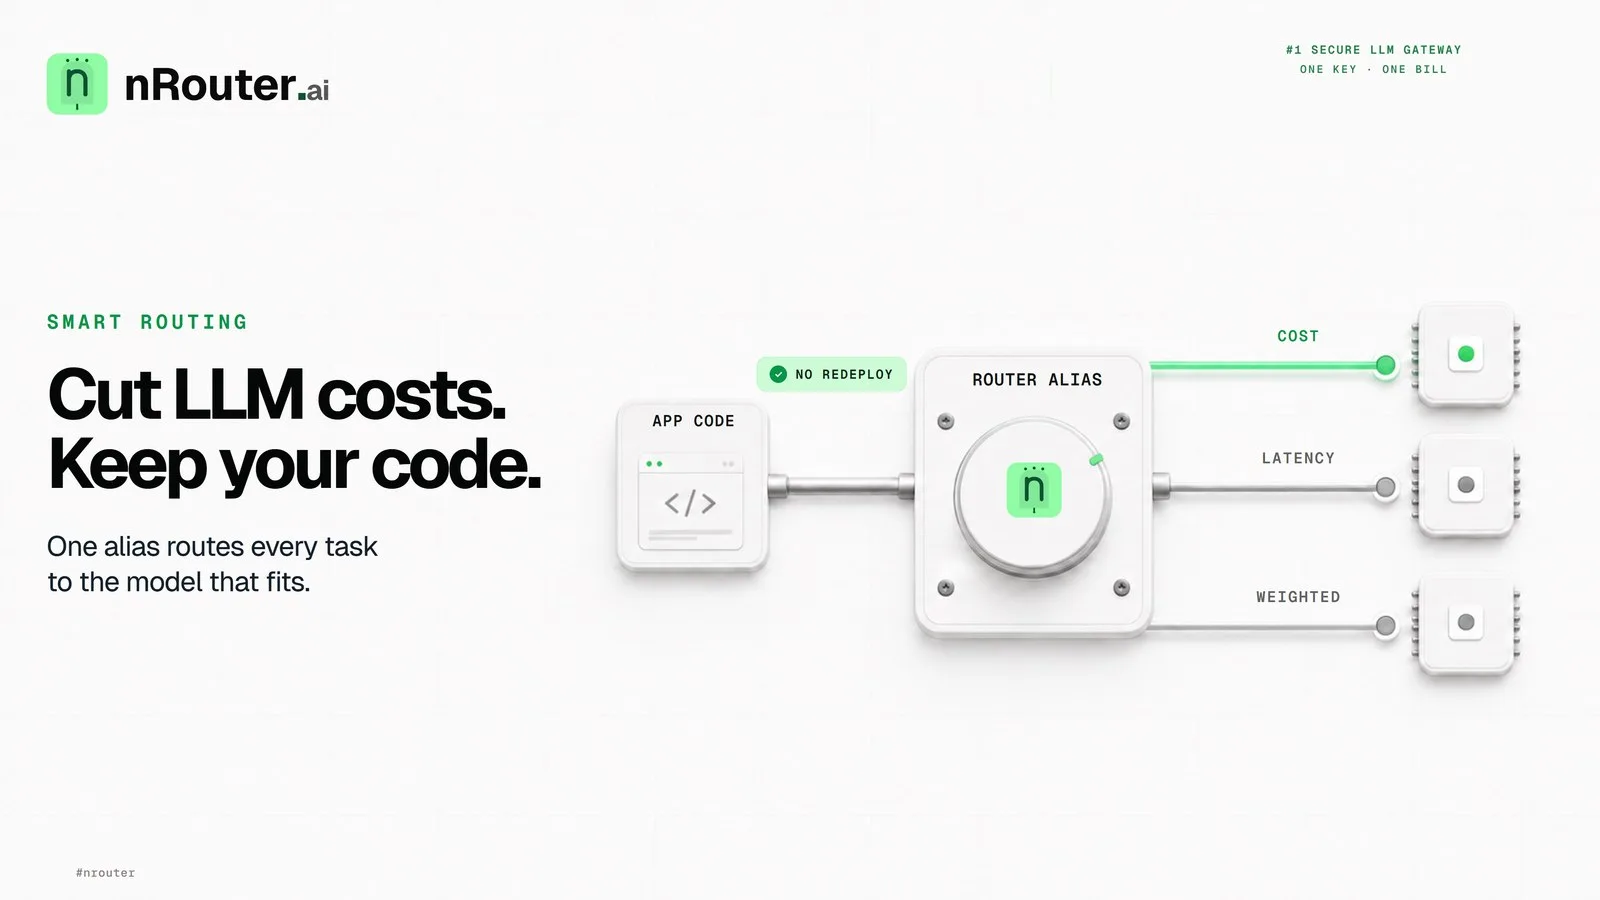
The Direct Answer: Smart routing can reduce cost when eligible models meet the quality needs of the task. Send nrouter/auto for Best for the task or Lowest cost selection, or name a catalog model directly. Measure the actual result; no saving percentage is guaranteed.
Figure 1: Smart Routing Data Plane — Direct model access or eligible automatic selection, with configured fallbacks and serving-model response headers.
What it does
Smart routing is one part of a broader LLM cost optimization strategy that also covers caching, budgets, retries, and cost attribution.
nrouter/auto asks the gateway to choose an eligible model. Best for the task uses smart selection when available; Lowest cost orders models fit for the task by list rate. A named model stays Direct unless an explicitly configured fallback handles an eligible upstream refusal.
The one-paragraph version: the cheapest large saving in most LLM bills is not a discount, it is the fact that a large fraction of calls are being served by a model far better than the task requires. Fixing that by hand means per-model branching scattered across a codebase, which is why it usually does not get fixed. Automatic model selection moves the candidate choice into the gateway, which makes it cheap enough to actually change — and cheap enough to change back.
This post is about routing choice as a cost lever. It is not the provider-breadth argument (one key, every provider), not the bounding argument (budget ceilings), and not the reseller argument (per-customer billing). Routing is the lever that changes what a call costs; those are the levers that change what you can see, bound and re-bill.
The job it does for you
Before. Every call goes to one model, chosen once, usually the best one available at the time — because choosing the best one is the decision that cannot be criticised. Then the workload diversifies. Classification, extraction, JSON reformatting, a cheap first pass before a human reviews it: all of it billed at flagship rates, all of it high volume, none of it requiring the flagship.
Everyone knows the fix. Almost nobody ships it, and the reason is not laziness — it is that "use a smaller model for the easy stuff" cashes out as a second provider SDK, a second credential, per-call branching logic in three services, and a permanent maintenance obligation, in exchange for a saving nobody has measured yet. The expected value of that trade is genuinely unclear, so it stays on the backlog and the premium-everything default persists.
After. The branching lives in one place — nRouter's LLM gateway — outside your code. A call names nrouter/auto or a catalog model. The response identifies the serving model and cost, so an evaluation measures what happened instead of treating a routing preference as a saving.
The structural change is that the cost of trying a routing change drops to near zero, and that is what makes the saving reachable. A change that costs two sprints has to be justified in advance. A change that costs an evaluated selection change can be tested.
How it works
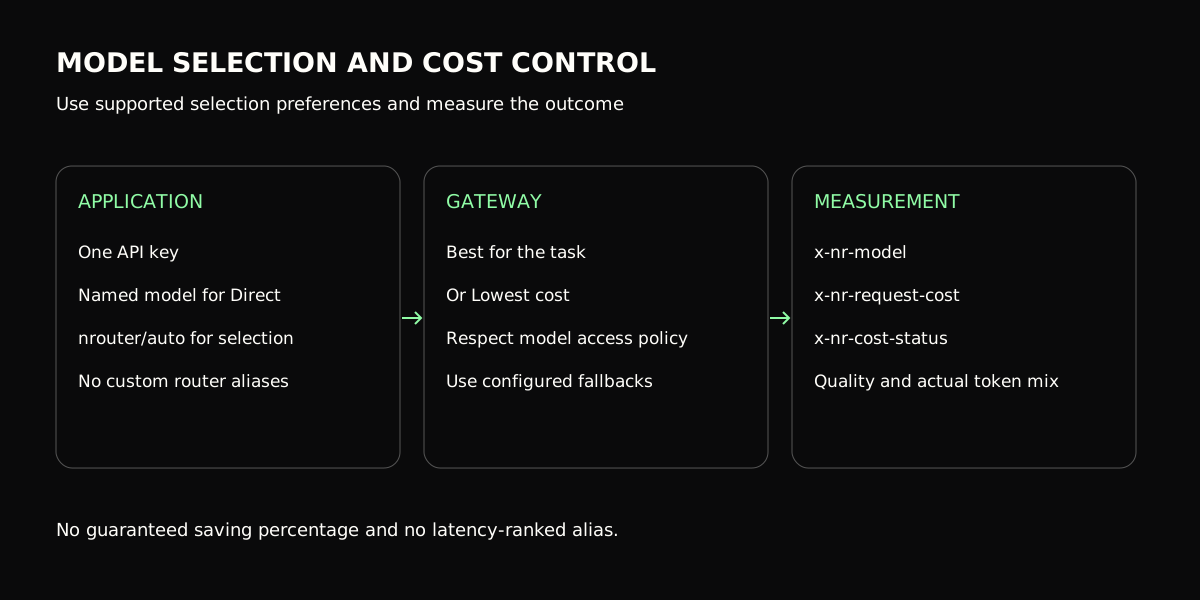
Use a named catalog model for Direct requests or nrouter/auto for per-request selection. Smart Router aliases and Per-Model Weights were withdrawn on 2026-10-15. The current auto preferences are Best for the task and Lowest cost, not Latency or Weighted strategies.
| Choice | Behavior | Important limitation |
|---|---|---|
| Direct | Calls your named model | Other models require configured fallbacks |
| Best for the task | Uses smart model selection when available | Measure quality rather than assuming every task improves |
| Lowest cost | Orders eligible models by equally weighted input/output list rates | Actual token mix determines the bill |
Routing is opt-in: a request that names a model does not become a latency-ranked pool. The auto candidate set is constrained by model access policy. If no permitted model can serve the request, the gateway refuses instead of treating an arbitrary provider as interchangeable.
Read x-nr-model to learn what answered and x-nr-request-cost for a priced call. An absent cost is unpriced, not zero; cost honesty explains that distinction.
A Direct request uses the named model and only tries other models through a saved fallback list or nrouter_fallbacks on that request. A request to nrouter/auto has its own bounded selection and fallback loop. Fallback advances only when a provider cannot take the request: upstream 429, 503 or Anthropic 529, a misconfigured provider deployment returning 401 or 404, an unopened connection, or a timeout before the first response byte. Upstream 500, 502, 504, context-window refusals, and errors after response bytes arrive are not general fallback triggers.
A fallback provider refusal before generation is not the same as resending a request after a client lost the response. The former is part of one bounded chain; the latter can create another billable generation. See provider fallback chains.
Set it up
import os
from openai import OpenAI

client = OpenAI(base_url="https://api.nrouter.ai/v1", api_key=os.environ["NROUTER_API_KEY"])
raw = client.chat.completions.with_raw_response.create(
    model="nrouter/auto",
    messages=[{"role": "user", "content": "Classify this support ticket."}],
    extra_body={"nrouter_optimize": "cost"},
)
print(raw.headers.get("x-nr-model"))
print(raw.headers.get("x-nr-request-cost"))
print(raw.headers.get("x-nr-cost-status"))- Review permitted models in the catalog guide.
- Choose Best for the task or Lowest cost through the routing setup.
- Set explicit fallbacks only where you accept the alternatives.
- Read the serving model, cost status and attempts for real traffic.
- Compare quality and cost before changing the whole workload.
See current attempt limits and per-request controls.
What to route down, and what not to
Routing saves money only where a cheaper model is genuinely sufficient, so the unit of the decision is the task, not the request volume. A useful four-question filter — route the task to a cheaper model unless one of these is true:
- Does it require multi-step reasoning or planning?
- Is the output hard to verify, so a wrong answer slips through unnoticed?
- Is it customer-visible and brand-critical?
- Is it long-context or multimodal in a way small models handle badly?
Four "no" answers make it a candidate. Most extraction, classification, tagging and short-rewrite work answers "no" four times, and that work is usually the high-volume half of the bill. The framework in full, with the task-to-tier mapping, is cost-vs-quality LLM routing: which tasks can go cheap.
The trap on the other side: a cheap model that needs three attempts to produce a usable answer is not cheap, and a headline per-token rate does not tell you that. Route on measured quality-per-dollar for your workload, which means the next section is not optional.
Two provider-side levers sit underneath this decision and are worth exhausting first, because neither requires a quality judgement at all. Repeated prompt prefixes are billed below fresh input on both OpenAI and Anthropic, which rewards putting your stable system prompt and retrieved context in front of the volatile part. And work that does not need an answer now can go through an asynchronous batch path at half the standard rate on both — OpenAI's Batch API documents a 50% discount within a 24-hour window, Anthropic's Message Batches API the same 50% with most batches finishing inside an hour. Neither changes which model answers, so neither carries the risk this section is about.
Prove the downgrade before you commit it
A routing change is a hypothesis — "task X is fine on the cheaper model" — and shipping it to 100% of traffic is testing in production with no control group. The sequence that avoids that:
1. pick one task currently served by the flagship
2. split its traffic deterministically: incumbent (A) vs candidate (B)
3. fix the quality signal BEFORE you look at the result
4. compare quality and cost-per-request across the two cohorts
5. if B holds quality at lower cost, move task X to B and re-measure next period
Deterministic is the load-bearing word: the same input must land in the same cohort every time, or you cannot attribute a difference to the model rather than to the sample. Deterministic A/B testing across model variants is the mechanics, and experiment configuration is separate from the auto selection preference.
This step is also what converts a routing change from a claim into a number you can put in a document: not "we think we can save money" but "we moved ticket classification to model B, the quality signal held, and cost per request on that task fell by a measured amount."
Worked example with numbers
This is an illustrative example built on assumed rates, not a platform claim, and not a saving nRouter promises. Substitute your own measured cost per call from x-nr-request-cost and your own traffic mix — the arithmetic is what transfers.
Assume 1,000,000 chat calls a month, all currently served by a flagship model at an effective $9.00 per 1,000 calls for this workload's average prompt and completion length. Assume a review of the tasks finds 70% of calls are classification and short extraction, which a smaller model serves acceptably at an assumed $1.20 per 1,000 calls.
| Slice | Calls/mo | Assumed rate / 1K | Monthly |
|---|---|---|---|
| Before — all flagship | 1,000,000 | $9.00 | $9,000 |
| After — routine (70%) | 700,000 | $1.20 | $840 |
| After — flagship (30%) | 300,000 | $9.00 | $2,700 |
| After — total | 1,000,000 | — | $3,540 |
In this constructed mix the reduction is about 61%. That figure is a property of the assumptions, not of the product. Change the mix to 30% routine and the same arithmetic yields about 26%. Change it to a workload that is entirely hard reasoning and it yields nothing at all, correctly — there is no cheaper model that is sufficient, so there is nothing to route.
Which is why the honest instruction is the one in the A/B section: read the cost header for a week before, make the change, read it for a week after, and use that number. The two rates above should come from the models page for your actual candidates, and the before-and-after should come from your own responses.
The two cost lines routing does not touch
Routing changes what a call costs. Two other lines on the same bill move independently, and it is worth separating them so a saving is not double-counted.
The platform fee. nRouter sells one plan, pay as you go, at a 0% platform fee, and usage settles at the served model's exact list price with 0% markup. Because a credit purchase charges exactly the credits bought, there is no platform fee added on top of your model spend, and no subscription plan is sold (existing subscribers keep theirs). In the worked example, spending drops from $9,000 to $3,540 with zero fee overhead on either amount.
Response caching. Caching is on by default for identical non-streaming requests (streaming requests are not cached); your organization can switch it off in Router Settings, and a single request can skip it by sending "nrouter_cache": false in the request body. It is not a line on this bill: a cache hit is still metered and billed like any other request, so what it changes is latency, not what you pay. It does interact with routing, because a cached response was produced by whichever model served the original call.
Neither of these is routing. Counting a fee reduction and a routing reduction as one number is the most common way a savings figure ends up indefensible in a review.
What it costs
Routing is not a paid feature, and neither is anything else: nRouter sells one plan, pay as you go, at a 0% platform fee; a credit purchase charges exactly the credits bought ($5 costs $5.00, $100 costs $100.00), nRouter absorbs card-processing costs, and usage settles at the served model's exact list price with 0% markup. Every dollar saved on upstream inference is a full dollar saved on your bill; details are on the pricing page.
No subscription plan is sold (existing subscribers keep theirs). Every customer gets access to the full platform capabilities without recurring plan fees or feature gating.
Getting started requires adding a card and loading the $5 minimum purchase, which charges exactly $5.00 for $5.00 in credits.
Where it fits with the rest of the platform
- Finding what to route. Routing without measurement is guessing at which tasks are expensive. Cost vs usage separates the quietly expensive model from the obviously popular one.
- Routing shapes. Operator-controlled routing is one of three shapes on the market, and the other two make different trades — LLM routing strategies 2026.
- Latency measurement. Choose a primary using workload measurements and configure suitable fallbacks — the latency and failover guide explains the reliability trade.
- Agent pipelines. A routing decision inside an agent loop compounds across steps, which changes how you evaluate it — LLM routing for AI agent pipelines.
- Bounding what is left. Routing lowers the expected case; a ceiling bounds the worst one — budget ceilings that turn AI spend into a forecast.
Limits and what it will not do
- It cannot make a hard task cheap. If every call in a workload genuinely needs the flagship, routing saves nothing, and the correct output of the exercise is that finding.
- It does not judge quality for you. Nothing in the routing layer knows whether the cheaper model's answer was good enough. That is what the A/B step and your own quality signal are for.
- A concrete model id is never re-routed. This is a safety property, and it also means automatic selection requires nrouter/auto; a named model uses only configured fallbacks.
- Fallback only handles documented upstream refusals before response bytes. It does not recover from every 5xx, context-window refusal, or interrupted stream.
- A new application request can create another charge. A bounded gateway fallback chain settles against the serving model; resending a request from your client after losing a response can create another generation.
- Lowest cost uses list price, not measured quality-per-dollar. A model that is cheap per token and needs three attempts will still be picked. That is a reason to curate the candidate set carefully rather than to add every model to it.
- SOC 2 Type II is in progress, not certified. The trust page carries the current posture.
Try it
Create an account at signup, load the $5 minimum (a purchase charges exactly the credits bought, $5 for $5.00), and do the smallest version of the whole argument: pick your highest-volume routine task, compare a named model with nrouter/auto using the Lowest cost preference, send the same fifty inputs through it and through your current model, and compare x-nr-request-cost and the outputs side by side. The quick start gets the key working; Router Settings documents supported selection and fallback behavior. An afternoon produces a number you can defend.
See also
For a complete framework covering model selection, caching, retries, attribution, and hard budgets, read the LLM cost optimization guide. Teams evaluating an OpenRouter alternative for production routing can compare nRouter with OpenRouter.
- Cost-vs-quality LLM routing: which tasks can go cheap — the task-level decision framework behind which calls to route down.
- Deterministic A/B testing across model variants — how to prove a downgrade held quality before you commit all the traffic.
- LLM routing strategies 2026 — where operator-controlled routing sits against benchmark-anchored and ML-classifier routers.
- Provider fallback chains: surviving an OpenAI outage — the reliability axis and the difference between a bounded chain and a new client request.
- Cost vs usage: finding the quietly expensive model — how to pick which task to route before changing model selection.
- Cutting LLM costs: what published discounts actually save, and where the model is an assumption — the same lever stacked with batch and caching, and where the reservation figure stops being a published rate.
- The models page — the live catalog and rates your candidate set is built from.
Sources
Verified 2026-08-23. If any linked page has changed since, email hello@nrouter.ai and we will correct this post.
- nRouter plans and fees: nrouter.ai/pricing — pay as you go at a 0% platform fee, $5 minimum purchase, with usage settled at the served model's exact list price.
- nRouter Router Settings documentation: nrouter.ai/docs/guides/router-settings — supported selection, configured fallbacks, attempt budgets and caching.
- nRouter live catalog: nrouter.ai/models — the authoritative model list and rates behind any candidate set.
- OpenAI API pricing: OpenAI rate card — published per-model rates; the worked example's rates are assumptions, not quotes from this page.
- Anthropic pricing: anthropic.com/pricing — published per-model rates for the Claude family.
- AWS Bedrock pricing: aws.amazon.com/bedrock/pricing — Bedrock is live on nRouter and AWS publishes its own rates.
- OpenAI prompt caching: platform.openai.com/docs/guides/prompt-caching — the discounted rate on a repeated prompt prefix.
- OpenAI Batch API: platform.openai.com/docs/guides/batch — the published 50% discount and its 24-hour completion window.
- Anthropic prompt caching: platform.claude.com/docs/en/build-with-claude/prompt-caching — the same lever on the Claude family.
- Anthropic Message Batches API: platform.claude.com/docs/en/build-with-claude/batch-processing — the published 50% cost reduction, with most batches finishing in under an hour.
OpenAI, Anthropic and AWS are trademarks of their respective owners. nRouter is not affiliated with or endorsed by them. All claims above are sourced from their public pricing or documentation on the date shown.
Frequently asked questions
What does nRouter do for reduce LLM costs with routing?
nrouter/auto selects an eligible model per request using the configured preference. Measure quality and actual cost before promoting a change.
What problem does nRouter solve for reduce LLM costs with routing?
Before. Every call goes to one model, chosen once, usually the best one available at the time — because choosing the best one is the decision that cannot be criticised.
How does nRouter work for reduce LLM costs with routing?
Choose a named model or nrouter/auto with Best for the task or Lowest cost.
Senior SEO engineer at nRouter, focused on search, AEO, and content performance.
More from Product
All posts →
Two Ways to Ask for a Model: Direct, or nrouter/auto
nRouter gives you two ways to ask for a model. Name one and it is never swapped, except through a fallback you configured. Send nrouter/auto and nRouter chooses, by Best for the task or Lowest cost.
 nRouter Team
LLM Observability: Traces, Spend Logs, and Request Debugging
Inspect end-to-end inference traces, exact-cent spend rows, and multi-provider routing decisions under one request ID, with response headers on every call.
Budget Ceilings That Turn AI Spend Into a Forecast
A forecast is only a forecast if the worst case is bounded. Set hard dollar ceilings at the org, team, user and key scope, decompose next month's number into them, and know exactly which code your client gets when one bites.